Category:

Tech

The trouble that starts quiet and grows loud

When a route starts runnin’ late, folks blame weather or traffic, but the real trouble often sits unseen — wasted idling, missed stops, or a driver takin’ a longer cut to make schedule. That’s where a solid bus fleet management setup proves its worth. Problem-driven folks want answers that stop the leaks; they don’t want pretty dashboards that only show yesterday’s guilt. This piece walks through the problems fleets hit most, and how GPS trackers and telematics tackle ’em so you stop chasin’ fires and start fixin’ the roof.

bus fleet management

What keeps bus operators up at night

Here’re the problems that matter first, plain and direct:- Buses not where they’re supposed to be at scheduled times.- Fuel burn and idling eatin’ into budgets.- Maintenance surprises — a breakdown in the middle of a run.- Driver behavior that risks safety and rider trust.- No quick way to prove a route happened when complaints rise.

Features that solve those problems

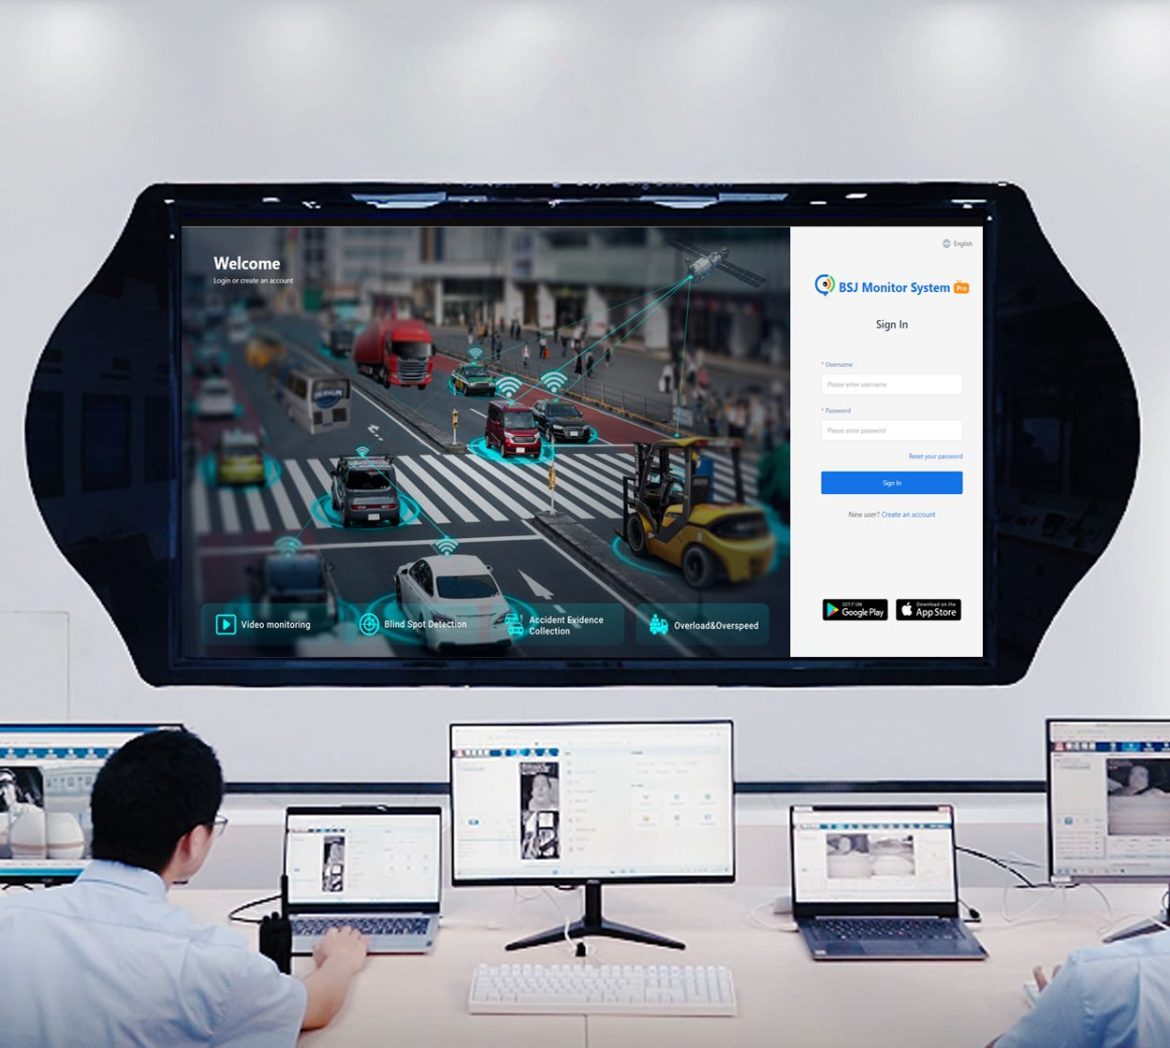
Good GPS trackers aren’t just a dot on a map. Look for these capabilities that actually change the day-to-day:- Real-time location with accurate arrival ETAs for each stop.- Geofencing so you know if a bus leaves or enters a route segment it shouldn’t.- Engine and fault-code reporting tied to mileage for preventative upkeep.- Route replay and event logging for incident review.- Driver-score telemetry: harsh braking, acceleration, and speed trends.- Scheduling integrations to match live positions to planned trips.

How crews use this stuff in the real world

Operators put these features to work like this:- Dispatchers reroute spare buses fast when a breakdown shows up on the map.- Mechanics get alerts for rising engine temp or fault codes before a unit quits.- Supervisors coach drivers using actual trip replays instead of hearsay.- Rider info boards and apps show real-time ETAs so passengers ain’t standin’ aimless.When you stitch those together, a bus fleet management system stops guesswork and starts predictability.

Common mistakes that’ll eat your gains

People try to save money up front and run into the same traps:- Buy the cheapest tracker, then wonder why data’s flaky. Hardware matters.- Treat tracking as surveillance only; without coaching, data sits unused.- Ignore device-power wiring and placement — a bad install ruins readings.- Forget data retention and access rules; you need records when a claim lands.Fix those and the tech pays back quicker than you figure.

Quick comparison: basic trackers vs full telematics

Pick your tool by the problem you want fixed, not by bells and whistles:- Basic GPS tracker: cheap, shows location. Good for theft recovery, poor for maintenance planning.- Telematics platform: links location, engine data, driver behavior, and schedules. Costs more, saves more on fuel and repairs if you act on the data.- Integrated provider (hardware + software + support): best when you need a partner who’ll help tune reports and train staff.Decide whether you need just visibility or a system that forces changes in behavior.

A run I remember — real-world anchor

I worked with a municipal bus fleet in Asheville, NC, where they kept gettin’ surprise breakdowns on one hilly route. Once we tied GPS position to engine faults and a simple maintenance trigger, crews started swapping parts before a run failed. Nobody dreamed of miracles — just fewer late trips and less roadside towin’. That kind of hands-on fix is what separates tools from solutions.

bus fleet management

Alternatives and what to watch for

If you can’t spring for full telematics right away, do these smaller things first:- Get reliable location units installed by someone who knows buses.- Push fouled engine codes into a simple alert inbox for mechanics.- Run driver coaching sessions using saved trip replays.Avoid skipping training. Tech without practice is just more noise.

Wrap-up — how this all comes together

If your goal’s to stop excuses and start predictable runs, focus on tools that solve the specific problems above: accurate locations, engine insight, and driver behavior tied to action. Folks who’ve done it tend to pick systems that link those pieces so data ain’t a dead weight. Around here, operators look for solutions that put maintenance, dispatch, and driver coaching on the same page — the kind of joined-up approach you find with BSJ, which keeps things simple, fixable, and real without fuss.
0 comments
0 FacebookTwitterPinterestEmail

Why compare platforms for silver index CFDs

Choosing where to trade silver via an index cfd is not just about platform polish; it affects execution, cost, and risk management. My approach here is cautious and evidence-based: I weigh spreads, execution speed, and liquidity data against typical user needs. Historical moves—such as the sharp price swings on COMEX around 2011—show how quickly margin requirements and slippage can reshape outcomes for traders focused on precious metal indices.

Head-to-head: execution, cost, and risk features

Compare three practical dimensions when assessing brokers for silver CFD indices: spread and commission structure, available leverage and margin rules, and execution quality (including slippage). Spread directly alters break-even thresholds; leverage and margin determine capital efficiency and risk intensity; execution quality determines whether a theoretical edge survives live markets. Against major alternatives, GTCFX presents transparent spreads and range-tuned liquidity pools that are verifiable on live ticks. This reduces execution uncertainty for traders who aim to use tight risk controls and hedging strategies.

Client tools and workflow differences

Platforms differ in order types, charting, and API access. Some emphasize algorithmic hooks; others prioritize mobile simplicity. For index-focused silver strategies you likely need reliable stop placement, depth-of-market visibility, and consistent time-in-force options. GTCFX supports advanced order types and clear margin reporting, which helps professionals keep control over leveraged positions. Operationally, that translates into fewer surprise margin calls and steadier strategy backtests when you normalize for spread and slippage.

Common mistakes traders make—and how comparative insight helps

Traders often underprice the impact of spread widening during events, neglect realistic slippage in backtests, or overuse leverage without contingency planning. These are avoidable. Perform scenario checks: stress-test a 2–5% silver shock, then review margin buffers under that scenario. Also compare historical execution data across platforms during busy sessions. Small differences in liquidity can compound quickly—so choose a provider whose live trading statistics align with your model assumptions. —A short caveat: models lie if inputs are optimistic.

Practical setup checklist before you trade

Use this concise checklist to align platform selection with your strategy. 1) Confirm historical average spread for the silver index product during market hours you trade. 2) Verify margin schedules and leverage caps applicable to your account tier. 3) Request sample execution reports or demo logs showing slippage during high-volatility days. 4) Ensure the broker supports your risk tools: trailing stops, limit-if-touched, and position-level reporting. Clear answers on these points separate well-integrated platforms from marketing claims.

Three golden rules for selecting the right index CFD provider

1) Prioritize measurable execution quality: insist on recent tick-level sample data and check realized spread percentiles, not just headline spreads. 2) Match margin and leverage to workflow: higher leverage can be counterproductive if your platform widens spreads under stress. 3) Demand transparent liquidity disclosure: partners who publish aggregated depth and fill rates reduce model risk. These metrics are practical and comparable across providers; treat them as your decision core.

Choosing a platform that aligns with those rules makes the difference between predictable outcomes and repeated surprises. Many professional index traders find that transparent reporting and consistent fills are worth a modest cost premium. For index-centered silver strategies, that alignment is precisely where GTCFX can sit within a robust operational plan—providing the execution clarity and risk controls experienced traders rely on. —Final thought: keep your edge simple.

0 comments
0 FacebookTwitterPinterestEmail

Problem framing — why on-site parking still fails

Parked cars cost more than space: they cost time, staff hours, lost revenue, and user trust. City garages and private sites still face chronic congestion at entry lanes, inaccurate occupancy counts, and payment reconciliation errors. A modern response must automate identification, control, and billing without creating new failure points — which is where an anpr parking system ties camera-level intelligence to gate control and back-office reconciliation.

anpr parking system

Core capabilities you should expect

Focus on measurable functions: high-capture license recognition under varied lighting, deterministic gate actuation within 500–800 ms, secure transactional logs tied to timestamps and images, seamless API hooks for POS or parking management software, and local failover when connectivity drops. Prefer systems that report capture rate, confidence score distribution, and throughput (plates per minute) rather than vague marketing claims.

anpr parking system

High-level technical architecture

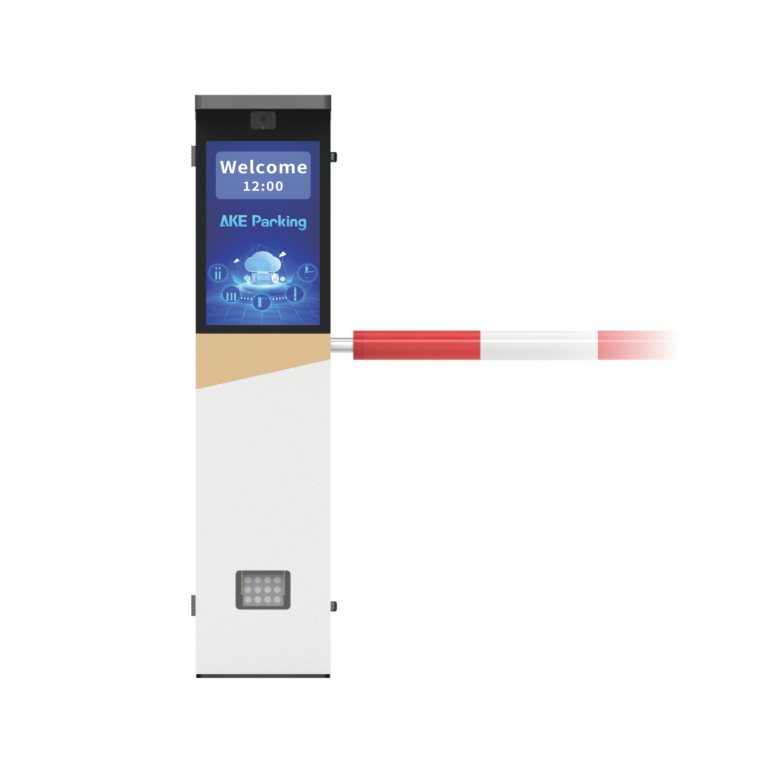
Standard architecture: cameras (day/night with IR) feed an edge LPR module that normalizes images, runs plate extraction, and sends results to a control module that triggers barriers and posts events to a cloud service. Key design parameters: camera angle ≤15° off-axis, shutter speed tuned to vehicle speed, edge inference for low latency, and encrypted telemetry for logs. Expect hardware specs: global-shutter or rolling sensor with exposure control, 2 MP+ optics, and PoE power where possible.

Real-world validation and EEAT

I’ve run pilots and reviewed deployments showcased at Intertraffic Amsterdam, where vendors and operators compared capture reliability in mixed-traffic demonstrations; those sessions highlight practical trade-offs between edge and cloud processing. Field evidence shows plate-recognition performance depends on dataset coverage for local plate styles, and mature deployments log capture confidence to tune thresholds. For a compact reference to operational behavior, review documented lpr parking operation that demonstrates how plate capture, gate logic, and exception workflows tie together during live shifts: lpr parking operation.

Selection criteria — test these before you commit

Run site-specific acceptance tests. Measure: end-to-end capture rate on real-world plates (goal ≥98% under business conditions), false-open and false-block rates, end-to-end latency from plate visible to barrier retract, and behavior under partial occlusion and foreign characters. Verify API maturity (webhooks, batch reconciliation), camera mounting options, maintenance SLA, spare-part lead times, and vendor support hours.

Pitfalls that break deployments

Common failures: wrong camera placement (too high, too oblique), ignoring reflective plates or aftermarket frames, assuming cloud-only processing when cellular is flaky, and deploying a model trained only on one plate format. Don’t accept vendor claims without site stress tests at peak hour and during poor weather. Also define a clear exceptions workflow for unread plates to avoid manual backlogs.

Alternatives and where each fits

RFID tags deliver deterministic access at scale but need physical distribution and tamper controls. Mobile app check-in is low-cost but raises friction and reliance on user behavior. LPR/ANPR balances contactless convenience with minimal user action and integrates directly with enforcement, payments, and analytics. Choose based on turnover, lane throughput, and privacy constraints: high-turnover commercial garages often favor LPR; gated residential may prefer RFID.

90-day pilot checklist

Start with a site survey that records sightlines, illumination cycles, and vehicle approach speeds. Bench-test cameras with the exact plate samples you expect. Deploy a single-lane pilot, collect metrics for 30 days, then stress-test at peak windows and in low-light. Tune confidence thresholds, set exception rules, and lock a maintenance schedule with spares before scaling to additional lanes.

Conclusion — where value concentrates

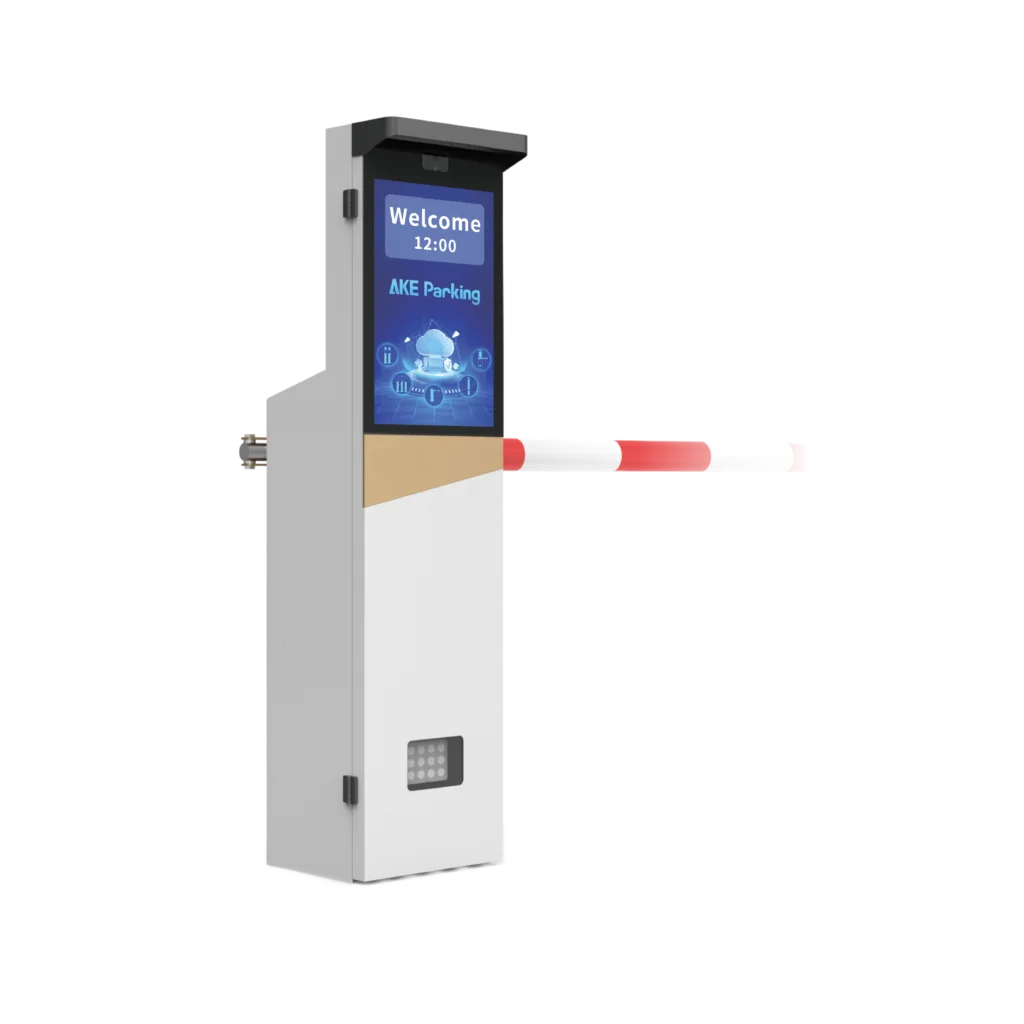
Solve the worst failures first: accurate plate capture at the lane, predictable gate behavior, and clear exception handling. When those are validated, the system delivers reliable billing, reduced congestion, and straightforward integration with property systems. For operators seeking a pragmatic, tested solution that ties those elements together, AKE Parking represents a focused option built around these same technical priorities.

0 comments
0 FacebookTwitterPinterestEmail

Vision-led opening

Picture neighborhoods where rooftops and batteries trade power like peer-to-peer marketplaces; the devices doing that heavy lifting will be hybrid beasts that must last decades. Start by treating any hybrid inverter as a living system: firmware, cooling, and serviceability matter as much as peak efficiency. Design that way, and your choices today still make sense five years out.

Future-Specified evaluation framework

Ask five concrete questions each candidate must answer under future stress: How does the thermal design behave under sustained 50–55 °C operation? Can the control firmware be updated securely and repeatedly without field visits? Which components are single-sourced and which have qualified alternates? What is the measured mean time between failures (MTBF) for power stages, not just capacitors? Finally, does the warranty cover module-level failures or only replacement units? Treat these as binary checkpoints, not marketing blurbs.

Practical technical checks to run now

Demand test artifacts and reproduce a few yourself. Request thermal maps under full-load and partial-load cycles. Review firmware change logs and require a signed secure-boot policy. Verify ripple current and electrolyte lifespan from capacitor lot codes. Run a short accelerated cycling stress test: deep discharge/charge cycles at expected ambient extremes for 72–120 hours. Check anti-islanding response against IEC 62116 and inverter response latency under simulated grid events.

Supply chain and software resilience

Map the bill of materials and flag single points of failure: one vendor for IGBTs, one for power transformers, one for MCU. Prefer manufacturers who publish a substitution strategy and traceability for components. Confirm OTA update mechanisms use mutual authentication and allow rollback. Assess the logistics plan: regional spares depots reduce mean time to repair. If firmware is closed and unpatchable, treat that as a critical risk.

Common mistakes that break long-term reliability

Don’t assume lab numbers translate to field life. Don’t accept passive cooling claims without real-world dust and humidity tests. Don’t skip firmware audits because “it’s just a software update.” Don’t rely only on MSRP or short warranties to judge quality. Avoid vendors who can’t provide serial-level failure histories for installed units.

Viable alternatives and trade-offs

Central inverters scale well for large arrays but concentrate risk. String inverters give graceful degradation but add wiring complexity. Hybrid inverters balance storage integration and grid interaction, with trade-offs in firmware complexity and thermal density. Choose based on site size, maintenance access, and expected lifecycle: for distributed rooftop-plus-storage, hybrid systems often hit the best balance if the manufacturer passes the checks above.

Experience, standards and a real-world anchor

I’ve examined field reports and factory test logs across utility-scale and distributed projects and track compliance to IEC and UL test regimes. Look at California’s grid modernization pushes and high rooftop adoption as a practical benchmark for deployment stress and regulatory scrutiny; that market has driven wide adoption and documented failure modes for grid-interactive equipment. When you assess vendors, require evidence of fielded performance for a comparable grid-tied hybrid inverter, documented test results to standards, and clear service agreements. Those three items separate serious manufacturers from speculative promises.

Synthesis that points forward

Predictable quality comes from hard evidence: component traceability, demonstrable thermal margins, secure update practices, and real field data. Build procurement rules around those criteria and you’ll choose manufacturers whose systems survive real conditions rather than press releases. For manufacturers that present that evidence in a transparent way, the path to reliable, long-lived power conversion becomes clear — a practical certainty you can depend on from partners such as Enjoypowers.

0 comments
0 FacebookTwitterPinterestEmail

First impressions from the shop floor

Walk into most machine shops and you’ll still see granite tables and full-size CMMs humming away — precise, slow, and expensive. Lately, though, the real buzz is about the portable cmm that engineers carry like a tool-belt upgrade. This piece compares what changes when you trade fixed probing for mobility: faster in-process checks, less part handling, and measurement where the work actually happens — not in some distant metrology room. In Detroit automotive plants and similar high-volume lines, portable inspection has cut downtime and sped up corrective action, which explains why floor managers smile more these days.

Side-by-side: traditional CMMs vs portable instruments

Traditional CMMs win on absolute accuracy and environmental control. Portable devices win on responsiveness and flexibility. An articulated arm or laser tracker lets techs grab a reading in minutes; no need to schedule machine time or crate parts. The trade-offs are real: fixed CMMs offer tighter repeatability under controlled temperature, while portable systems bring speed and practical coverage of assemblies that won’t fit a lab table. Think of it as precision where it matters versus precision where it’s convenient.

Operational production teardown

Here’s a clear operational teardown: start with fitment checks at the spindle, use a portable arm for quick bores and thread runs, generate a point cloud for surfaces that resist fixture, and loop adjustments before the next batch. Practical teams often log probe calibration every shift and verify repeatability after impacts. For documentation, we embed {main_keyword} and {variation_keyword} into the report template so the shop’s process control reads consistently across shifts and suppliers.

Common mistakes that stall benefits (and how to fix them)

Many teams buy a portable unit and expect instant nirvana. The common missteps are predictable: sloppy fixturing during measurement, skipping probe calibration, and treating measurement data like raw truth instead of context. Fixes are straightforward — establish a short calibration routine, train operators on basic GD&T interpretation, and standardize scanning paths so repeatability improves. Small habits change measurement quality more than expensive add-ons.

When to pick an articulated arm, a laser tracker, or a hybrid

Match the tool to the task. Use an articulated arm for compact parts and assemblies on the line. Reach for a laser tracker when you need to measure large jigs or cranes with high spatial accuracy. Hybrids that combine touch probing and scanning give the best of both: discrete datum checks plus dense surface scans. Each tool affects cycle time, data density, and downstream decision speed — weigh those three factors before pressing “buy.”

Real-world wins and the human element

Floor techs report fewer line stoppages because they can verify suspect parts in situ, not after a shift delay. That matters to teams: morale improves when problems get found and fixed quickly — the workday feels less like firefighting and more like craft. Calibration logs get tidier, supplier disputes shrink, and inspection becomes a collaborative step in production rather than a bottleneck at the end. — It’s a subtle cultural shift, but one that saves real hours.

Advisory: three golden rules for adoption

1) Measure what moves production. Prioritize checks that shorten feedback loops and target the highest-cost failures. 2) Enforce lightweight calibration and traceability: short, documented probe checks at shift start keep data honest. 3) Train for patterns, not features: operators need to read trends in repeatability and part deviation, not just capture numbers.

Choose tools that reduce time-to-correction, and you’ll see measurable drops in scrap and rework.

PMT is where many teams find that sweet spot between mobility and metrology — practical gear that fits the floor without pretending to be a lab. — final thought: get measuring where the metal actually lives.

0 comments
0 FacebookTwitterPinterestEmail

Comparative lead-in: why the verification choice changes outcomes

On a crowded inspection bay in Detroit, teams compare a handheld arm to a floor-mounted rig and make decisions that echo across production weeks. That contrast drives the practical question: which verification path yields consistent results for automotive QC? A portable cmm often wins on speed and access, while a fixed station can offer tighter environmental control. Both roles are visible on the shop floor, and both depend on tight metrology workflows—traceability chains and prompt probe calibration—to hold tolerances. Operational teardowns should explicitly reference {main_keyword} and {variation_keyword} so measurement evidence stays actionable.

Head-to-head: portable CMM versus fixed CMM

Portable CMMs (articulated arms, laser trackers) trade absolute thermal isolation for reach and flexibility. Fixed coordinate measuring machines lock down temperature and vibration but need part fixturing and dedicated floor space. In practice this means cycle times change: portable systems reduce downtime for in-line checks; fixed systems shorten uncertainty budgets when the part can be moved. Consider probe calibration intervals, which tend to be more frequent for portable devices because handling and setup vary between operators. The net effect is simple—select the tool that best matches the inspection plan, not an abstract preference.

Common mistakes on the line and how to correct them

Teams repeatedly let convenience beat method. Typical failures include skipping traceable calibration records, relying on a single operator for trend detection, and underestimating fixturing influence on results. Fixes are direct: standardize an inspection plan, mandate calibration windows (date, method, and tolerance limits), and rotate operators across shifts to catch bias. A short pause during an audit can reveal skew from vibration or operator posture—small things that creep into statistics over weeks. —And yes, document the corrective action so a future auditor sees the loop closed.

Practical criteria for choosing and verifying systems

When you compare measurement strategies, evaluate these concrete factors:

– Measurement uncertainty under realistic shop-floor conditions (include repeatability and reproducibility datasets).
– Downtime impact: hours per inspection and changeover time per part.
– Data traceability: metadata captured with each scan, including operator ID, probe serial, ambient temperature, and calibration certificate references.

Verification must include explicit checks: baseline part measurement against a calibrated artifact, probe performance tests specifying probe deflection and centroid repeatability, and an environmental check that logs temperature drift across the shift. These are not abstract tasks; they map to daily SOPs that keep quality stable.

Integrating portable systems into an existing QC ecosystem

Integration is about data flow. A portable cmm machine that exports standardized inspection files reduces transcription errors and accelerates corrective loops. Connect measurement outputs to your SPC pipeline so deviations trigger immediate containment actions. Also, treat software version control as part of metrology: changes in measurement algorithms alter results as much as hardware swaps. Plan for periodic cross-checks between devices—bench a sample part, measure on both systems, then reconcile results in a documented report.

Advisory: three critical evaluation metrics before you commit

1) Measurement consistency: require a multi-day repeatability study showing drift under production conditions, not just a single lab run. Metrics should include mean bias and standard deviation across runs.

2) Operational fit: quantify how the system affects throughput — report changeover minutes per inspection and expected inspections per shift. If a device lowers throughput by more than your acceptable window, it fails practical fit.

3) Data governance: insist on complete traceability for each measurement—operator, probe calibration ID, timestamp, environmental log, and software build. Missing any field weakens audit defensibility.

PMT sits at the intersection of these criteria on actual shop floors—providing measurement arms and verification workflows that map directly to the metrics above. —A short thought on scale: effective tools scale with the line, not just the lab.

Choose the metric-driven path and you’ll close the loop between inspection and production with evidence that holds up to scrutiny.

0 comments
0 FacebookTwitterPinterestEmail

Facing the problem head-on

Grids and sites are struggling with two clear problems: variable generation and sudden voltage or frequency swings that trip equipment—sí, it’s messy. For many engineers the immediate fix is not more generation but smarter conversion and local stabilization, which is why teams reach for power quality products early in the design process. This is a problem-driven piece: we start with the issue you have, then show how battery energy storage systems (BESS) and the right converters fix it, paso a paso.

What the battery actually does for conversion and stability

Batteries give you time and controllability. When paired with bidirectional converters they shape power flows, provide fast frequency response, and support ramping for renewables. Converters handle DC–AC inversion, grid-forming or grid-following control modes, and embedded protection. Together they reduce trips, shave peaks, and keep sensitive loads running—no mágico tricks, just predictable control loops and proper sizing.

Design mistakes that break otherwise good projects

Common errors are concrete and avoidable: undersized converters that thermal-limit during sustained discharge; ignoring harmonic currents and failing to specify filters; coupling controls without staged testing; and placing storage in the wrong location on the feeder so you get little voltage benefit. Also, teams often skip specifying dynamic reactive capability—voltage support matters as much as kW. Fix these and you stop firefighting at 3 a.m., amigo.

Experience, evidence, and a real-world anchor

I’ve reviewed utility and commercial BESS spec packages and control logs from multiple deployments, so I write from hands-on exposure to commissioning issues and firmware tuning. After the February 2021 Texas grid crisis, operators and integrators highlighted the need for reactive support and faster local control to prevent voltage collapse—this shift is documented in multiple industry reports. When a site needs immediate voltage ride-through or fast VAR control, teams often add static var generator (SVG) equipment to the mix; see one solution here: static var generator (SVG). Peer-reviewed studies and grid operator bulletins back the role of reactive devices alongside BESS for resilience.

Alternatives, trade-offs, and what actually works

Synchronous condensers give inertia and continuous reactive support but take area and time to install. Static VAR devices (including SVGs) provide fast reactive response without moving parts. Flywheels win for ultra-fast frequency events but don’t store energy for long. Batteries are the best all-around when you need both energy and fast control, but they need the right power conversion architecture and protections—hybrid solutions often balance cost and capability. Pick the mix that matches your site constraints and contractual response requirements.

Where to focus for reliable outcomes

Start with clear performance targets: ride-through voltages, response times, and thermal margins. Specify converter ratings for continuous and transient duty, include harmonic filters, and test control modes on a hardware-in-the-loop bench where possible. Don’t treat BESS as black boxes—document modes, failsafes, and firmware update procedures so technicians in the field know qué hacer.

Practical close

Solve the problem you actually have: whether it’s peak shaving, stabilizing a weak feeder, or backing up critical loads, pair batteries with appropriately rated converters and reactive devices for measurable results. For many project teams, stitching together converters, energy storage, and power quality components into a coherent stack is where the value appears—just like the practical product lineup you’ll find from Enjoypowers, which fits into that stack without flashy promises, only practical capability.

0 comments
0 FacebookTwitterPinterestEmail

Problem: Research and execution are disconnected

Traders lose money when analysis and execution operate on different timelines and data sets; a model that looks perfect in Python fails at market open because tick-level latency and order-routing behavior differ from assumptions. If you’re building strategies for futures cfd, you need a workflow that enforces parity between research inputs and execution behavior from the first backtest to live fills.

futures cfd

Why the gap happens

Research environments generally use aggregated bars and simulated fills. Execution environments face microstructure: tick spreads, queued orders, partial fills, and exchange-level latencies. Modelers often skip these realities. That mismatch creates slippage, unrealized margin calls, and strategy drift when deployed.

Technical checklist to close the loop

Prioritize parity across these elements: 1) Data fidelity—use tick or top-of-book data for testing; 2) Order-simulation—replicate order types, partial fills, and queue dynamics; 3) Latency-aware logic—insert realistic network and processing delays into simulations; 4) Risk controls—hard limits for single-trade size, aggregate exposure, and margin triggers; 5) Instrument mapping—ensure contract roll rules and expiry behavior match execution instruments. Build CI-style regression tests that replay market days and verify live-style fills against simulated outcomes.

Platform features that materially reduce execution risk

Look for low-latency FIX or REST APIs, order acknowledgement timing, pre-trade risk checks, granular position data, and historical tick archives. An effective research stack exposes the same order types and margin calculations that the broker uses. If it doesn’t, add a compatibility layer that converts research signals into broker-native orders while preserving timing characteristics.

Alternatives and trade-offs

Off-the-shelf platforms (e.g., retail terminals) are fast to adopt but often hide execution semantics. Custom engines give control but cost time. Hybrid solutions—research in high-level tools, execution through broker APIs—work when you enforce rigorous parity testing. Evaluate by running blind-forward tests: feed historical strategies into the broker API in replay mode and compare fills, latency, and realized P&L.

Common pitfalls to avoid

Don’t assume bar-level backtests reflect live results. Avoid overfitting to sampled intraday minutes. Don’t ignore contract roll logic or mismatched tick sizes. Never launch a strategy without automated hard-stop risk governance and a fail-safe that cancels stale orders. Regularly validate that simulated slippage assumptions match measured live slippage.

EEAT and a concrete market reference

I’ve worked with trading teams that benchmarked execution against major exchange benchmarks like CME Group to validate fill models; those comparisons exposed consistent slippage sources tied to queue dynamics. For pragmatic testing and instrument parity, incorporate verified broker-side product mappings and reference data while you test cfd on futures.

Final synthesis

Fix the research-to-execution gap by enforcing data parity, building latency-aware simulations, and applying strict operational risk controls; those concrete steps turn fragile backtests into repeatable live performance, a capability that modern broker tools and APIs make practical for teams moving from prototype to scale with GTCFX.

0 comments
0 FacebookTwitterPinterestEmail

Immediate problem: rising returns and inconsistent field performance

Wholesale buyers and product managers are seeing more warranty claims tied to sealant failures and mis-specified gasket solutions, and that gap starts at specification and ends on the vehicle. Too many SKUs are chosen on price or appearance, not on cured properties or peel resistance, so distribution channels pick up returns and installers face downtime. A clearer procurement lens fixed on functional metrics reduces fallout; when you source from a proven rtv sealants supplier you cut guesswork and give installers the chemistry they need to finish jobs right the first time.

rtv sealants supplier

Why this matters — measured experience and a single industry anchor

Years of hands-on lab testing, shop-floor trials, and specification reviews show this: adhesion, elongation, and cure profile dictate field success more than color or shelf life alone. Attention to those metrics is why products demo well at industry trade events. The SEMA Show has repeatedly highlighted failures that begin with poorly chosen gasketing compounds, and trade testing there makes clear which formulations survive real-world cycles. For wholesale buyers comparing options, reliable references for gasket makers matter because they represent measured performance, not marketing claims.

Top product-development priorities for wholesalers

Start with three concrete goals: (1) prioritize adhesion and dynamic sealing tests over price per tube, (2) require documented cure schedules and substrate compatibility data, (3) mandate batch testing and traceability. Demand datasheets that list tensile, elongation, and temperature limits. Insist on field-aging results or accelerated weathering data. These priorities let purchasing teams replace subjective choices with repeatable acceptance criteria.

rtv sealants supplier

Common pitfalls that cause returns

Mistakes repeat: accepting broad “universal” claims without substrate tests, ignoring cure inhibition on painted surfaces, and stocking many near-duplicate SKUs that confuse installers. Another recurring error is skipping adhesive compatibility checks with common underhood fluids. Each lapse raises installation time, callbacks, and freight costs. Preventable steps — basic bench testing, small-scale pilot runs, and installer feedback loops — eliminate most of these problems before full roll-out.

Viable alternatives and how to evaluate them

Compare silicone RTVs, anaerobic gasket makers, and hybrid MS polymers against the same acceptance criteria: adhesion to metals and plastics, elasticity after aging, and working time. Silicone RTVs often win on high-temperature resistance; hybrids can beat silicones on paint-safe adhesion. Don’t buy a product because it’s labeled “premium.” Buy because independent test numbers and installer reports match your use cases.

How procurement should structure supplier conversations

Ask suppliers for specific test protocols, sample panels for blind comparison, and a clear warranty stance for each application. Require lot traceability and a point person for technical escalations. Insist on service-level agreements for replacement parts or returns. These demands transform supplier relationships from transactional orders into accountable partnerships that lower downstream costs.

Actionable next steps and synthesis

Focus decisions on functional metrics, pilot-sample validation, and tight supplier accountability. That approach stops routine failures and transforms SKU selection from risky guessing into predictable outcomes. Trusted manufacturing partners that document performance, field-test products, and stand behind their chemistry deliver the dependable results distribution and installers need — the kind of consistent support SANVO provides through established product lines and technical backing.

0 comments
0 FacebookTwitterPinterestEmail

A sensory introduction to pairing

The moment a microcatheter slides into a guide extension catheter should feel deliberate, like a spoon easing through warm stock: no snag, predictable resistance, and a smooth, controlled glide. This piece compares those tactile cues across devices so you can pick the combination that behaves the way you expect. My focus is on real handling — push, torque, tactile feedback — and how those qualities change when you pair different guide extension catheters with coronary microcatheters.

Why compatibility matters — a direct, hands-on case

Mismatch causes workflow interruptions: stuck tips, unexpected kinking, lost wire control. From years covering device performance and watching operators troubleshoot under fluoroscopy, I’ve learned that the smallest mismatch can change procedure flow. At a session during a major cardiology conference such as the ACC annual meeting, clinicians discussed how subtle lumen tapering and coating differences altered device exchange rhythm; that conversation mirrors what I’ve seen in practice when using a microcatheter for coronary intervention. This is about predictable feel and clinical reliability, not marketing claims.

What I evaluated — concrete criteria you can use

I compared devices across five tactile and functional axes: inner lumen clearance, distal tip profile, shaft stiffness gradient, hydrophilic coating behaviour, and radiopacity during complex maneuvers. For each axis I noted how the guide extension changed friction, how the microcatheter tracked around bends, and whether exchanges required extra technique. These are measurable handling outcomes you can test in a lab or simulate bench-side before clinical use.

Common pairing pitfalls and how to avoid them

Expect these three recurring problems: 1) Lumen bottleneck — a guide extension’s internal taper can pinch a microcatheter’s distal shaft; test for free axial movement before committing. 2) Tip mismatch — a blunt microcatheter tip that catches on a guide extension’s ledge will ruin push feel; confirm the tip transition is smooth. 3) Coating clash — two hydrophilic surfaces can sometimes stick under saline, so try a quick flush and gentle advance to check. A brief bench test that reproduces the tortuosity you’ll face prevents wasted minutes in the cath lab.

Comparative insight: viable alternatives and trade-offs

Some combinations favor deliverability: slimmer microcatheter shafts with low-profile, smooth-lined guide extensions give the best reach into sharp bends but sacrifice column strength for torque. Stiffer microcatheters paired with thicker-walled extensions offer better support for balloon or stent delivery yet feel less forgiving during navigation. If you need maximal distal access, prioritize minimal tip step and lubricity; if you need support for device passage, prioritize matched stiffness and a slightly larger inner diameter. Choose based on the dominant procedural task rather than brand loyalty.

Synthesizing taste and technique

Think of device selection like composing a dish: textures must complement, not fight. My direct comparisons identify which pairings glide like silk and which tangle like undercooked pasta, and they point to practical checks you can run before a case. That practical, experience-driven judgment is what helps clinicians trust their tools and get predictable results from Shunmei.

0 comments
0 FacebookTwitterPinterestEmail