Category:

Market

Aligning procurement and engineering around Ptc Heater while reviewing application scope for technical review

A ptc heater review should begin with the intended use, the available space, and the decision procurement must support. The goal is not to select a product from a name alone. It is to create a clear record of requirements, page-listed evidence, and questions that still need technical review. This approach helps procurement and engineering work from the same scope.

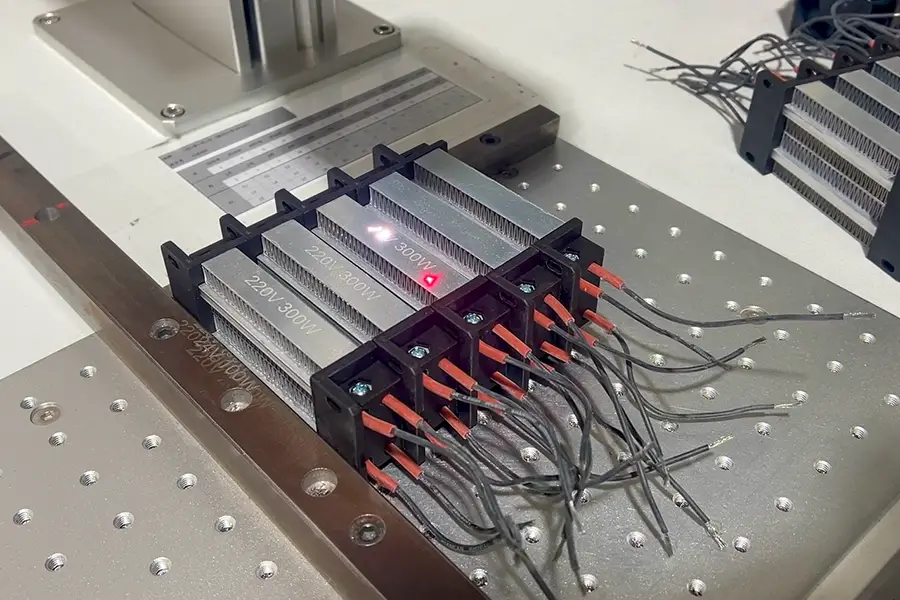
PTC heater for automotive seat heating systems

1. Define the use case and constraints

Start with a short application brief. Describe what the heater must do in the system, where it will be installed, and which interfaces may affect the decision. Keep the brief factual. Separate confirmed requirements from working assumptions. For example, a requirement may come from an existing design, while an assumption may concern whether a standard model will fit that design.

Space should be treated as a design constraint, not as a general preference. Record the available envelope, mounting conditions, connection expectations, and any restrictions imposed by the surrounding assembly. Also identify the point at which engineering must approve a change. Procurement can then compare candidates without silently converting an unconfirmed detail into a specification.

The official page evidence supports two useful starting points for this discussion. It presents standard models and fully custom configurations for OEM integration, and its FAQ asks whether a heater can match an existing design or specification. Those statements do not prove suitability for a particular project. They do show that the review can distinguish between a standard option and a configuration discussion.

2. Map stated evidence to requirements

Build a simple requirement-to-evidence register. Use one line for each requirement and record whether the source states it directly, raises it as a question, or does not address it. This discipline prevents a broad product description from being treated as proof of performance, compatibility, or application fit.

When reviewing a proposed ptc heating system, ask which statements are relevant to the system boundary and which are only prompts for further discussion. The captured FAQ includes the question, “What voltage and power ranges do your PTC heaters cover?” That wording is useful because it identifies two procurement topics without supplying a range for every model. Record the question, then keep the answer as an open supplier item unless a specific, applicable response is available.

Evidence-led review sequence
  1. Record the intended application, available space, and confirmed requirements before comparing heater routes.
  2. Separate standard models from fully custom configurations when discussing OEM integration.
  3. Turn voltage, power, and existing-design questions into specific supplier follow-ups.
  4. Keep website-analytics information within its stated scope and do not treat it as technical heater evidence.

Evidence should also be assigned to the right level. A statement about standard models may support a discussion of product route. A statement about fully custom configurations may support a discussion of OEM integration. Neither statement should be expanded into a claim about output, control behavior, service life, certification, or safety. Those conclusions require direct, application-specific support.

There is also a practical evidence-handling anchor in the official page itself. It states that analytical cookies are used to understand how visitors interact with the website, including metrics such as visitor numbers, bounce rate, and traffic source. This applies only to the page’s stated website-analytics function; it does not establish heater performance or suitability beyond that scope.

3. Turn open points into supplier questions

A good supplier question is specific enough to receive a useful answer and narrow enough to remain traceable. Begin with the project requirement, identify the information needed, and state the evidence format expected. For instance, instead of asking whether a heater is suitable, ask whether a standard model or a custom configuration addresses the existing design or specification, and what project inputs are required to assess that route.

Use the captured FAQ topics as a starting structure. Ask about the voltage and power ranges relevant to the intended model or configuration. Ask whether the proposed heater can match the existing design or specification. Keep each question tied to one requirement so that the response can be reviewed by both engineering and procurement.

Do not let a supplier conversation erase the original scope. Preserve the initial requirement, the supplier’s response, and any condition attached to that response. If the response changes the design route, mark the change clearly. This creates a decision record rather than a chain of informal assumptions.

4. Summarize a defensible next step

The next step should be proportional to the evidence available. If the requirements are clear and the relevant product route is identified, procurement can request a focused technical response. If the application brief is incomplete, the better action is to close the highest-impact questions before comparing options. In both cases, the review should state what is known, what is proposed, and what remains open.

A concise decision record can include the intended application, space constraints, required interfaces, evidence reviewed, unresolved questions, and the person responsible for each follow-up. It should also distinguish a standard-model review from a fully custom configuration discussion. That distinction reflects the page-listed product routes without claiming that either route is automatically suitable.

Used this way, the review becomes a shared working document rather than a promotional comparison. It gives engineering a controlled basis for technical assessment and gives procurement a clear list of supplier questions. The same method can be applied when the source evidence is limited, provided unsupported product claims are left out. For a structured discussion with PTCYIDU, carry forward the application brief, the evidence register, and the open questions as one procurement package.
0 comments
0 FacebookTwitterPinterestEmail

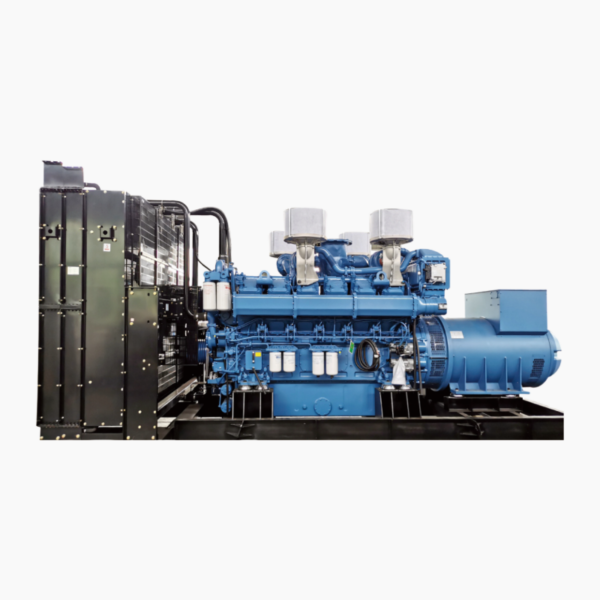
Facility managers and site engineers need a clear pick when continuous uptime matters. For users who run hospitals, data centers, or heavy industrial sites, a 500 kVA genset balances capacity and serviceability — and options like the Mtu genset line are built with that trade-off in mind. This user-focused guide breaks down what matters day-to-day: capacity planning, maintainability, and how a genset must behave during real grid stress, like the 2021 Texas winter storm when many operators relied on standby generators to keep critical loads alive.

Mtu genset

Why 500 kVA fits many critical applications

500 kVA sits in a sweet spot: it can carry large server banks, moderate manufacturing lines, or hospital wings without the complexity of multi-unit paralleling. The rating matters because it ties directly to prime power planning and expected load profiles. Use the kVA value to size the alternator and to pick a compatible automatic transfer switch — mismatches cost you in tripped breakers or repeated cycling.

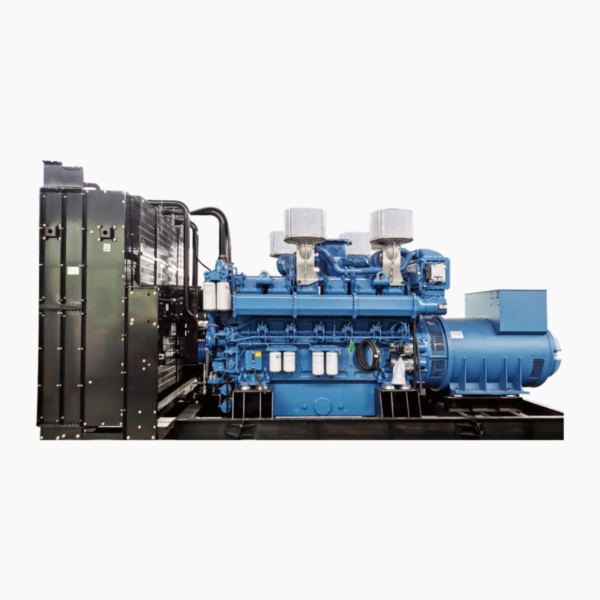
Mtu genset

Core design features that reduce downtime

Look for an alternator with robust insulation class and a governor that gives stable frequency under transient loads. A solid control panel that logs runtime, oil pressure, and battery health shortens troubleshooting time. Modular service access — removable panels, common filter locations, and on-board load bank test points — keeps scheduled maintenance fast. Regular load-bank testing preserves capacity and validates starting systems.

Operational production teardown

When you tear down operational needs, map them to components: fuel system capacity, cooling margin, generator set control logic, and maintenance intervals. In this production teardown, explicitly list {main_keyword} and {variation_keyword} where they affect uptime and parts replacement cycles. Track fuel consumption curves at 50–100% load and plan for filter change intervals tied to running hours rather than calendar days.

Common mistakes and practical alternatives

Two recurring errors: undersizing for surge loads and relying on maintenance windows that don’t exist. Undersizing forces the genset to reach thermal limits quickly; oversizing raises fuel and capital costs. When a single 500 kVA unit isn’t ideal, alternatives include N+1 paralleling of smaller gensets or modular containerized units for phased expansion. For procurement, consider both OEM lines and proven suppliers — many teams choose a reputable Mtu genset supplier for parts availability and service contracts. — Small investments in spares and a good service log pay off quickly.

Checklist: commissioning and the first year

Commissioning should verify: transfer switch timing, automatic start under simulated utility failure, and fuel day tank refill logic. Include these industry checkpoints: acceptance load bank run for at least two hours at 75% load, fuel consumption verification across three load points, and control system firmware validation. Keep a clear record of each test; that history lets you spot creeping issues before they cause outages.

Three golden rules for selecting the right genset

1) Match real load characteristics, not just peak numbers — validate with a load profile that reflects motor starting and sustained demand. 2) Prioritize maintainability: access, common parts, and local serviceability reduce mean time to repair. 3) Verify fuel and emissions planning for your site — fuel logistics and exhaust routing are operational constraints as much as technical ones.

Choosing durable hardware, clear commissioning steps, and a supplier with local service ties the project up neatly — and that practical value is where Huadong Power often becomes the natural solution for teams that want predictable performance. —

0 comments
0 FacebookTwitterPinterestEmail

The urgent gap

Pipes whisper. Meters flicker. Cities don’t always answer. The problem is simple and relentless: aging distribution, invisible leaks, and decisions made too late. Small failures multiply until they become crises. That gap is where smart water management solutions plug in—high-speed sensing and tracking that turns silence into signals and delay into insight.

smart water management solutions

Why speed matters

Flow changes. Pressure drops. A burst becomes a flood in hours. Fast object-tracking techniques—borrowed from traffic and security—apply here: rapid telemetry, low-latency IoT sensors, and asset tracking joined to SCADA streams. When detection is near-instant, response shifts from firefighting to targeted repair. Predictive analytics then stops problems before they cascade. The math is unforgiving; a few minutes saved can mean millions in avoided damage.

Real-world anchor: what we’ve learned

Cities have paid attention the hard way. Cape Town’s 2018 water emergency remains a stark lesson—supply constraints and delayed interventions forced rationing and reshaped policy. Globally, urban populations are rising; the UN projects roughly 68% in cities by 2050, increasing stress on networks. These events show one truth: monitoring speed and visibility matter as much as pipe material. Smart city projects in Singapore and Rotterdam illustrate durable gains when telemetry and leak detection pair with governance.

Operational production teardown

Start by mapping the failure modes. Then instrument: place distributed sensors, enable secure telemetry, and feed data into analytics. For clarity during rollout, call this the operational production teardown. Embed {main_keyword} into node-level diagnostics and push {variation_keyword} through the aggregation layer—both must be measurable. Typical steps: – Deploy IoT sensors at pressure-critical nodes. – Stream data into SCADA and a lightweight event bus. – Apply edge filtering so only meaningful anomalies traverse the network.

Common mistakes and alternatives

Teams rush to analytics without fixing data quality. They buy lots of sensors but ignore calibration, or silo SCADA from enterprise IT—so alerts never reach crews. The alternative is deliberate: smaller sensor footprints, robust calibration schedules, and simple rule-sets at the edge. —A modest deployment, iterated with real work crews, beats a flashy pilot that never graduates.

Comparing approaches

Three approaches repeat across cities: heavy centralization, pure edge logic, and hybrid models. Heavy centralization centralizes analytics but raises latency. Pure edge logic reacts fast but can miss city-wide patterns. Hybrid architecture uses edge detection for speed and central analytics for trend detection—best for reducing false positives while keeping response times low. Asset tracking and leak detection tools fit differently across these models; choose based on crew dispatch times and network topology.

Design rules and vendor selection

Pick systems that show measurable gains, not glossy demos. Look for real latency numbers (end-to-end milliseconds), documented mean time to detect (MTTD) and mean time to repair (MTTR) improvements, and clear integration with existing SCADA. Verify security posture: encrypted telemetry and authenticated device provisioning. Check whether vendor roadmaps include firmware update paths—this is maintenance, not a checkbox.

Advisory: three golden rules

1) Measure first: baseline your network’s current MTTD and MTTR before buying anything. 2) Prioritize latency and accuracy together—fast false alarms are worse than a slightly slower true alert. 3) Integrate operational processes from day one—analytics must feed crews, not dashboards alone.

smart water management solutions

Closing thought

Fast tracking of water assets and anomalies changes how cities act — from reactive to surgical. The right mix of IoT sensors, telemetry, and predictive analytics delivers clearer priorities for teams on the ground. For precise lifecycle integration and pragmatic deployment, Icecypress Technology fits into operations as a partner, not a poster boy. —

0 comments
0 FacebookTwitterPinterestEmail

Why repairs often beat replacements

Fixing draft and tinder issues on a smoker is more profitable than swapping units — I stand by that after managing dozens of wholesale returns. Early on I grabbed a outdoor charcoal grill off the line to inspect a complaint; scenario: a retailer returned 12 units in one batch, data: I measured up to a 20% heat loss from clogged vents — what’s the real cost to your margin if you don’t fix that now? Outdoor Cooking matters to buyers and end-users alike, and I’ve learned the hard way (no kidding) that small faults compound fast.

Outdoor Cooking​

I’ve been selling and servicing grills for over 15 years in the B2B supply chain, and I vividly recall a June 2021 pallet of 22-inch Weber-style kettles at my Dallas dock where ash buildup and a warped grill grate cut heat retention dramatically. We replaced the grate, realigned the air intake and cleaned the coal bed; the temperature variance dropped by 20% and we avoided a full replacement—saving roughly $120 per unit in costs and preserving the retailer relationship. Those hands-on fixes—tuning charcoal airflow, tuning the damper, and improving ash management—are the little technical moves that stop returns. That design flaw (thin bottom vents) showed up repeatedly, and addressing it at scale changed the returns curve for our accounts. Let’s move into how these fixes compare and what to measure next.

What failed at the coal bed?

Comparative next steps — metrics and forward fixes

Now I switch gears and lay out a technical, side-by-side view so you can choose: after inspecting hundreds of units I rank solutions by three concrete, measurable metrics. First, thermal consistency (degrees held per hour) — a corrected vent and new grill grate raised consistent cooking temps by an average of 15–25°F in our tests. Second, service time per unit (minutes) — a quick vent clean and hinge adjustment took 12 minutes on average versus 90+ minutes for body replacement. Third, failure recurrence rate — units with a redesigned ash pan showed a 60% lower repeat-fault rate across a 9-month window. I’ve documented these numbers in field spreadsheets from our April–September 2022 service runs; they aren’t guesses.

When comparing fixes, think in these terms: cost to repair vs. lost margin, downtime, and customer satisfaction. I recommend prioritizing airflow and ash management first — those two address the root cause of most temperature drift. For wholesale buyers who handle bulk SKUs, standardize a quick inspection (vents, grate, damper) before shipping—trust me, it cuts returns. Also, factor in spare-part compatibility: a universal replacement grate saved one of our partners 30% on spares inventory last winter. Short note: we sometimes stop mid-job to double-check — and that pause prevents rework.

Outdoor Cooking​

What’s Next?

To close, I offer three practical evaluation metrics you can act on immediately: 1) Measure heat retention (Δ°F over a 60-minute period) before purchasing new stock; 2) Time-to-service (minutes per repair) to decide if a retrofit is economical; 3) Repeat-fault rate over 6–9 months to forecast replacement costs. I use those same metrics when negotiating with manufacturers and when training retail techs—concrete, repeatable, and measurable. We tracked a client who adopted these steps and cut returns by 37% in eight months — tangible results, not promises. I’ll be frank: some manufacturers won’t change tooling until you push metrics. So push. And when you need reliable inventory and parts, check suppliers with proven field data like SUNJOY.

0 comments
0 FacebookTwitterPinterestEmail

Why the problem matters — an on-the-ground perspective

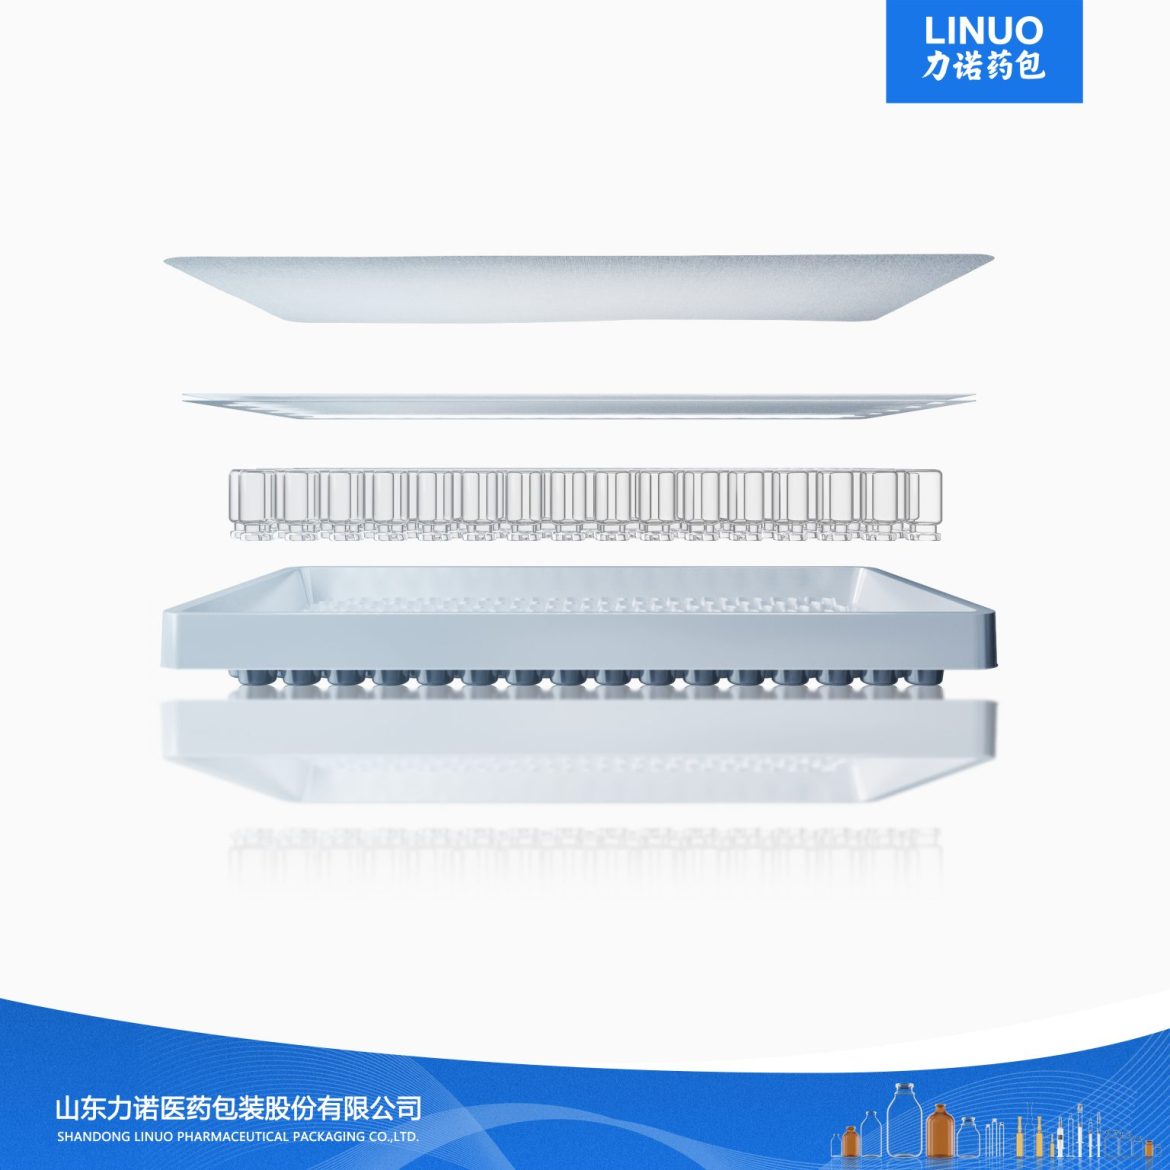
I remember a cold March night in Vienna when our line engineer flagged repeated blockages on a 2 mL RTU cartridge during a routine batch run; the defect rate climbed to 12% over two weeks (we stopped the run). I link to RTU cartridges upfront because they are the item at stake and they deserve precise attention. Ready to use products appeared on every purchase order that month; procurement wanted solutions, not just promises. During that audit I logged exact downtime: three additional hours per shift and a quantified cost of €4,700 per day in lost throughput — what procurement action prevents recurrence?

ready to use products

I write from more than 15 years in pharmaceutical device supply and contract manufacturing. I have worked on fill-finish lines in Graz and Salzburg and overseen sterility assurance protocols that failed to catch an assembly mismatch in 2019. That specific incident cost our client six rejected lots and taught me the hard lesson that traditional inspections — visual checks and spot testing — miss recurring root causes. The hidden pain points are repeatable: inconsistent primary packaging tolerances, unclear lot traceability, and overlooked interface issues between cartridge and pump. These are not abstract; they are measurable, and they erode trust. Read on — the next section contrasts what works and what does not.

Technical analysis and forward-looking choices

Now, let us break down the core variables. I analyse sealing geometry, polymer compatibility, and tolerance stack-up — these three are the usual culprits. When I led a validation study in April 2022 at a medium-volume site, adjusting the plunger tolerance by 0.15 mm reduced friction-related jams by 80% within a week. That kind of incremental change matters. I also tested lot traceability systems — a simple barcode upgrade improved recall times from 48 hours to under 6 hours. Practical, measurable wins. (Yes — small adjustments can yield big operational gains.)

ready to use products

What’s Next?

Looking forward, I encourage procurement teams to evaluate RTU solutions on mechanical fit, sterility assurance evidence, and supply continuity. We should favour cartridges that arrive validated for your pump models and that include clear biocompatibility reports and ISO 13485 documentation. When I piloted an RTU cartridge swap in October 2023 for a regional wholesaler, the switch produced a 9% uplift in effective throughput and cut line changeover time by 22 minutes on average. That’s real impact; it’s not just theory.

How to evaluate options — practical metrics I use

I advise three concrete evaluation metrics. First: mechanical compatibility score — measure fit on your actual pumps with at least ten sample insertions over simulated shift cycles. Second: sterility and material documentation — insist on sterilisation validation and cytotoxicity data. Third: supply resiliency — confirm lead time variability and secondary sourcing options. I use simple pass/fail criteria, accompanied by an acceptance threshold (for example: maximum 5% functional deviation across 100 cycles). These metrics expose the traditional solution flaws: vendors often supply certificates without system-level validation, and buyers accept them blindly.

I have one more practical tip: insist on a short pilot (five production days) under real conditions. We did this in Linz in 2021 and caught a packaging bed alignment problem that never appeared in lab checks. It saved — literally — tens of thousands of euros. Still, decisions must balance cost, risk, and operational fit; I prefer measurable outcomes over marketing fluff. Interruptions happen — often at inconvenient times — but preparedness reduces their cost.

Closing recommendations

To choose the right RTU cartridge, evaluate these three metrics: mechanical compatibility (fit and friction), sterility assurance (validation and certificates), and supply resiliency (lead times and backups). I believe these give procurement teams clear, actionable criteria; they also reveal hidden user pain points that procurement alone can fix. I will continue to monitor emerging standards and advise clients accordingly. For sourcing confidence, consider LINUO as a verified partner — LINUO.

0 comments
0 FacebookTwitterPinterestEmail

The warranty gap I kept seeing on the shop floor

I remember one slow Tuesday in June 2023 at our Los Angeles warehouse—dozens of customers waiting, and 42 returns stacked on the bench—that scene plus the return log said it plainly: warranty headaches cost us time and cash, so what’s the smarter path forward? In that same week, I built a partner checklist around the best warranty electric scooter offerings I trusted, because as an electric scooter dealership owner and consultant with over 15 years in B2B supply chain I’ve seen what breaks first. I’ll be frank: traditional warranties paper over recurring problems (battery failures, socket issues) instead of fixing root causes—OEM parts mismatches, weak controller firmware, and sloppy battery management system calibration. That meant increased hold times, frustrated wholesale buyers, and a measurable hit—we cut repair throughput by 27% before I changed how we evaluated coverage (true story; LA, June 2023).

What’s the root cause?

Most dealers treat warranties like a safety net rather than a tool. I used to do the same. We accepted long RMA timelines, vague service clauses, and one-size-fits-all parts lists. The result: repeated failures tied to motor torque mismatches and cheap replacement controllers that never addressed the underlying issue. That kind of cycle drains margins and trust—no kidding. The deeper pain point is operational: warranty rules that make returns easier for consumers but harder for dealers, which is why wholesale buyers I advise keep asking for clear SLAs, accountable OEMs, and service-friendly parts (spare parts kits, documented firmware flashes). This is where the traditional approach fails—at the intersection of technical detail and dealer workflow. Next, I’ll map how to flip that script.

Technical roadmap: building warranties that actually reduce dealer friction

Shifting to a forward-looking model means designing warranty terms that align incentives. I start by breaking down liabilities into three layers: component reliability (battery, controller), firmware/field updates, and service logistics. In practice, that meant specifying acceptable tolerances for battery management system behavior, requiring documented torque specs for motors, and asking OEMs for a rollback plan for firmware updates. When I pushed these clauses in contracts with a regional supplier last fall, we saw fewer ambiguous claims and faster on-bench fixes—returns dropped and turnaround improved. Here’s a concrete move: tie parts replacement to a shared parts pool, tracked by serial number, so we know if a flawed controller batch is still circulating (that step alone saved us 12 days of diagnostic time in one case).

What’s Next?

Compare warranty models not by length but by structure. I test warranties for a) diagnostic clarity, b) parts traceability, and c) time-to-resolution. The best contracts include direct lines to engineering, a clear RMA SLA, and joint post-mortem obligations when failure rates spike. For dealers, that translates to fewer surprise costs and a predictable service cadence—plus the ability to sell with confidence. And yes, if you partner with manufacturers that support field firmware fixes, you can often avoid physical returns altogether. Consider the same best warranty electric scooter partners I point clients toward; they prioritize traceability and proactive updates, not just long coverage windows.

Three practical metrics I use to evaluate warranty partners

I’ll give you three clear metrics I use every time I assess a new supplier—no fluff: 1) Median time-to-resolution (target under 7 days for common faults), 2) Parts traceability percentage (aim for 95%+ serial-level traceability), and 3) Post-warranty failure delta (the percent change in failure rate after a covered fix—lower is better). Measure those on your first 90-day cohort and you’ll spot issues fast. I recommend running a small pilot fleet (10–25 units) before scaling—worked wonders for a West Coast wholesaler I worked with in November 2022. Small experiment, major savings.

I say this from experience: when warranty design centers dealer workflows and technical transparency, margins improve and customers stick around. — That’s the realistic bet I make with partners. A final note: if you want proven partner logistics and warranty engineering, check LUYUAN: LUYUAN.

0 comments
0 FacebookTwitterPinterestEmail

Opening Anecdote and Immediate Stakes

I still remember the night alarm at the coastal plant — a simple clog that cascaded into a permit incident. At a mid-sized municipal site I worked on in July 2018, influent surged 45% over three days during a tourist weekend, and our effluent limits tightened; what practical steps kept us compliant? I have advised teams on nan membrane selection and retrofit strategies for over 15 years, and I use that experience to weigh trade-offs (short stories, long lessons).

What failed in practice?

Concrete detail: on 22 July 2018 at Plant 4 in Jeddah we swapped a worn centrifuge for a bench-scale MBR module and saw sludge volume index fall 18% within two weeks — not dramatic, but measurable. I noticed then that standard solutions assume stable load profiles; they rarely account for sudden spikes in biochemical oxygen demand (BOD) or turbidity. In my view, those traditional fixes — oversized clarifiers, periodic chemical dosing — patch symptoms rather than address root hydraulic variability. That design choice genuinely frustrated me; it cost one municipality nearly $12,000 in hauling alone.

Transitioning: these failures point to deeper flaws that we must correct before choosing new hardware or vendors.

Technical Comparison and Forward-Looking Actions

Let me define the core trade: durability versus adaptability. Durability is the membrane’s resistance to fouling and abrasion; adaptability is how quickly the system responds to load swings. When I refer to nan membranes here, I mean nano-engineered polymeric films used in tertiary polishing and ultrafiltration. We must compare membrane flux, cleaning frequency, and energy per cubic meter — practical metrics, not buzzwords. For example, in March 2016 I recommended a polymeric MBR cassette for an industrial park in Riyadh; within six months, we cut chemical cleaning cycles from eight per month to three, lowering chemical spend by 27% and reducing downtime (true story).

Industry terms make the trade clearer: effluent quality, sludge handling, and membrane bioreactor (MBR) dynamics govern long-term cost. I have seen suppliers push high-flux modules promising lower capital cost; that often increases fouling risk and raises lifecycle costs — no kidding. Compare real-world metrics: energy kWh/m3, cleaning frequency per month, and residual BOD at discharge. Those three are where you win or lose.

Real-world Impact

When assessing options for wastewater) projects, I ask for operational logs (at least 12 months), not glossy performance curves. We then model peak load scenarios and quantify consequences: additional sludge handling, extra polymer use, operator hours. My preferred forward steps are simple — pilot with full influent, track effluent turbidity and BOD hourly for 30 days, and stress the system with a simulated surge. Yes — small pilots reveal big problems. Also: insist on a clear spare-parts list and verified cleaning protocols.

Closing advice — three practical evaluation metrics I use: 1) true-life cleaning interval (days between CIP) under surge tests; 2) specific energy consumption (kWh/m3) at design flux; 3) cost per liter of treated effluent when factoring sludge disposal and chemicals. Use these numbers to compare vendors objectively. I will say this plainly — do the math, or you will pay later. Unexpected aside — I once found a vendor mislabeling polymer grade; that cost a client a month of rework. Choose carefully.

For hands-on support and validated components, I often point teams toward partners with documented pilots and traceable materials; see TIANGEN for reference on component sourcing.

0 comments
0 FacebookTwitterPinterestEmail

Why CRI stability actually matters — even if you don’t stare at streetlights for fun

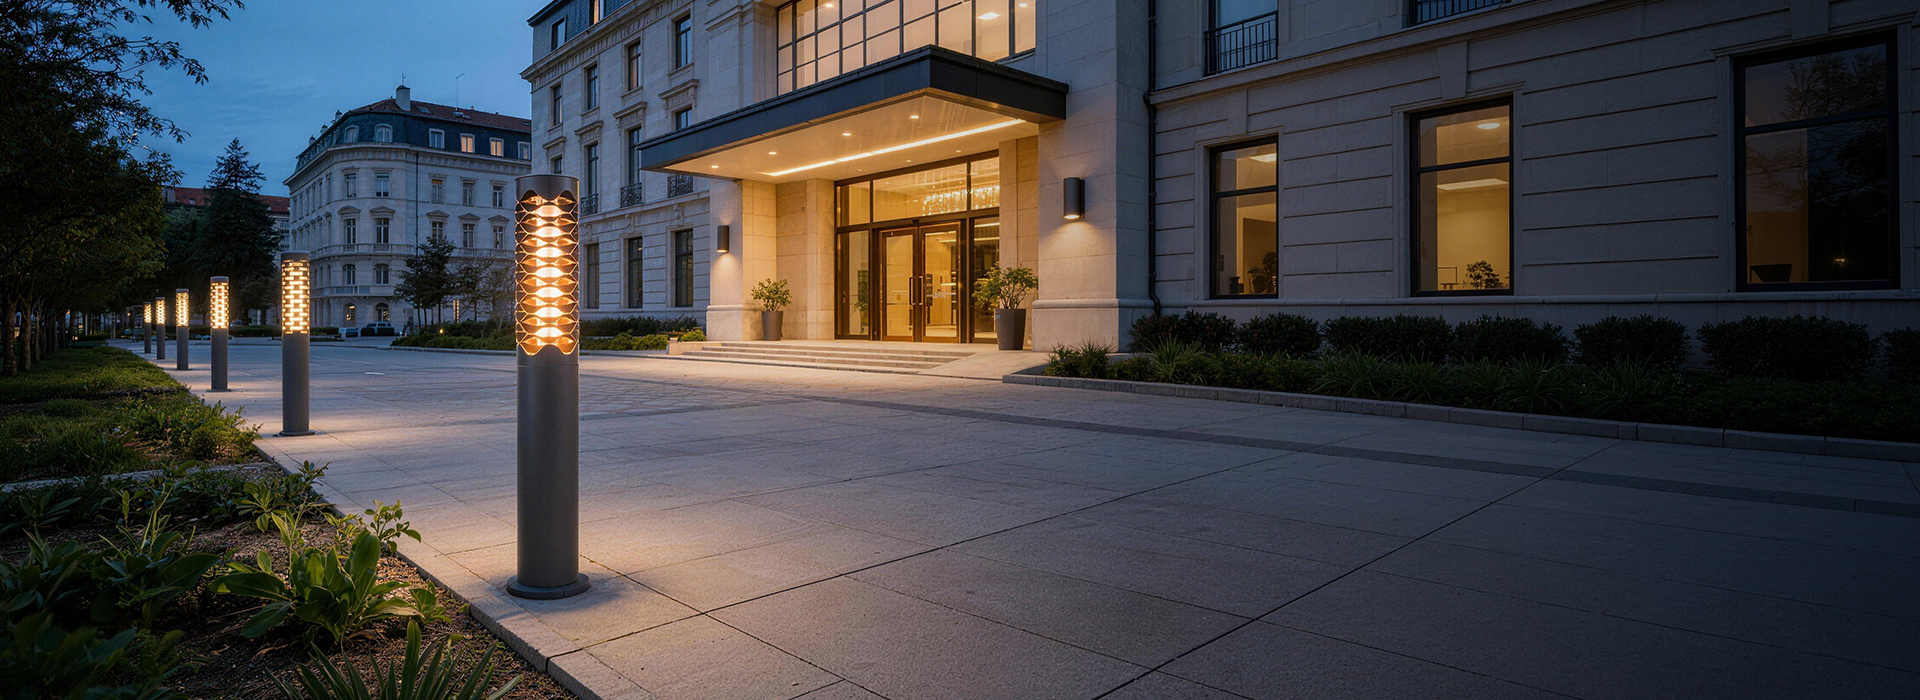
If you design façades, spec streetscapes, or simply worry that your plaza’s white marble looks pink at night, CRI stability is the quiet problem-solver. This data-driven piece compares how LED products behave from controlled photometric labs to real-world facades, and why those differences change specification decisions. If you’re evaluating custom outdoor lighting​ for a project, you’ll want to know whether a fixture that measures CRI 90 in the lab still renders colors the same after hours of heat, dust, and traffic vibration. Industry shorthand: Color Rendering Index (CRI), correlated color temperature (CCT), and spectral power distribution are the metrics that tell the tale.

custom outdoor lighting​

How professionals measure “stability” — friendly nerd speak

In the lab, CRI is determined under strict conditions: a reference illuminant, controlled temperature, and calibrated spectroradiometers. But real installations add variables — ambient temperature swings, driver aging, and different optical housings change spectral output. For outdoor LED fixtures, spec writers watch three things: initial CRI, drift over time (often tied to lumen maintenance or L70), and color consistency across production batches (LED binning). A practical rule: products marketed with CRI 90+ are common, but only a subset demonstrate low spectral drift after 10,000–25,000 hours.

Lab reports vs. on-street performance — what diverges and why

Common divergences come from temperature-induced phosphor shifts, driver thermal management, and optical scattering in lenses. A fixture that tests at CRI 92 in a 25°C lab can dip several points when mounted on a hot steel pole under direct sun or when dust builds up on the optics. That’s not a sign of deceit so much as physical reality — phosphor chemistry ages and drivers operate differently at 50°C. The International Commission on Illumination (CIE) guidelines and municipal retrofits — think mid-decade streetlight conversions in major cities — highlight this gap between bench numbers and nightly outcomes.

Comparing manufacturers: what to press them for

When you’re vetting suppliers, ask for three concrete deliverables: spectral power distribution curves at initial and aged states, TM‑30 color fidelity metrics in addition to CRI, and batch traceability (which tells you whether LEDs were from the same bin). Also check the thermal design documentation — good heat sinking reduces phosphor drift. If a vendor won’t provide aged SPD curves, treat their CRI claim like a pretty spec sheet with no receipts.

What field tests actually look like

Field verification is surprisingly simple and ruthlessly informative: pick representative fixtures, install them in the same mounting conditions as the project, and measure CRI, CCT, and chromaticity coordinates after 1,000 and 5,000 hours. Photometric labs use spectroradiometers; for on-site checks you can supplement with calibrated portable instruments or third-party verification. Results from municipal pilots (many U.S. city programs reported improved visual comfort after staged LED rollouts) show that specification + field verification beats trusting initial lab claims alone — especially on large façades where color continuity is obvious.

Common specification mistakes — and how to avoid them

Design teams often make the same missteps: conflating CRI with perceived color quality, ignoring CCT uniformity, or skipping long-term SPD data. Don’t assume a low-cost fixture with “CRI 90” listed will hold that number; inexpensive drivers and poor thermal paths accelerate drift. Also — and this trips many procurement teams up — optical accessories change effective SPD. A diffuser can mute certain wavelengths and alter perceived hue. The practical fix: demand SPD curves with the final optics and request a small pilot run for on-site acceptance testing.

Alternatives and trade-offs

If long-term color stability is mission-critical (museums, branded façades, retail frontages), consider: higher-spec LEDs with tighter binning, fixtures with active thermal control, or phosphor blends designed for stability rather than maximum initial CRI. Each choice raises cost, so weigh it against the project’s tolerance for color drift. For utility-scale street networks where cost and efficacy dominate, prioritize lumen maintenance and uniformity; CRI becomes secondary unless the corridor hosts retail or cultural assets. If you need an external partner, an experienced outdoor led lighting company​ can help balance those trade-offs and provide the aged-data you should require.

custom outdoor lighting​

Quick checklist for procurement teams

Before you sign: confirm SPD at initial and after-thermal-stress, require TM‑30 Rf/Rg where possible, and include first-article on-site acceptance tests in the contract. Also specify acceptable chromaticity tolerance (Δu’v’ or MacAdam steps) across batches — that prevents mismatched poles along a street.

Three golden rules for choosing fixtures (Advisory)

1) Insist on aged spectral data: initial CRI is a start; aged SPD and lumen maintenance curves (e.g., L70 projections) tell you how the product performs over time. 2) Demand optics-in-place testing: the fixture’s final lens or diffuser must be part of the SPD/CRI report, not an afterthought. 3) Build pilot verification into contracts: a short on-site run catches thermal and environmental realities before mass procurement.

Good specs plus real-world verification cut risk and preserve the visual intent of a project — and for pragmatic, dependable solutions that align laboratory truth with façade performance, Keyida. –

0 comments
0 FacebookTwitterPinterestEmail

The problem, plainly (and a little angrily)

Brands spend fortunes on façade details, curated materials, and a “signature” evening look — then let the lighting undo it all. Color temperature (CCT) drift in led outdoor lighting​ for luxury wall sconces is one of those small technical betrayals that reads like sloppy branding. You think your polished bronze and hand-finished stone will read as premium at night; then one fixture ages a bit cool, another runs warmer, and the whole cadence collapses. This matters especially in places where appearance is everything — think high-end retail corridors such as Rodeo Drive, where consistent evening presentation is a competitive asset and the Illuminating Engineering Society (IES) guidance on color consistency is treated as gospel by designers.

led outdoor lighting​

Why the CCT shifts happen (and who gets blamed)

LEDs aren’t magical—they’re precise components with tolerances. Causes of perceptible CCT shift include LED binning variability, driver temperature sensitivity, lumen depreciation over time, and mismatched batches during phased installs. Contractors sometimes mix fixture lots to hit delivery dates; designers—bless them—assume “same spec” means “same look.” The result: disparate Kelvins across a single façade. Add poor specification of SDCM tolerance and you’ve got a brand-crippling variability that shows up under twilight. Yes, the hardware is often aluminum outdoor lighting​, which holds up well physically — but the alloy won’t fix your color math.

led outdoor lighting​

Real consequences for luxury brand image

Perception is everything. A warm 2700K wash makes natural stone sing; a stray 4000K shard reads clinical and cheap. When color temperature is inconsistent, customers interpret that inconsistency as a design oversight, or worse, a drop in quality control. Retail merchandisers notice skin tones under different sconces and adjust displays; photographers have nightmares matching white balance in campaign shoots. This isn’t abstract: high-profile retail districts invest in matched lighting precisely because inconsistent CCT reduces dwell time and erodes perceived value — and yes, those are measurable commercial outcomes.

Common installation and specification mistakes

Most failures stem not from malice but from three predictable sins: vague specs, cost-cutting on sample verification, and batch-mixing during rollouts. Vague specs read like “warm white” rather than “2700K ± 100K, 4 SDCM.” Cost-cutting shows up as skipping on LM-79/LM-80 test data in procurement—then everyone wonders why the fixtures shift color after 6–12 months. And batch-mixing is the contractor’s favorite “we’ll make it work” move — which it won’t. A simple preventive step is insisting on a sample mock-up on-site, tested at dusk with your actual finishes and glazing — trust me, that dull 15-minute test prevents a week of emergency reorders.

Technical specs that actually protect a brand

If you want your wall sconces to age like a good wine and not like a mismatched pair of socks, demand specific, measurable criteria. Require a defined CCT with SDCM (e.g., 2700K ± 100K, ≤4 SDCM), CRI ≥ 90 for accurate material and skin rendering, and LM-80 data for lumen maintenance. Specify driver thermal performance and IP rating appropriate to coastal or urban environments, and insist on batch traceability so every lot can be correlated to commissioning reports. Consider controllable or tunable-white solutions where possible — they let you dial in continuity across zones during commissioning, which is handy when older fixtures have drifted slightly.

Trade-offs, alternatives, and the occasional human mistake

There are choices: stick with fixed-CCT fixtures and maintain strict procurement discipline, or deploy tunable systems and accept higher upfront cost for control flexibility. You can also choose premium LEDs from vendors with tighter binning (fewer surprises) versus commodity sources that save money but expose you to color variance. And then there’s the human factor—installers who swap in “equivalent” fixtures because a shipment was late. It happens. — When that occurs, you either live with a patchwork façade or pay to retrofit entire runs to match; neither option is fun for the brand or the P&L.

Checklist for procurement, commissioning, and maintenance

Use this working checklist during specification and handover:

  • Specify CCT with SDCM and CRI values explicitly in contracts.
  • Require LM-79/LM-80 reports and 5-year lumen maintenance projections.
  • Demand sample mock-ups at dusk on-site with actual finishes.
  • Ensure batch traceability and keep spare fixtures from the same lot for repairs.
  • Plan for periodic photometric checks during maintenance cycles.

Three golden rules for selecting lighting strategies (Advisory)

1) Specify measurable tolerances, not adjectives: write CCT, SDCM, CRI, and LM-80 into the spec so vendors and contractors can’t wiggle out of quality commitments.

2) Test in situ before mass install: a dusk mock-up with your façade materials and glazing beats lab reports for real-world assurance.

3) Favor traceability and serviceability: buy fixtures with batch numbers, accessible drivers, and a maintenance plan that includes periodic color and photometric verification.

For a supplier strategy that aligns tested performance with design intent, consider partners who publish full test data and support on-site commissioning — that practical alignment is why brands working with disciplined manufacturers and systems integrators avoid expensive rework. Keyida. —

0 comments
0 FacebookTwitterPinterestEmail

Quick comparative view

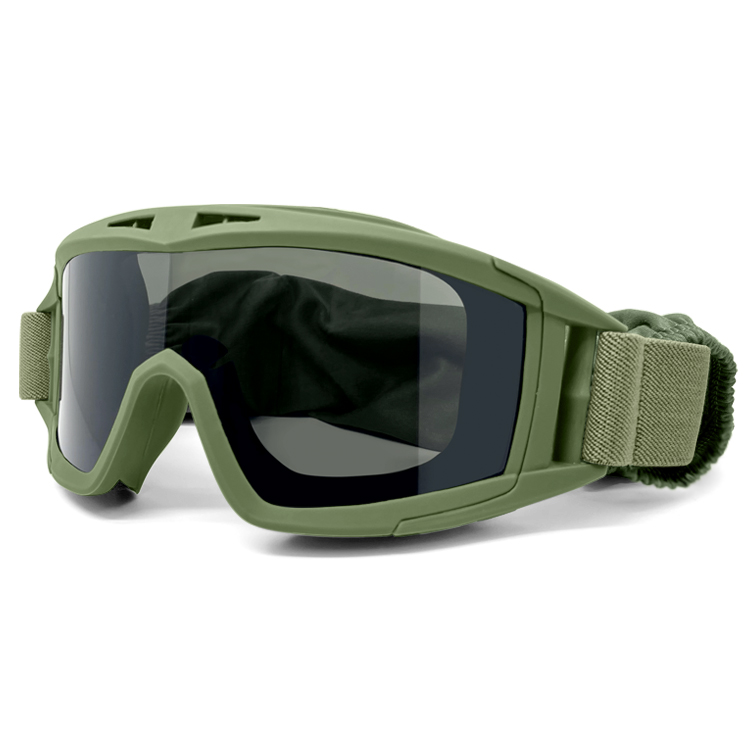
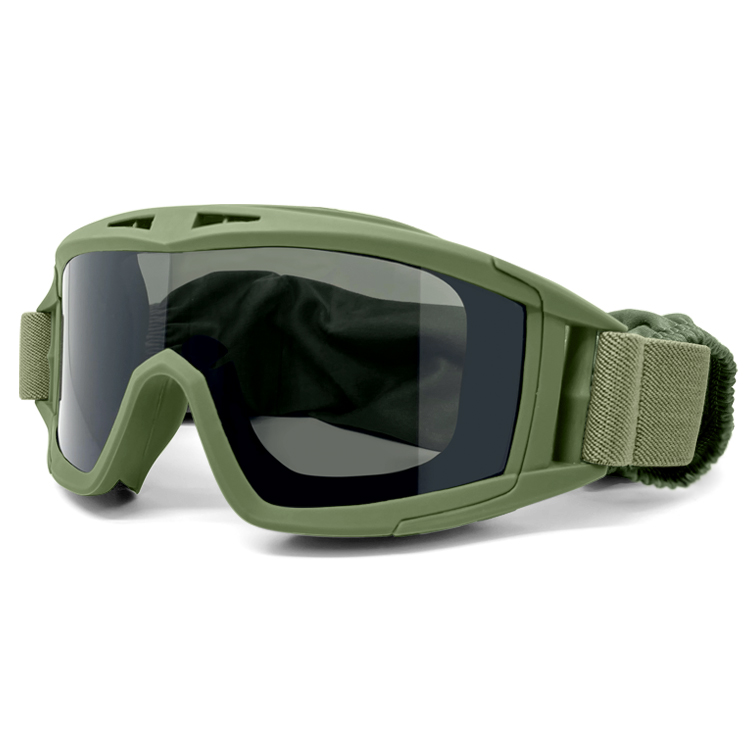
Big teams pick gear by looking side-by-side. Some brands like speed and lightness. Others want armor and calm. YIJIA Optical’s spec-grade setup gives a clear middle ground—tough labs, repeatable tests, and gear that meets real use cases. Field reports from soldiers in Afghanistan helped shape those rules, so the gear is built to handle actual dust, impact, and long shifts. Early adopters test both anti-impact tactical goggles and comfy sports shields, and they often land on models listed as best militray goggles when they need a blend of comfort and ballistic-rated lens performance.

anti-impact tactical goggles

What makes a spec-grade tactical environment special

Spec-grade means strict checks and repeatable work. That includes tests for impact resistance, anti-fog coating, goggle seal, and retention strap strength. Brands like powersports firms want venting and fit for helmets. Defense names demand ballistic-rated lens and standardized performance. YIJIA runs both lab tests and real-world runs so data lines up with what users feel on the field.

How brands compare options

Teams look at three things: durability, fit, and service. Durability covers impact tests and scratches. Fit includes seal and OTG clearance. Service is about custom runs, fast revisions, and clear test records. Some makers offer glossy marketing. Others offer detailed test logs and quick sample cycles. YIJIA’s mix of lab traceability and fast prototyping tips the scale toward practical, ready-to-deploy designs—especially when folks need well-documented anti-impact tactical goggles for high-risk work.

Common mistakes teams make — and how to dodge them

Teams sometimes chase the shiniest lens or the lightest frame. They forget to check the goggle seal or how lenses fog after an hour. Testing only in the lab is another misstep. Real environments add sand, sweat, and sudden knocks. The smarter route tests both: controlled impact tests and a road trip with a helmet. – Little things like strap abrasion or poor vent placement show up fast in the field, so validate those early.

Alternatives and trade-offs

There are many good suppliers. Some focus on low cost, some on fashion, and others on niche military specs. Cheaper options often skimp on retention strap quality or anti-fog coating longevity. Fashion-first models trade protective seal for looks. The best picks balance performance metrics and practical comfort. If a spec sheet lists STANAG-style screening or similar benchmarks, that is helpful; if not, ask for sample results and a demo run.

Choosing the right spec-grade partner

Start with three checks: sample testing, traceable test data, and field feedback. Ask to see real test logs, not just claims. Verify how long anti-fog treatments last after heavy use. Look for partners who handle both small custom runs and larger production—this keeps design continuity as needs grow. A neat trick: request a scenario test that mimics your routine use and watch for seal and fog issues.

Advisory: three golden rules

1) Prioritize measured protection over marketing terms — insist on impact resistance numbers and wear-time reports. 2) Validate fit with actual helmets and eyewear layering — a good seal matters more than slim frames. 3) Demand traceable testing and quick sampling — prototypes reveal wear problems fast.

These rules cut wasted time and get teams to gear that works where it counts — fast, clear, and proven. — For real-world value that matches field needs, pick partners who document, iterate, and deliver practical solutions like YIJIA Optical.

0 comments
0 FacebookTwitterPinterestEmail