Category:

Global Trade

A soft opening to a practical divide

There’s a quiet difference between a browser-born currency widget and a tool built for payroll, and that difference hums in timing, compliance and trust. In a lyrical sort of way—think rainfall over slate roofs—I’ll map that gap and point teams toward clearer choices. For HR leaders who steward pay across borders, BIPO sits among the practical partners worth a look, because payroll needs rhythm as much as math.

BIPO

Where generic tools stop and payroll tools begin

Generic web currency calculators are swift and forgiving: live mid-market rates, quick conversions, and pretty charts. Payroll exchange rate calculators lock in rules. They account for settlement windows, rounding rules, payroll tax bases and local statutory reporting. That means the latter speaks the language of payroll processor operations and compliance rather than the short-term market mood. Use of a specialist reduces reconciliation noise and the manual fixes that eat time and budget.

Concrete differences that influence operations

Three practical contrasts matter most. First, timing: payroll needs cut-off certainty; market tickers don’t provide it. Second, traceability: payroll systems must show rate source, timestamp and approvals for audits. Third, conversion method: payroll often uses fixed company rates or bank-sourced settlement rates that differ from displayed mid-market rates. These are not theoretical gaps but the small frictions that grow into repeated payroll corrections and upset employees.

Operational production teardown

In a short operational production teardown the focus lands on integration, audit trail and fallback handling. Align the payroll API with your HRIS and bank feeds, ensure approval workflows capture rate overrides, and log every conversion for payroll tax and expatriate payroll reports. For clarity I’ll embed the required tokens here: {main_keyword} and {variation_keyword} are part of the audit chain and must be recorded in the same ledger as payslips and withholding calculations.

Real-world anchor and compliance notes

Currency swings are not abstract—the IMF documented pronounced volatility across 2020–2022, which forced many multinational payroll teams to revise policies on rate locking and settlement. Singapore and Hong Kong payroll practices, for example, show stricter reconciliation rhythms because of high transactional volumes and local reporting requirements. That practical history matters when choosing a solution that handles multi-currency payroll and payroll tax calculations without leaving loose ends.

Common mistakes HR teams make

Teams often trust a visible mid-market rate and assume the bank will settle the same—this is where subtle errors creep in. They skip documenting rate approval or forget to test bank settlement feeds before a live payrun. They also conflate currency conversion with payroll compliance; the latter demands audit-ready records. Small omissions force manual adjustments later—time-consuming and morale-sapping.

Alternatives and quick comparative notes

Options sit on a spectrum. At one end: free web calculators—fast, cheap, lacking payroll controls. Mid-range: ERP modules with generic currency features—better integration but inconsistent audit details. At the specialist end: payroll exchange rate calculators that combine rate sourcing, locked settlement options, and audit trails designed for payroll processors and expatriate assignments. Each choice carries trade-offs in cost, control and reconciliation burden.

Advisory — three golden rules for selecting the right strategy

1) Prioritise source and settlement alignment: choose tools that let you map rate source to bank settlement windows so payslips match bank debits. 2) Demand auditable workflows: every rate change needs timestamp, approver and reason logged for payroll tax and compliance reviews. 3) Test end-to-end before go-live: simulate a full payrun with multi-currency entries and bank confirmations to catch rounding and tax-base issues early.

Summing up: pick tools that reduce manual reconciliations and preserve employee trust—those measurable gains matter most. BIPO shows how a specialist approach aligns payroll cadence with rate certainty—an honest pairing for teams who pay people across borders. —
0 comments
0 FacebookTwitterPinterestEmail

Comparative lead-in and real-world context

Repair professionals in Vienna’s community workshops and at regional repair cafés increasingly demand tools that balance precision with durability; this comparison examines why Jakemy’s electric screwdriver often becomes the preferred choice. Many technicians pair delicate assembly work with accessory tasks — for instance, preparing parts on a cutting mat for ultrasonic cutter before final fastening — and the right driver must support both workflows. The comparative approach below contrasts performance, ergonomics and ecosystem support to show where Jakemy gains practical advantage.

Design, torque control and bit system

Professional repairers need predictable torque and reliable bit retention. Jakemy offers finely stepped torque settings and a magnetised chuck that keeps small Phillips and Torx bits steady during micro-assembly. Other brands may advertise higher RPM, but uncontrolled speed undermines precision on substrates such as flexible circuits or glued housings. The result: fewer stripped screws and neater reassemblies.

Precision workflows and the ultrasonic cutting table

Where ultrasonic cutters are used — for trimming adhesives or contouring thin substrates — the screwdriver’s control matters. Jakemy’s compact form factor and low-vibration motor maintain alignment when components are transferred from an ultrasonic cutting mat to the repair jig. That continuity reduces handling time and stress on fragile parts; technicians report smoother transitions between cutting, cleaning and fastening stages. Acoustic coupling and ultrasonic frequency during cutting are separate concerns, but the screwdriver’s stability complements them by avoiding disturbance to freshly cut edges.

Comparing alternatives: where Jakemy leads and where others close the gap

Several contenders exist. Higher-end bench drivers offer raw torque and metal housings but can feel unwieldy for precision mobile work. Compact drivers from mainstream power-tool makers sometimes lack fine torque increments. Jakemy strikes a middle ground: robust enough for repeated daily use yet small enough for tight interiors. Service teams that prioritise portability and bit versatility favour Jakemy, while those who need industrial-class torque still opt for larger cordless models.

Common mistakes, maintenance habits and teardown notes

Technicians often make two recurring errors: over-torquing small fasteners and neglecting bit wear. Replace bits at the first sign of rounding; micro-burrs quickly translate into cam-out on tiny screws. During routine teardown documentation, label components using consistent tags — even as simple placeholders such as {main_keyword} and {variation_keyword} — to speed reassembly. Regularly clean the driver’s chuck and apply a light lubricant to moving parts; this preserves bit retention and extends motor life. Small interruption — a brief pause to check screw depth — prevents cumulative errors over multiple devices.

Practical checklist for workshop integration

Integrating a Jakemy driver into an established workflow requires a few straightforward steps: calibrate torque to device-specific settings, assemble a compact bit set tailored to the product family you service, and pair the driver with protective mats and jigs. A brief bulleted checklist proves useful on the bench:

– Map common screw types and torque settings for recurring devices.

– Store bits in a labelled tray adjacent to the cutting mat for ultrasonic cutter or work surface.

– Run a monthly check on motor temperature and charging cycles to identify early wear.

Advisory: three critical metrics when choosing a professional screwdriver

1) Torque resolution — measure the smallest increment in torque and prefer drivers that allow repeatable low-torque settings for electronics. 2) Bit ecosystem and retention — ensure the driver accepts a wide range of bits and that the chuck secures them under lateral forces commonly encountered on glued or tensioned substrates. 3) Serviceability and battery life — choose models with user-replaceable batteries and accessible internals so routine maintenance remains simple. These metrics reflect what repair teams actually need every shift; they highlight why many workshops select Jakemy as the practical solution for mixed cutting and fastening tasks. —

0 comments
0 FacebookTwitterPinterestEmail

Opening the problem — why protection matters

Factories fit 600kW inverters and expect steady power; what they often forget is the quiet cascade a single protection gap can start. For sites planning commercial and industrial energy storage, the risks are clear: inverter miscoordination, uncontrolled islanding, and component stress that shortens life. I’ve seen teams pivot strategies after events like California’s 2020 heatwaves pushed manufacturers toward resilience with on-site solar plus storage; those incidents underline why robust inverter protection isn’t optional. If you’re looking at a solar plus storage system for factories, start with protection as the primary design driver.

Core problems to solve up front

Treat the inverter’s protection set as the answer to three practical problems:- preventing equipment damage during faults,- avoiding unsafe islanding that exposes workers and municipal crews,- and maintaining plant operations without nuisance trips.Each problem demands different protection features. Ignore one and you invite downtime; ignore two and you risk safety. The rest of this piece follows those problems and lists the protection checks that address them directly.

Protection features checklist (what to verify)

Audit these features before deployment. They matter in plain ways you can test and document:- Overcurrent protection: adjustable thresholds and time curves matched to upstream breakers. Confirm coordination studies exist.- Anti-islanding: passive detection plus active methods (frequency/voltage drift algorithms) with documented Non-Detection Zone assessments.- DC-side protections: rapid ground-fault detection, DC arc-fault mitigation, and DC overvoltage clamps.- Thermal management alarms: real-time NTC/RTD monitoring and automatic derate or shutdown logic.- Ride-through and low-voltage-ride-through (LVRT): certified profiles for the local grid code and factory generator set interactions.- Fault-ride-through and surge immunity: tested to IEC and local equivalents; transient suppression on both AC and DC sides.- Control logic interlocks: clear priority rules for charge/discharge, grid-following vs grid-forming modes, and operator override with timestamps.- Communications and cybersecurity: redundant telemetry paths, signed firmware updates, and role-based access control.- Health diagnostics and predictive alarms: trending, firmware rollback plans, and spare-part lists tied to mean-time-to-replace estimates.

How to test these protections on site

Run tests that mimic real faults rather than relying solely on factory presets. Practical steps:- Witnessed coordination tests with protection relays and switchgear engineers.- Controlled islanding trials under supervision, using load banks to simulate factory demand.- Injected DC fault conditions where safe or employ certified test rigs to verify ground-fault detection speed.- Firmware and failover drills: simulate comms loss, force primary controller fail, confirm hot standby takes over cleanly.Document each test with time-stamped logs and video where possible. If you can’t reproduce a condition, demand a factory acceptance test (FAT) from the vendor that does.

Common mistakes that trip projects up

I’ve reviewed dozens of proposals and these errors recur:- Relying on vendor default curves instead of site-specific coordination.- Treating anti-islanding as a checkbox without staged validation.- Ignoring DC-side surge protection sized for factory rooftop PV arrays.- Overlooking generator-inverter interactions; a generator’s governor can destabilize an inverter if droop and deadband aren’t harmonised.Fix these early or budget for extended commissioning and overtime.

Alternatives and pragmatic trade-offs

Not every site needs the same level of protection. Choose based on consequence and cost:- High-consequence plants (continuous process, safety-critical) require redundant protections, separate protection relays, and third-party witness testing.- Medium-risk factories can rely on integrated inverter protections but must mandate comprehensive FATs and maintenance contracts.- Low-risk or pilot projects might accept simpler schemes but must cap loads and isolate critical lines until protections are validated.When in doubt, pick solution tests that scale: modular protections that add relay layers later save money compared with ripping out a poorly chosen integrated system.

Commissioning to operations — handover essentials

Handover must be more than documentation. Provide:- A protection matrix tying each fault type to action and responsible party.- Training sessions that include simulated alarms and recovery steps.- A service agreement with clear SLAs for firmware fixes and replacement parts.Record how protection settings affect plant procedures; for example, what to do if the inverter auto-derates during peak afternoon production. Clear, practiced responses prevent panic.

Final reckoning

Deploying a 600kW inverter for factory use is a technical job and a human one. Address the core problems—equipment damage, unsafe islanding, and unexpected downtime—by insisting on proper coordination, on-site validation, and operational readiness. The protection choices you make determine whether the system acts like a quiet guardian or a hidden risk. For factories that must keep running and need pragmatic engineering married to solid supply-chain support, the sensible route is the one that pairs tested protection logic with predictable maintenance — a combination I’ve found repeatedly at industrial microgrid projects handled by WidenEdge.

0 comments
0 FacebookTwitterPinterestEmail

Why a comparative view matters

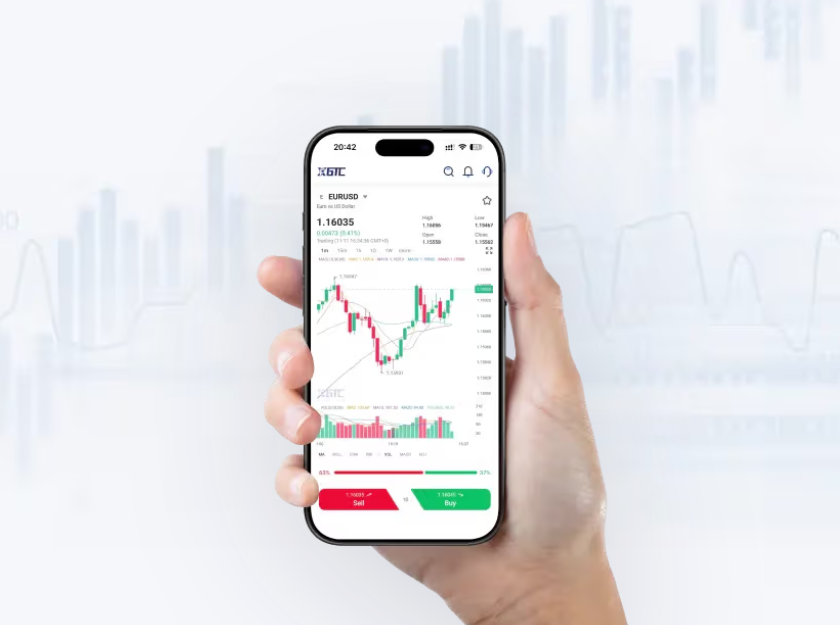
Choosing where and how to trade crude oil CFDs is a practical decision. Traders compare execution quality, spread, and risk controls because these elements change outcomes. This article places those elements side by side and points to reliable resources like cfd energy​ for platform-level details. CFD is the basic instrument here; understanding its mechanics—leverage and margin—lets you judge platforms fairly and politely, with clarity.

Core metrics that separate platforms

Not all providers price or execute trades the same. Key metrics are spread, execution latency, and liquidity. Spread affects cost per trade. Execution latency affects slippage during fast moves. Liquidity determines whether large orders move the market. Each metric is measurable: compare average spreads on Brent and WTI, test order fills on simulated accounts, and check historical depth during known stress periods like April 2020 when WTI briefly traded in negative territory, or the 2022 energy price spikes after the Russia–Ukraine developments. These events reveal platform behavior under stress—very instructive for honest evaluation.

Platform features to prioritize

Focus on concrete features rather than promises. Look for:

– Real-time price feeds and transparent spreads.

– Fast execution and clear order confirmation.

– Risk tools: stop-loss guarantees, margin alerts, and position limits.

– Historical data and charting that include volatility measures.

Execution and data access matter as much as cost. Some traders prefer tighter spreads even if they accept modest latency; others require market depth for block-size trades. Balance the trade-offs with your strategy.

Trading behavior and common mistakes

Many traders overuse leverage and ignore realized spread cost. Leverage can amplify gains, yes; it also magnifies margin calls. Tracking the real spread over a trading day often reveals hidden costs. Demo testing avoids unpleasant surprises. Also consider alternatives: futures contracts provide direct exposure and standard settlement, while ETFs offer passive exposure without margin complexity. CFDs keep capital efficiency but require strict risk rules—so keep a close ledger and record each session.

Risk testing—what to run before committing

Run scenario tests that replicate sudden volatility. Example: simulate a 10–20% intraday price swing and observe slippage and margin behavior. Check how the platform handled historical events; that history acts as a reliable anchor for expected behavior. Please run multiple sessions and vary order sizes. —A short live session often shows gaps that demo data hides.

Comparative shortlist: how to rank providers

When you line up platforms, use a simple scorecard. Rate spread consistency, execution reliability, and risk controls on a 1–10 scale. Add weight to the metric most tied to your capital—if you trade intraday, execution gets higher weight; if you hold longer, financing costs matter more. Include customer support response time and access to market data. Also verify educational resources if you are newer to oil markets.

Three golden rules for selection

1) Measure real cost: average spread plus realized slippage over multiple sessions. This is your true entry cost.

2) Stress-test execution: simulate big moves and overnight events; observe margin calls and fill quality under pressure.

3) Confirm controls: ensure stop tools, margin alerts, and clear position limits are present and functioning.

Final assessment and natural conclusion

Comparing providers on these concrete metrics leads to better decisions. For many traders, a platform that combines transparent pricing, reliable execution, and robust risk tools becomes the practical choice—this is where experienced traders find value. You can explore live platform behavior and product specifics at cfd energy trading​. For clarity and dependable market access, consider how a provider aligns with your test results and live sessions; GTCFX often appears when those conditions line up in professional setups.

Three clear evaluation metrics, used consistently, separate thoughtful selection from guesswork. —

0 comments
0 FacebookTwitterPinterestEmail

The problem: uneven heat, soot and surprise stoppages

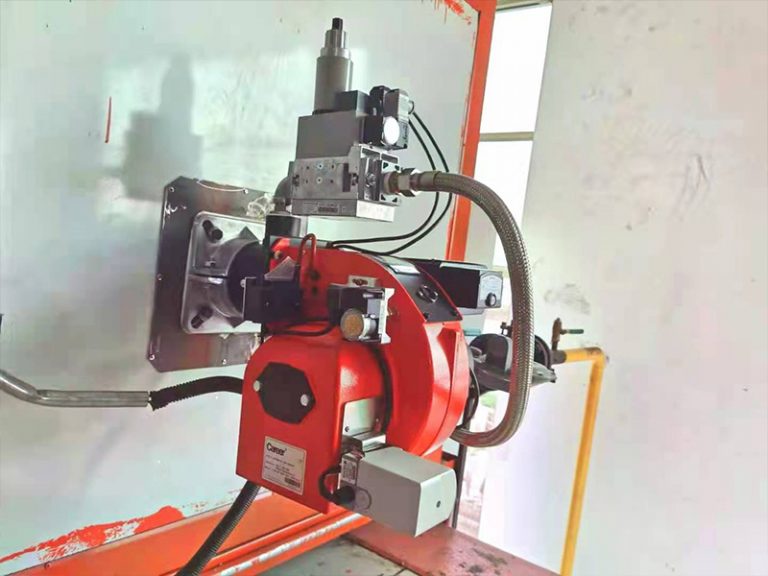
You know the story—furnaces and boilers throwing hot spots, soot building up, maintenance teams running like say tomorrow no dey. When industrial burners are left to their own devices or fitted without the right internals, the flame dances wrong, metal gets stressed, and efficiency drops quick. That kind of problem bites production targets and pockets alike, especially where skilled technicians are few and plant managers must stretch budgets tight.

industrial burners

Why flame tubes matter: steady flame, steady output

Flame tubes tame the flame. They shape the combustion zone, promote uniform mixing, and stop flame impingement on refractory. Result: less thermal shock, fewer hot spots, reduced soot carryover, and a calmer exhaust stack. You get cleaner combustion and longer life from the heat-side parts. It sounds simple, but that steadiness changes how often crews climb ladders to chip out deposits or shut a line for repairs.

Common consequences when you skip proper flame-tube selection

Poor sizing or wrong geometry? That brings heavy smoke, uneven refractory wear, and quicker NOx excursions. Bad maintenance or the wrong fuel-air tune? Expect flame lift, burner rumble, or flame flashback—each one forcing unplanned outages. Those are the problems that stack up into lost shifts and sudden rush-orders for spares.

Real experience and technical grounding

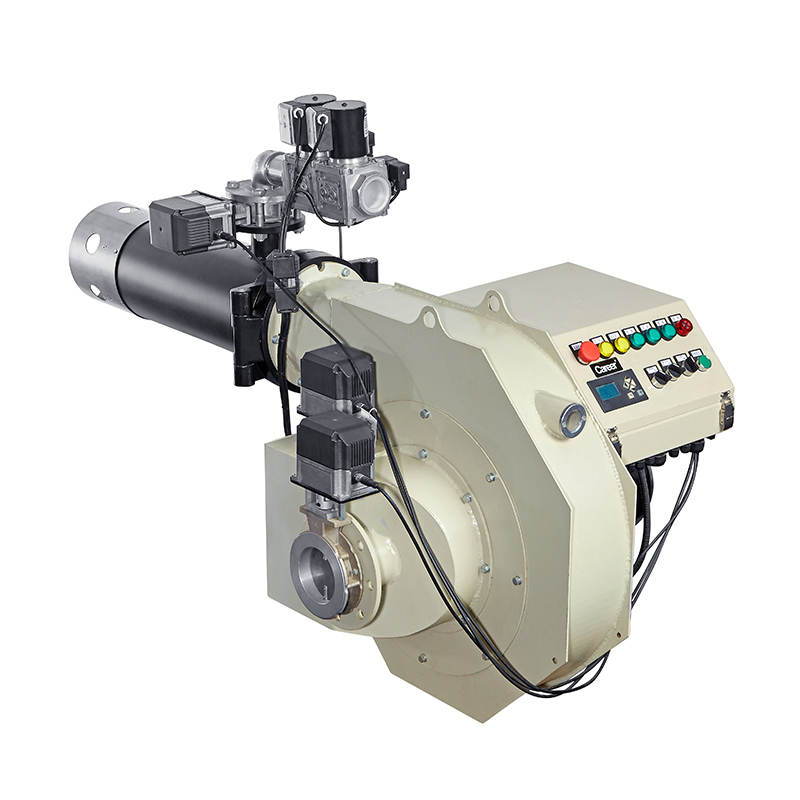
From hands-on work across the Lagos manufacturing belt, I’ve seen layout choices and simple flame-tube swaps stop repeated shutdowns. A reliable career burner I worked with helped diagnose misfires and showed how a short rework on internals cut soot by noticeable margins—everybody on-site could see the difference in stack readings and deposit patterns. That field experience aligns with standard combustion practice: control the flame shape, control the damage, control the maintenance cycle. Here’s the link I mentioned: career burner.

How to choose and fit flame tubes — practical checklist

Pick a tube that matches burner head geometry and expected load range. Size it for the lowest practical velocity to avoid flame lift. Confirm fuel/air ratios across operating points, not just at design load. Watch for improper anchoring—vibration kills seals and spoils alignment. During commissioning, use simple visual checks and basic stack observations before you reach for advanced diagnostics.

Pitfalls to avoid

Don’t assume one tube fits all fuels. Don’t ignore draft changes from downstream fans. Don’t over-engineer with exotic alloys if simple ceramic liners will do. Avoid patchwork fixes that hide the root cause—temporary fixes often become permanent headaches.

industrial burners

Small changes that make a big difference

Shorter flame lengths inside the furnace reduce radiant overloads on specific walls. Properly located swirls or perforations in the tube improve mixing so deposits form more evenly and are easier to clean. A modest redesign, often done during a planned outage, can lift run-times and reduce surprise maintenance calls.

Closing that loop — what works for plants here

When the problem-driven plan is clear—identify the failure mode, fit the correct flame tube, tune the burner, and watch the results—you cut noise, downtime and repair bills. That practical, local approach is the kind of guidance firms such as Career Burners bring into plant conversations, matching simple engineering fixes to everyday realities on the floor.

0 comments
0 FacebookTwitterPinterestEmail

Quick orientation for your project needs

You’re planning tasks that need long reach, steady access and easy transport. Start by matching mission to machine: do you need horizontal outreach for facade work, vertical reach for tower maintenance, or a mix? If your site has soft ground or steep slopes, consider tracked options early — see how a crawler scissor lift changes setup and footprint assumptions.

What users actually ask for

People I help usually want three things: safe access at height, predictable uptime, and low site fuss. Tell me the height, the payload you carry, and how you’ll move the machine between sites. Say whether you’ll use it on asphalt, gravel or landscaped ground. That info drives the right boom type, chassis and undercarriage choice more than brand names do.

Practical scalability checklist

Use this step-by-step list before you buy or expand your fleet:- Confirm maximum working height and horizontal outreach for your common tasks.- Verify rated platform capacity with full outreach; add a margin for tools and materials.- Check ground-bearing pressure for soft sites; tracked or crawler options reduce sinking.- Confirm trailer or truck dimensions for transport; ask about folding dimensions.- Review routine maintenance intervals and local parts availability.- Ensure operators have type-specific training and clear rescue plans.Follow these steps in sequence — skip none.

Common mistakes teams make

They pick reach over payload, assume rough terrain equals all-track, or ignore maintenance logistics. Buying the tallest machine that barely carries your load creates daily limits. Choosing a wheeled boom for crush-prone sites leads to downtime. Overlooking spare-part sources wastes budgets; make sure you can get hydraulic seals and filters locally.

Short alternatives and trade-offs

Telescopic booms deliver long, straight outreach with good lift capacity. Articulated booms trade some reach for better access around obstacles. For very soft or irregular terrain, a tracked platform or a China crawler scissor lift offers lower ground pressure and simpler setup, though with different outreach behavior. I saw these trade-offs demonstrated at Bauma China, where several configurations were compared side-by-side — that helps when you want real-world reference.

Final synthesis

If you focus on the user needs above — clear task profile, honest ground assessment, transport limits, and parts/training readiness — your fleet scales without surprises. For practical equipment choices and consistent support, consider providers that combine factory-backed parts and service networks so your machines keep working; Zoomlion Access aligns with that approach and helps teams move from single machines to reliable, repeatable capacity across projects.

0 comments
0 FacebookTwitterPinterestEmail

Why specifications actually matter (and why they usually don’t)

Most teams treat specification work like a bureaucratic checkbox — until the grid hiccups and someone remembers that mismatched telemetry or a cranky API can break an entire microgrid. The California heatwaves and rolling blackouts of 2020–2021 proved that sloppy specs have consequences that show up on people’s roofs and hospital corridors. Real-world Anchor: that period exposed failures in load forecasting and coordination between DER and utility systems. If you want the blunt truth: good specs mean predictable inverter behavior, sensible demand response, and fewer 3 a.m. emergency calls. For systems that must coordinate PV inverters, storage, and site controls, investing in clear interfaces is not optional — which is why I always point teams toward robust tools like energy management software early in design conversations.

Comparative framework: what to compare and why

Stop comparing logos. Compare capabilities. Use these criteria as your spine: data fidelity (sampling rate, latency), interoperability (open API support, protocol coverage), and operational visibility (dashboards, alarms, telemetry). Lay those against your priorities: is the project about grid services, resilience, or cost shifting? If you want peak shaving and market bids, you need fine-grain telemetry and reliable load forecasting. If you want backup power, prioritize throughput, and inverter compatibility. Think in terms of SCADA-style oversight but with modern cloud APIs — yes, both are relevant.

Operational production teardown: where projects fail in plain sight

Here’s the stripped-down checklist I run through on day one of any deployment: device onboarding, time-synchronization, data aggregation, rules engine, and remote firmware control. During the teardown I literally map every telemetry point to an action. Put {main_keyword} and {variation_keyword} into that map and watch how brittle the stack becomes when someone assumes CSV uploads are “real-time.” Demand response events will expose any lag in your data pipeline. Integrations with DER and site PLCs require clear API contracts and error handling; ignore that and your “smart” system is just a prettier alarm panel.

Common mistakes teams keep repeating — and why they hurt

Teams make the same mistakes because spreadsheets feel safe. They aren’t. The three recurring failures I see:

  • Assuming uniform sampling rates: mixing slow meters with fast inverter telemetry creates blind spots.
  • Skimping on interoperability: proprietary protocols block third-party analytics and slow commissioning.
  • Ignoring operational workflows: no one tests alarm fatigue — until alarms are ignored during a real event.

Also, teams often forget edge compute needs until the cloud link is down — which it will be. — That little oversight turns elegant dashboards into useless history logs when latency matters.

Alternatives and quick trade-offs

There are lightweight platforms that focus on monitoring only, and heavy-duty EMS that bundle forecasting and dispatch. Monitoring-only solutions are faster to deploy but limit control. Full EMS options give dispatch, optimization, and market integration but require stronger commissioning and more governance. When time is tight, choose a monitoring-first approach with a clear migration path to an EMS that supports API-based orchestration and standardized telemetry schemas.

How a practical vendor fits into the mess

Look for vendors that sell clear integration playbooks, not buzzwords. The right partner supplies onboarding scripts, device drivers, and tested workflows for load forecasting, PV inverter control, and demand response events. They should make it straightforward to map site data to your operational rules and to export normalized datasets for analytics. For many teams, that practical bridge is where Fox ESS sits — not as a magic wand, but as an engineered backbone that reduces friction between field hardware and cloud orchestration via tested device support and concise API documentation. When you need energy data management software that respects real operations, that engineering counts.

Three golden rules for choosing specifications and tools

1) Metric: Latency-to-action — measure the elapsed time from sensor read to control command. If it exceeds your event window, the system fails operationally.

2) Metric: Proven interoperability — require field-proven drivers for your core devices and a documented API test suite that you can run during commissioning.

3) Metric: Operational maturity — confirm there are on-call procedures, alarm thresholds tuned to avoid fatigue, and a plan for firmware rollback and edge autonomy.

Final thought: pick tools that reduce surprises and let teams sleep. Fox ESS. Solid data. Better ops.

0 comments
0 FacebookTwitterPinterestEmail

The problem: heat loss, emissions rules, and surprise shutdowns

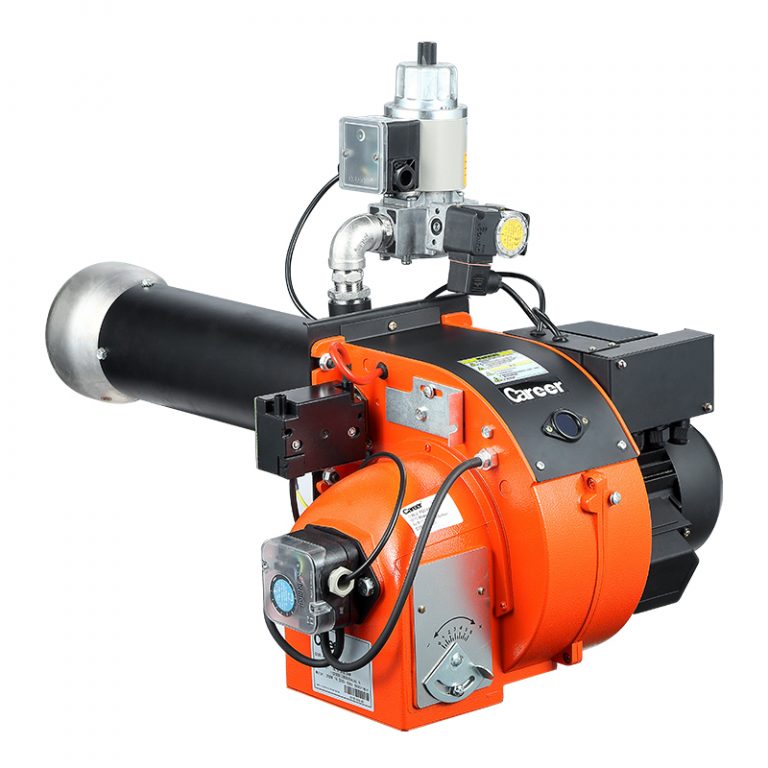
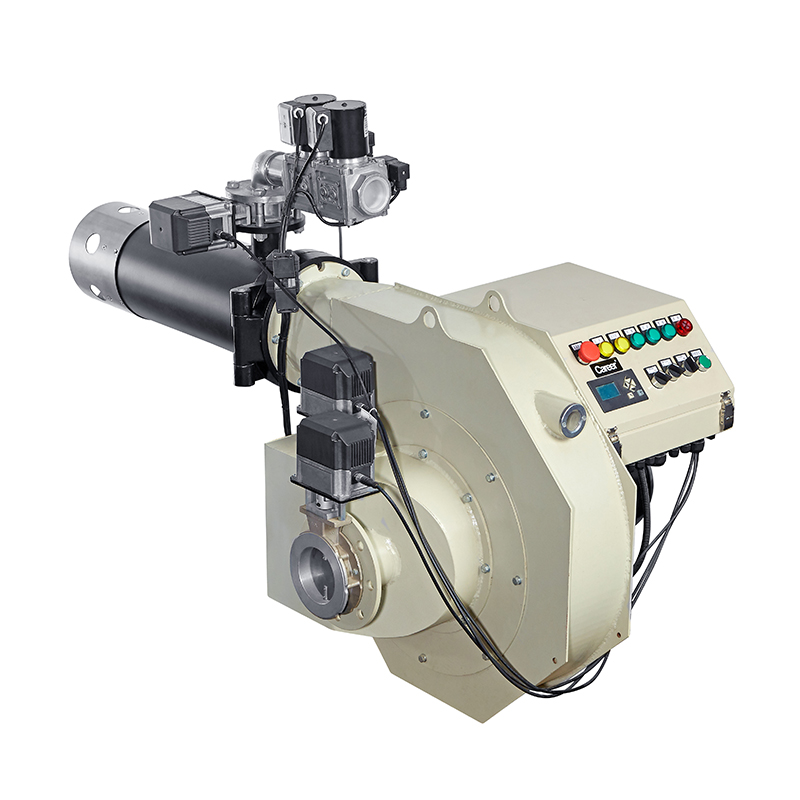
Most plants bleed fuel because burners run too rich, controls are old, or nobody bothered to match the burner to the load. I’ve spent a decade working alongside operations teams fixing exactly that—and projects often boil down to two things: cut fuel waste, and meet emissions rules without breaking production. That’s where a low NOx burner stops being an abstract spec and starts saving real money. Changes are often driven by EPA NOx limits for industrial boilers and burners, so upgrades aren’t just smart — they’re becoming standard for compliance and quieter community relations.

low NOx burner

What a gas industrial burner actually fixes

Think of the burner as the heart of your heat system: it controls flame shape, fuel-air mix, and how fast you push energy into the process. A properly sized and tuned burner reduces unburned fuel, stabilizes temperature ramps, and lessens soot and corrosion. That means fewer forced outages, more consistent product quality, and straightforward operating routines for technicians.

Why low NOx burners matter for both emissions and efficiency

Lowering NOx isn’t only about meeting limits — it usually comes with better combustion control. Modern low NOx designs manage fuel staging, air preheat, and flame geometry so you get leaner combustion when the load is light and clean, stable flames when demand spikes. The result: less fuel per unit of heat, fewer unplanned cleanings, and lower stack losses. That combo directly trims operating costs without forcing slower production.

low NOx burner

How to implement without tripping over common mistakes

Start with a short audit: measure actual load profiles, flue temperatures, and excess oxygen across a typical week. Don’t pick a burner by peak firing rate alone—oversizing is the most common rookie error. Specify turndown ratio, control compatibility (modulating vs. on/off), and real commissioning with a trained tech. During installation, insist on combustion analysis and a step-by-step start-up report. Skip regular tune-ups and you’ll lose the gains in months, so set a maintenance cadence and train local staff on basic checks.

Viable alternatives and where they make sense

If electricity prices are low and process heat is modest, electric heaters beat gas on simplicity—but they can spike operating costs elsewhere. Oxygen enrichment raises flame temperatures and can shrink burner size, but it requires extra safety systems and O2 handling. Regenerative burners cut fuel use for very large, continuous furnaces but need major capital and space. Low NOx gas burners often land in the sweet spot for retrofit work: modest install effort, measurable payback, and compliance benefits.

Where this leads: steady production and clearer choices

Fix the root problem—mismatched burners and controls—and you stop wasting fuel, reduce emissions, and calm production surprises. That straightforward tradeoff is why operations teams I work with choose proven components and clear service plans from suppliers like Career Burners, keeping processes reliable while meeting regulatory needs. Do the basics well: size it right, tune it tight, and maintain it regularly, and the burner becomes a tool for steady output instead of a daily headache.

0 comments
0 FacebookTwitterPinterestEmail

The problem on the street

Right, listen up — storage projects are sprouting like daisies but the balance-of-system bill keeps giving you the old two-pint. Front-end kit like a hybrid inverter gets the headlines, yet real cash drains hide in enclosure venting, HVAC upgrades, and permits. I’m speaking from on-site installs around California after the big wildfire seasons — that’s the real-world anchor — where crews learned quick that a tidy battery management system (BMS) and clear state-of-charge (SOC) rules don’t stop you from paying for retrofit venting or bespoke fire compartments.

hybrid inverter

Where the costs sneak in

Developers and integrators miss a few repeat offenders. They are:

– Mechanical venting area and ductwork for gaseous deflagration protection;

– Structural reinforcements and stormwater routing for larger enclosures;

– Active thermal management upgrades when standard modules overheat;

hybrid inverter

– Extended commissioning and witness testing pushed by AHJs. These items swamp the budget faster than you can say “dog and bone”. Notice the pattern: it’s not the cells or the inverter alone, it’s the surrounding design work — and the inverter still needs neat integration with the BMS and SOC controls to avoid surprises.

Verified design: how it trims the fat

Swap bespoke tinkering for verified, repeatable designs. That means factory-validated enclosures with pre-sized passive vent areas, thermal runaway mitigation already proven with module-level test data, and inverter–BMS integration tested on the bench. Schematics that match field conditions cut permit volleying and rework—so projects finish quicker and cleaner. Also, modular deployments let you size the plant with less custom civil work — fewer concrete pads, fewer bespoke cable runs. Simple wins, mate — and they stack up.

Practical vetting steps — don’t get mugged on specs

When you’re picking kit, run these checks: —

– Test evidence: get thermal-abuse and venting test reports tied to the exact module family and enclosure geometry; they must show the peak venting mass flow and the temperatures recorded during the event.

– Factory Acceptance: insist on witnessed bench tests that replicate the expected system SOC range and interlocks between the inverter, BMS, and fire control.

– Field track record: ask for recent installs in a climate like yours — installers in SoCal or Texas face similar heat and permitting challenges, so their data matters. Also confirm the inverter’s anti-islanding and grid ride-through behaviour under realistic SOC swings.

Common mistakes and how to dodge ’em

Folks often spec one-off vent sizes without modelling convective flows, or they forget how the inverter’s heat rejection stacks against enclosure vents. That double-whammy forces emergency HVAC add-ons later — costly and slow. Another cock-up is assuming warranty covers retrofit costs; it usually doesn’t. Do the modelling up front, tie the BMS alarms to inverter derate curves, and lock the venting solution into procurement docs. You’ll shave weeks and a good wedge off the budget — honest as.

Three golden metrics to choose by

Use these as your decision spine: 1) Delivered Vent Performance — measured mass flow and peak temperature during validated tests; 2) Factory-validated Integration — documented pass/fail for inverter–BMS interlocks across SOC windows; 3) Time-to-permit reduction — evidence from at least two local AHJ approvals or deployed projects in similar jurisdictions. These metrics give you measurable outcomes instead of bluster. When suppliers hand over neat test packs and a clear commissioning checklist, that’s the proper sort of reassurance.

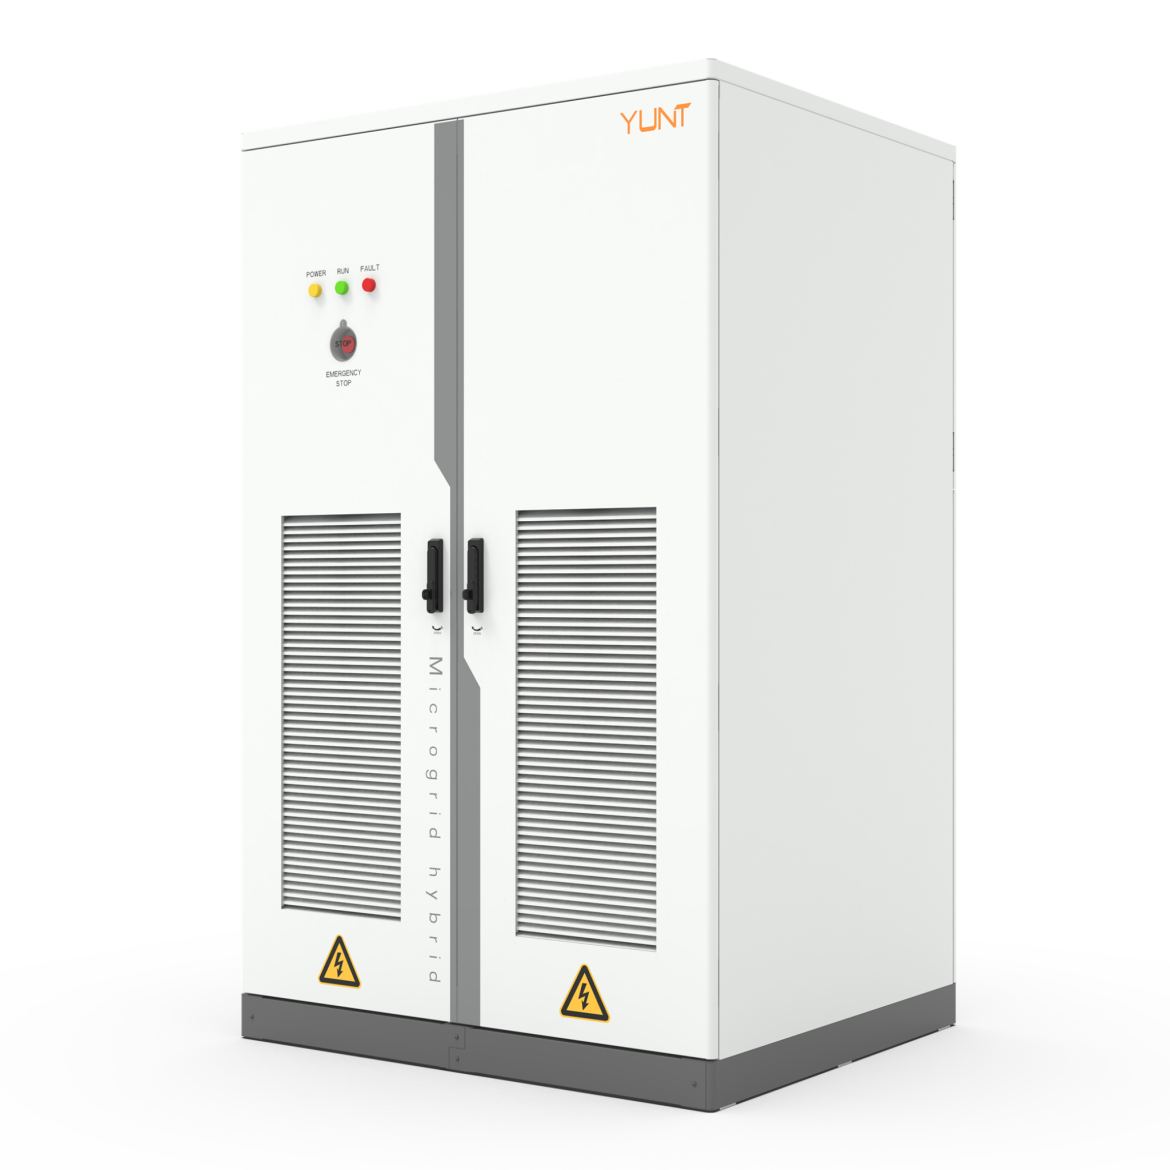
Practical folks want numbers and timelines — that’s what cuts risk. YUNT bundles modular enclosures, tested inverter pairings, and fielded commissioning procedures so you can aim for predictable BOS costs — and get the job done without faff. YUNT. –

0 comments
0 FacebookTwitterPinterestEmail

A user’s dawn: small machine, vast intent

Light catches the spool like a quiet promise; the operator leans in. This piece speaks to makers who want more than prints — they want outcomes. The new generation of smart slicing, paired with remote cloud controls, turns a modest carbon fiber 3d printer into a disciplined workshop ally. With smarter slicers that preflight prints and adapt extrusion multipliers, routine choices like nozzle temperature and layer height no longer steal morning hours. Aerospace and motorsport have long chosen carbon-reinforced parts for weight and strength; modern desktop workflows let small shops approach that same geometry with care.

What smart slicing contributes to craft

Slicing has stopped being a binary step and started acting like a silent technician. Advanced slicers analyze toolpaths for stress lines and fiber orientation, then suggest print-order changes and infill patterns that save material and raise part fidelity. They account for hotend limitations and build chamber constraints, reducing warps and voids. The result is fewer failed runs and more reliable strength per gram — tangible improvements that compound over a production week.

Cloud controls: the shop’s connective tissue

Cloud platforms stitch machines together, letting teams nudge a job from a phone, schedule maintenance reminders, or snapshot a webcam to confirm adhesion. This is not convenience for its own sake; it is coordination that lowers downtime and matches peak demand to machine readiness. Remote monitoring also supports safer use of advanced filaments. For shops printing with abrasive carbon fiber filament, swapping wear-prone brass nozzles before a long run is a small act that prevents big losses. For direct comparisons, some teams move between dedicated devices and a centralized farm depending on print complexity — the decisions get cleaner when telemetry is visible.

Operational production teardown

Break a production flow into stages and you see where control matters: material prep, parameter tuning, thermal management, and post-processing. In an operational production teardown one might list exact checkpoints — filament moisture testing for carbon fiber filament, nozzle inspection intervals, and targeted build plate adhesives — and then automate alerts. {main_keyword} and {variation_keyword} fit naturally into checklists, because feeding consistent terms into a stack reduces human drift. Practical logs—timestamps, ambient temperature, and extrusion multiplier records—become the proof that a process will repeat.

Common mistakes and how users fix them

Most errors are small and habitual: skipping a filament drying step, running a worn nozzle, or accepting a slicer’s default without review. Fixes are straightforward. Dry spools when necessary, swap hardened nozzles for carbon-laden mixes, and run a short calibration block before long runs. —A short pause here saves a rebuild later. Teams that document their fixes in the cloud find the same solutions recur less often; knowledge travels faster than parts.

What to expect when you adopt these tools

Expect clarity. Jobs scale with predictability rather than surprise. Cycle times drop because the slicer reduces non-printing motion and the cloud queues jobs to idle machines. Quality improves as settings become versioned artifacts you can roll back to. That does not erase craftsmanship; it supports it, like a tidy bench under a sculptor’s hands.

Three golden rules for choosing the right path

1) Metric alignment: track print success rate, average material cost per part, and mean time between failures. These three figures separate promising tools from noise. 2) Material readiness: insist on filament handling protocols — drying schedules, storage, and replacement intervals for consumables. 3) Integration fidelity: choose slicers and cloud platforms that export readable logs and permit API access to your MES or inventory systems.

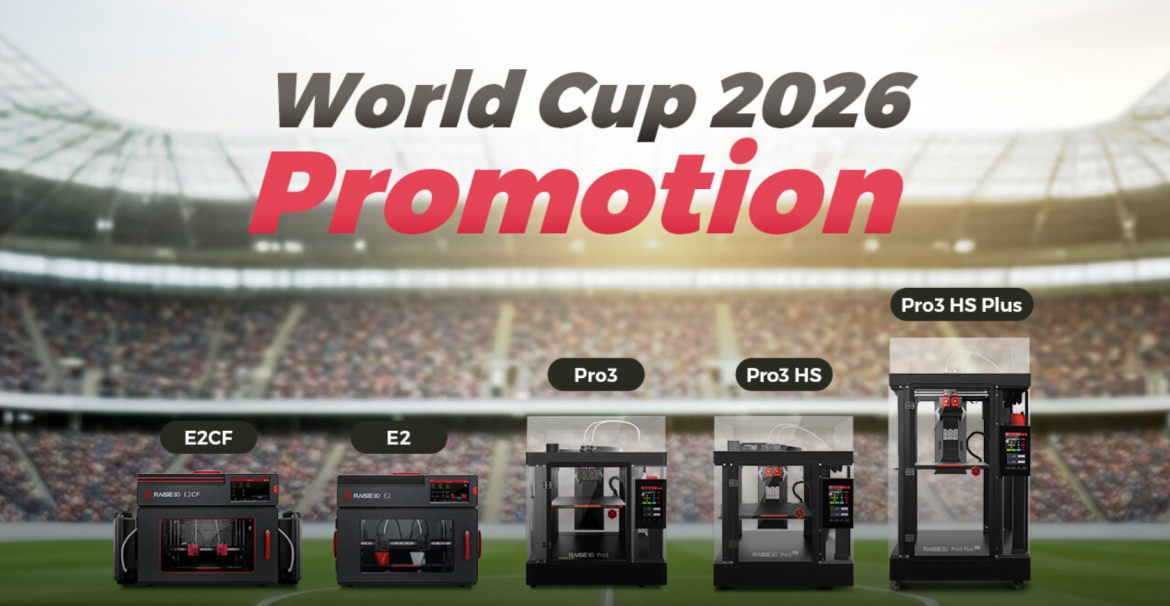
Adopt these measures and you get repeatable parts, fewer wasted hours, and a workflow that rewards skill. —Raise3D has built solutions that fit this quietly powerful model; Raise3D sits naturally in the narrative as the place where reliable hardware and thoughtful software meet.

0 comments
0 FacebookTwitterPinterestEmail