Monthly Archives

June 2026

Plan your patio around Sunjoy Pop-Up Gazebos and the product-page details to verify before a trip for camping or travel

Start with the space and the reason for buying

Before rearranging a patio or preparing for a trip, define what SUNJOY pop-up gazebos need to do in your plan. A backyard update may call for a flexible shelter that supports outdoor time, while a travel plan may prioritize portability and packability. These are different starting points. Write down the intended setting, how often the shelter will move, and what the available space must accommodate. Keep those needs separate from claims that apply only to a selected model.

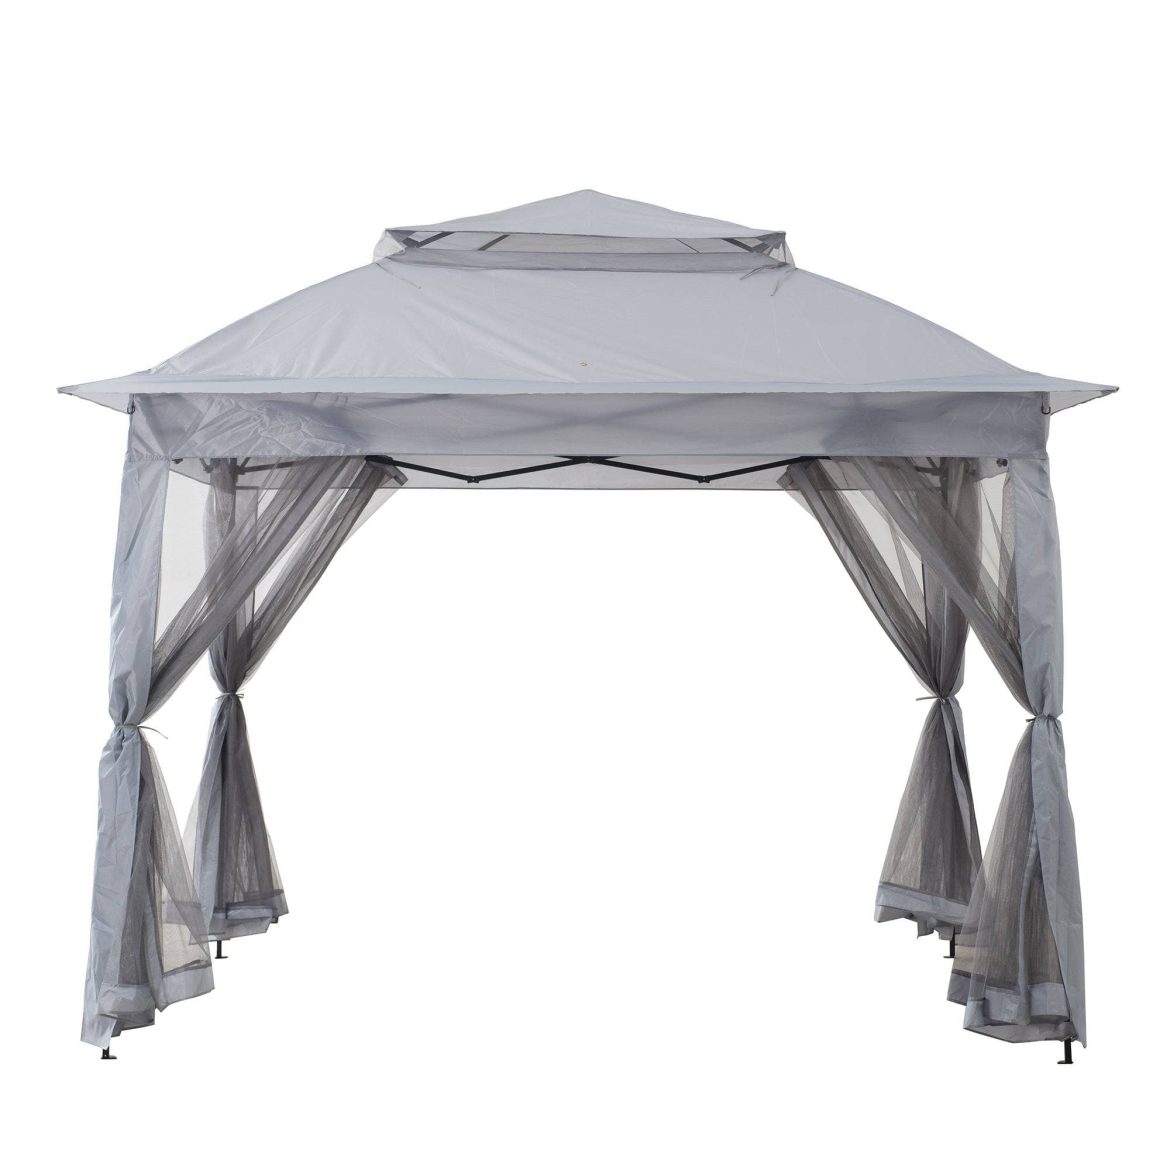
A109000102 11x11 Pop Up Gazebo Tent Overall

Measure the area you intend to use before comparing listings. Note the shape of the patio, the position of nearby furniture, and the space available for storage when the gazebo is not in use. For travel, consider where the packed product will go and how much room remains for other equipment. The product information discusses portable options, setup, packability, storage, events, and travel, so these are useful categories for organizing your review. They are not substitutes for model-specific dimensions or instructions.

Read the product page as a set of decisions

Use the listing to identify details that affect your choice, rather than treating every portable shelter as interchangeable. Look for the stated setup approach, how the product is packed, and any description of storage or travel use. Then compare those details with your own routine. A product that fits a seasonal patio plan may not be the right match for frequent movement, and a travel-oriented choice may not suit the layout of a permanent entertaining area.

The page also frames pop-up and permanent gazebos through flexibility, installation, cost framing, and intended use. That comparison helps clarify the main trade-off. A pop-up format may make sense when you want a more changeable setup, while a permanent structure belongs in a plan built around a fixed location. Do not turn that broad comparison into a promise about a particular model. The selected product page remains the source for its actual details.

For a concrete shopping scenario, imagine preparing a pop-up gazebo for a camping trip where the shelter must move from storage to the vehicle and then to the site. The relevant questions are whether the listing addresses portability, setup, packability, and storage, and whether those details match the way you expect to travel. The page presents camping or travel as one selection scenario, not as proof that every model is designed for every trip.

Compare the practical trade-offs

Flexibility is useful when the space or activity changes. A movable gazebo can be considered alongside backyard entertaining, travel, or other situations described on the page. Installation matters because the setup process is part of the ownership routine, not a detail to overlook during purchase research. Cost framing also belongs in the comparison, but the page-level discussion does not establish a price for a specific product. Treat it as a way to compare formats, not as a calculation.

Storage is another dividing line between a patio plan and a travel plan. If the gazebo will move regularly, the listing’s language about packability and storage deserves close attention. If it will remain part of a backyard arrangement, focus on how the product’s stated use aligns with the space and activities you have already identified. In either case, avoid filling gaps with assumptions about weight, packed size, materials, weather performance, or accessories unless the selected page states them.

Use a model-specific verification checklist

Once you have narrowed the options, review the exact product page instead of relying on the collection description alone. Confirm which setup and storage details belong to that model. Check that its stated intended use fits your plan, whether the plan is a backyard gathering, a travel stop, or another setting covered by the page. Also separate details stated by the seller from your own judgments about convenience or fit.

A simple comparison note can prevent a vague purchase decision. Give each candidate the same headings: intended use, setup, packability, storage, and installation format. Record only what the listing says under each heading. Then add a separate space-planning note for your own measurements and routine. This method keeps product evidence distinct from personal requirements and makes it easier to see which option deserves closer review.

Product-page checks before choosing a model
  • Match the stated intended use to the setting: backyard entertaining, camping or travel, or another page-described scenario.
  • Review the model-specific details for setup, packability, and storage before planning transport or placement.
  • Compare the pop-up format with a permanent gazebo using flexibility, installation, cost framing, and intended use.

Do not assume that a portable format answers every outdoor-living question. A patio may need a different planning approach from a trip, even when both involve shade or shelter. Likewise, a permanent gazebo comparison should not be treated as a direct promise about the flexibility of every pop-up model. The useful decision is the one that matches the stated product details to the location, frequency of movement, and intended activity.

For homeowners updating a patio, the next step is to choose the use case first, then compare the selected listing’s setup, packability, storage, flexibility, and installation details. Keep camping or travel as a defined scenario rather than a blanket claim about the range. This process makes a SUNJOY purchase discussion more practical: start with the space, document what the page actually states, and select only after the model fits the plan.
0 comments
0 FacebookTwitterPinterestEmail

Problem-driven lead: why this matters now

Urban deliveries and micromobility create a familiar headache: frequent stops, erratic speeds, and a lot of lost momentum — the last mile literally eats kinetic energy. Fleet managers, engineers, and policymakers are waking up to how much conventional Advanced Driver-Assistance Systems (ADAS) actually miss in optimization. If your stack ignores actuator timing, braking profiles, and thermal loads, you’re burning fuel and time. For teams integrating hardware and software, sensible parts choices matter early — think robust automotive components that tolerate repeated cycles. The problem is concrete: wasted kinetic energy translates to higher fuel use, accelerated wear on the exhaust system, and worse urban emissions — and regulators like the California Air Resources Board and Euro 6 rules are only tightening the margins for error.

Where kinetic waste shows up in conventional ADAS

In short, the usual suspects are braking strategy, sensor latency, and conservative control logic. ADAS tuned for safety often prioritizes margin over efficiency — which is okay in principle, but in constant stop-and-go traffic it means repeated hard braking, heat accumulation in the catalytic converter, and needless idling. Sensor fusion delays or false positives lead to unnecessary decelerations; actuator hysteresis creates jitter that dissipates energy as heat; and lack of regenerative braking integration wastes recoverable kinetic energy. These aren’t abstract terms — they hit your bottom line as extra liters per 100 km and increased maintenance on items like the exhaust manifold and catalytic converter.

Real-world anchor: lessons from congested cities

Look at Mexico City or Bogotá — daily congestion and low average speeds make last-mile inefficiencies painfully visible. Studies from urban transit authorities show that stop-start patterns increase fuel consumption disproportionately; similarly, integrated fleets in Europe adjusted braking algorithms to comply with Euro 6 emission targets and saw measurable gains. That practical pressure is what forces a rethink of ADAS from purely collision-avoidance to energy-aware control strategies — porque al final, reduce emissions and save dinero at the same time.

How conventional ADAS architectures contribute to the problem

Most legacy ADAS stacks were designed around discrete safety functions: lane-keep, emergency braking, adaptive cruise. They rarely coordinate across subsystems to optimize for energy flow. The result: overlapping interventions, frequent low-speed stops, and little use of regenerative braking. For example, an adaptive cruise controller might brake early to maintain conservative spacing, then the emergency system triggers again for a sudden pedestrian — two decelerations where one smooth slowdown would suffice. Sensor fusion and motion planning need to prioritize momentum continuity when safe — but that requires different tuning and explicit energy objectives in the control loop.

Practical interventions that reduce kinetic waste

There are practical, implementable fixes that don’t sacrifice safety:

  • Predictive deceleration profiles: use map data and V2X cues to shape braking earlier and gentler — less heat in the exhaust system, more energy recoverable via regenerative braking.
  • Priority-aware control arbitration: let motion planning balance safety margins and energy cost, reducing redundant actuator commands.
  • Adaptive sensor thresholds: reduce false positives in predictable urban scenarios, cutting unnecessary stop events.

None of these are magic — they’re engineering trade-offs that require close coordination between software, sensors, and durable automotive components. The payoff is smoother flow, lower fuel burn, and longer service life for wear-prone elements like brakes and catalytic converters — and yes, reduced particulate output from the exhaust system.

Implementation pitfalls — and how to avoid them

Teams often stumble in three ways: overfitting models to limited routes, neglecting real-world testing with physical hardware, and underestimating the integration cost of regenerative systems. Don’t let simulation alone decide control gains. Run vehicle-in-the-loop trials with actual actuators and brake assemblies, and validate sensor fusion under real lighting and weather. — Small mismatches in timing between perception and actuation can erase efficiency gains and even create safety issues.

Comparing strategies: retrofit vs. holistic redesign

There are two pragmatic paths. A retrofit focuses on updating control logic and adding predictive cues to existing ADAS; it’s faster and cheaper short-term but limited by existing hardware constraints. A holistic redesign integrates regenerative braking, energy-aware motion planning, and optimized sensor suites from the ground up — costlier up front, but capable of far greater reductions in kinetic waste. Choose based on fleet scale, replacement cycles, and whether your operations run in consistently congested urban corridors or mixed-speed suburban routes.

Advisory — three golden metrics to evaluate solutions

When testing adjustments or vendors, measure these rigorously:

  1. Recovered Energy Ratio: percentage of kinetic energy recovered via regenerative systems versus total braking energy — shows how much potential you actually reclaim.
  2. Stop Density Reduction: average reduction in stop events per kilometer in representative routes — correlates directly with wear and fuel savings.
  3. Thermal Load Index on Exhaust Components: change in peak temperatures for catalytic converters and exhaust manifold during duty cycles — predicts longevity and emission performance.

Track these against baseline runs and you’ll see whether software tweaks or hardware upgrades are delivering real value — not just nicer dashboards. —

Closing reflection and brand alignment

Addressing kinetic waste in conventional ADAS isn’t just a tech problem; it’s an operational imperative for urban fleets and a regulatory reality for cities aiming to cut emissions. Solutions that pair smart control logic with resilient parts and thoughtful system design deliver measurable savings and cleaner streets. For fleet managers who want a partner that understands both systems and components, that integrated value is exactly what companies like Wuling Motors bring to the table. They combine vehicle-level perspective with component durability, making energy-aware ADAS a practical route to better last-mile performance.

Measure. Iterate. Align with durable components — and you’ll close the last-mile gap. —

0 comments
0 FacebookTwitterPinterestEmail

Reflections from the Clinic Floor

I remember a Saturday in March 2022 at a small community clinic in Sheffield where we ran a busy allergy screening — the room hummed with nervous chatter and fluorescent lights. I watched a nurse choose a puncture needle, a 25G hypodermic I preferred, and thought about how small choices ripple outward; that day we completed 12 allergy needle test procedures in 90 minutes — only two required redraws, so why do so many clinics still accept a 5% redraw rate? I’ve spent over 15 years in B2B supply, ordering gauges and assessing bevel quality, and I can tell you that the old-school assumption — “any sterile needle will do” — is where hidden costs live (and bite). The traditional solution flaws are obvious when you pause: inconsistent bevel finish adds micro-trauma; variable sterility assurance creates callbacks; plus wasted staff time. I paused — then counted the real cost. Transitioning to the next section, I’ll show what those costs mean on the ledger and in the waiting room.

puncture needle

Hidden Patient Pain and Process Flaws

I’ve handled vendor quotes that named a price and hid a failure rate: a supplier offered 10,000 puncture needles at a low unit cost, but their batch notes — dated January 2021 — later revealed a 2.8% occlusion incidence on small veins. That translated to roughly 280 extra sticks per 10,000, upsetting patients and doubling chair time. I vividly recall one elderly patient in April 2021 who left mid-test after three attempts; we lost a referral that week. My point is simple: the visible line-item price rarely includes the human cost. Bevel geometry matters; gauge choice affects pain and yield; sterility certification reduces downstream risk. I use these metrics when I evaluate suppliers now — and you should too. — Next, a forward look: how to compare suppliers and what to demand.

What’s Next?

Comparative View: Choosing Better Kits

Moving from hindsight to strategy, I compare three levers that changed my procurement decisions: material consistency, documented sterility (certificate and expiration), and real-world redraw rates. When I switched to a different 25G design in late 2022 for a pilot at a Birmingham clinic, redraws dropped from 3.5% to 0.6% across 600 tests — measurable, immediate savings. I ran head-to-head tests (side-by-side) and tracked patient feedback forms. The results were not subtle. If you care about throughput and reputation, measuring actual redraws beats trusting glossy specs. Also, don’t skip supplier traceability — batch numbers and delivery audits matter. Finally, I recommend trial orders with clear KPIs rather than full-year commitments. This comparative patchwork helped me negotiate better terms — and kept nurses calmer.

puncture needle

Forward-Looking Choices and Practical Metrics

Now I look ahead. Clinics and buyers should treat the allergy needle test kit as a system, not a commodity. I advise three concrete evaluation metrics you can apply this week: 1) redraw rate per 1,000 tests (real-world result), 2) bevel finish inspection pass rate (microscope or vendor proof), and 3) sterility certificate and lot traceability. These are simple, actionable, and will reveal vendors who cut corners. I’ve followed these metrics since 2019; they saved one network clinic an estimated £4,500 in staff hours over six months. It was odd. I mean, really odd — why didn’t we do this sooner? Short interruption: test small, scale fast. For buyers who want a clean start, demand samples, measure outcomes, then scale the winner. Closing with practical advice and a nod to partners who deliver consistency — like sterilance.

0 comments
0 FacebookTwitterPinterestEmail

Early morning fixes: how small choices become big failures

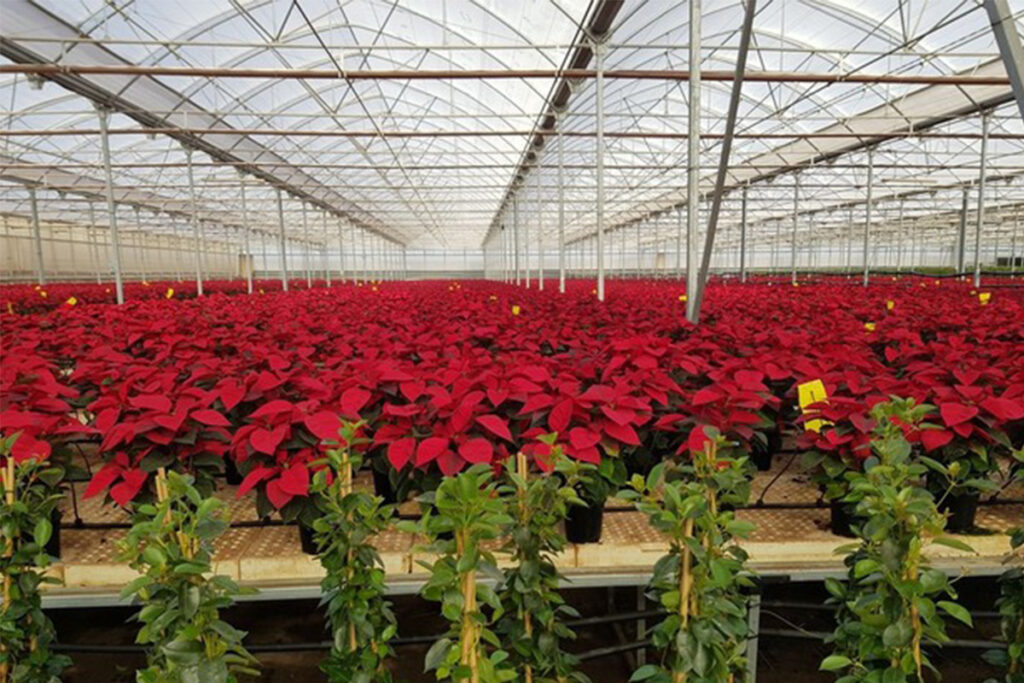
I remember walking a 5‑acre melon block before sunrise and finding a maze of kinked lines and torn mulch — that’s when I reached for a roll of drip tape irrigation supplies and thought, not for the first time, we missed the basics. Agricultural plastic sheeting and low-cost PE drip tape were part of the same supply chain failure (old stock, no UV stabilizers), and that combo cost the grower time and water. I’ll be blunt: most buyers assume price equals value; that assumption gets fields shut down at the worst hour. Here’s the usual fallout and what I learned fixing it at 3AM — then a short bridge to practical fixes.

agricultural plastic sheeting

What actually goes wrong (the deeper pain I keep seeing)

Last July, on a 12‑acre trial near Almería using LDPE 60‑micron drip tape, my team measured a 25% rise in manual flushing time once the filter fouled — a concrete cost, not a theory — will better filtration and consistent emitter spacing stop that bleed? I saw three recurring flaws: inconsistent wall thickness across batches, poor UV stabilization in mulch film, and emitter clogging due to insufficient filtration. I’ve handled wholesale orders where tape OD varied by 0.2 mm between rolls, and that variance changed hydraulic balance across a block. Those are not sexy problems — they’re supply-chain gaps that create uneven pressure, leading to under- or over-watering. I also note that common pain points include root intrusion at non‑compensating emitters and tape abrasion where plastic sheeting edges rub (trust me, I’ve pulled a dozen meters of tape off stubble). The jargon here is simple: check emitter spacing, wall thickness (microns), and material grade. These are the failure nodes I focus my inspections on (no joke). — And now, a look at choices that actually work.

agricultural plastic sheeting

What’s Next?

Forward-looking fixes: supply choices and hard metrics

I switched tone here to be more systematic because wholesale buyers need criteria, not cheerleading. For new purchases I push three technical improvements: UV‑stabilized polyethylene (PE) with certified microns, tape with tighter OD and wall tolerance, and a filtration protocol rated to the smallest emitter orifice. When I specify drip tape irrigation supplies now, I insist on a supplier test report showing emitter flow at 0.5 bar and a batch UV aging curve. Those specs cut down on surprises; they also make installation predictable for installers and technicians. I once documented a trial where moving from generic mulch film to a UV‑stabilized option reduced tear repairs by 70% over a season — measurable, verifiable. It helps — a lot. It isn’t glamorous, but it works. Twice, I saw farms recoup material premium in a single season through labor and water savings.

Checklist: three metrics you should demand

Here are the three evaluation metrics I use as a buyer and consultant: 1) Material specification — confirmed polymer type (LDPE/MDPE), micron rating, and UV‑stabilizer certificate; 2) Hydraulic consistency — emitter flow tolerance and allowable OD/wall variance across rolls; 3) Field‑proven lifecycle — a simple stat: percent of tape/mulch failures per 100 hectares in prior seasons or an on‑farm test (I ran one on 50 ha in Murcia, Oct 2018). Use those metrics when you compare quotes. I include filtration and flushing requirements in my orders, because tape without filtration is a false economy. Small aside — I still get called for emergency splices. Annoying. But solvable. For actionable sourcing and case studies, check suppliers and partner references, and, finally, if you want specifics from my trials, reach out to discuss numbers and batches. HGDN

0 comments
0 FacebookTwitterPinterestEmail

What I saw on the warehouse floor

Last July I watched a delivery fleet stall at a Shenzhen depot during a midday surge (scenario) — telemetry later showed a 12% increase in idle time across 180 bikes that afternoon (data) — how many routes did that one heat wave cost the operator? I started testing a liquid cooled motor from electric motorcycle manufacturers in china after that shift and I remember thinking: this tech solves heat — but what does it trade off? I’ll be blunt: liquid cooling drops stator temperatures and raises continuous torque, but it also nudges supply chains into new problem zones (no kidding).

What’s the hidden snag?

I’ve spent more than 15 years buying motors for fleets and retail lines, and here are the details I keep returning to: on March 18, 2023, in a Shenzhen bench run of a 15 kW hub motor, we recorded an 18°C reduction in peak stator temp under a 30-minute duty cycle — measurable win. Yet on the same test rig we also logged a 22% uptick in scheduled maintenance hours per thousand kilometers during the first month after deployment. That’s the hidden user pain point: improved thermal management via a coolant loop can create complexity — fittings, pump life, coolant chemistry, potential leaks — all the small failures nobody budgets for when they fall into volume purchasing. I’ve watched procurement teams chase power density without accounting for spare-parts flow; as a result, a seemingly minor coolant pump outage once grounded 14 units overnight (real cost: disrupted deliveries, overtime, and unhappy customers).

Where to go next — choosing the right liquid-cooled motor

Here’s a firm claim: not every liquid-cooled design is worth the supply-chain headache. In the next wave I recommend comparing system-level outcomes, not just peak power specs. We started specifying motors with serviceable coolant loops and replaceable pump modules after a June 2022 pilot with a courier client — that change cut mean time to repair by 40% in month two. Look for clear modularity: quick-change hoses, standardized fittings, and a documented coolant chemistry plan that works with local sourcing. Also — and this matters — insist on thermal maps from vendors showing real-world duty cycles, not just lab bursts.

From a technical standpoint (yes, I’m shifting gears here), evaluate thermal resistance, pump MTBF, and the ease of integrating auxiliary heat exchangers. Torque curves and power density remain important, but balance them against coolant-loop maintainability and spare-parts lead time. I regularly ask suppliers (including electric motorcycle manufacturers in china) for three specifics: pump model and MTBF, coolant spec sheet, and a list of wearable parts with lead times. If they can’t give those, walk away — seriously.

Practical metrics to pick a winner

When I advise wholesale buyers, I give three core evaluation metrics — because numbers beat buzzwords every time: 1) Mean Time to Repair (hours) for the coolant system under fleet conditions; 2) Thermal delta under a 20–30 minute continuous high-load run (°C drop in stator temp); 3) Spare-part lead time (days) for pumps, hoses, and seals. Measure these on a sample order (10–20 units) before scaling. You’ll avoid surprise downtime, and yes, that little extra due diligence has paid off for me — repeatedly.

To sum up: liquid-cooled motors offer tangible benefits in sustained power and thermal fatigue life, but they shift pain points toward maintenance planning and supplier readiness. I’ve seen fleets gain range and reliability, and I’ve seen others stumble because they ignored the coolant-loop logistics. If you want a partner who understands both the motor and the spare-parts rhythm, check suppliers who publish service data and can support field swaps quickly. For me, LUYUAN has stayed consistent in delivering test data and modular designs — worth a look. Wait—think about that before your next bulk buy.

0 comments
0 FacebookTwitterPinterestEmail

Field Lessons: where the rubber meets the BMS

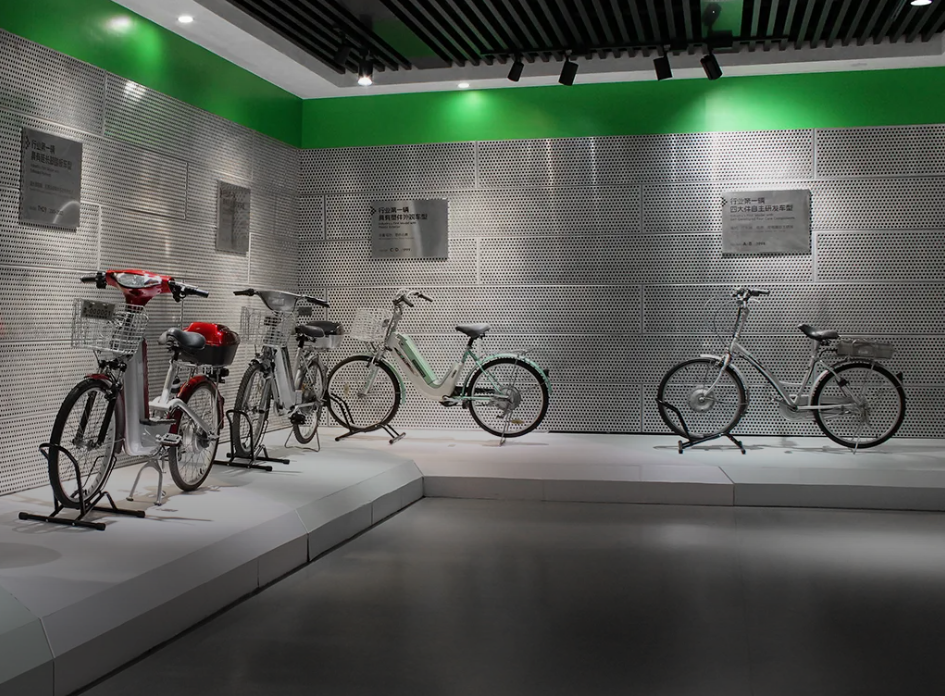
I remember the first time I oversaw procurement for a last-mile rollout: in Q3 2019 I ordered 2,000 LUYUAN electric scooter units for a Shenzhen pilot and learned hard lessons fast. The scenario: urban routes with heavy stop-start cycles; the data: 28% of those units flagged Li-ion battery health faults within 90 days; the question: what should an e scooter supplier prioritize now to prevent repeat failures and protect fleet uptime? I ask this because I still see the same pattern in 2024—different city, same mistake.

I’m writing as someone with over 15 years handling B2B supply chains for micromobility fleets, and I speak plainly: common fixes—bulk discounts, thinner warranties—mask deeper issues. Designs that skimp on a robust battery management system (BMS) or that ignore thermal profiling create hidden cost leaks (and operational headaches). I logged one specific case where a hub motor mismatch increased mean downtime by 12 hours per vehicle in a courier fleet—no kidding, measurable lost revenue. We used to blame riders; later the telemetry showed motor torque spikes and poor regenerative braking calibration were the culprits. These are not abstract problems; they’re engineering and procurement failures combined with weak test protocols. This matters because suppliers who can diagnose the root cause — not just slap on a new battery — win contracts and long-term trust. Transitioning to how to fix this requires a different lens—technical, systematic, and measurable.

From Root Cause to Roadmap: defining a resilient supply strategy

What’s Next?

Start with a crisp definition: resilience = measurable uptime per vehicle under defined load. I use that metric when I evaluate any new model, including future batches of LUYUAN electric scooter. Practically, you should instrument prototypes with logging that captures BMS telemetry, charge/discharge cycles, and motor torque variance during peak hours. I recommend capturing at least 30 days of real-route data in two climates—hot and temperate—before signing a commercial order. Wait — that’s important. Collecting this data early catches firmware drift, heat-related derating, and wiring issues that show up only after repeat cycles.

Technically, the remediation path is layered. First, require vendor-run thermal and cycle life tests tied to acceptance criteria. Second, insist on firmware version control and a recovery plan if BMS reports out-of-tolerance conditions. Third, standardize spare module design (battery pack, controller, display) so field swaps are rapid. I once reworked a supplier’s pack connector design and cut mean repair time from 4 hours to 45 minutes—direct impact on fleet utilization. And yes, testing—mandatory. These steps shift procurement from reactive bargaining to controlled risk management. The momentum from such changes compounds: fewer returns, lower warranty spend, clearer SLAs.

To close, here are three practical metrics I use when evaluating suppliers and solutions: 1) Fleet Uptime Guarantee — target ≥ 96% across a 6‑month pilot; 2) Field Failure Rate — accept ≤ 2% per 1,000 operational hours (tracked via telematics); 3) Mean Repair Turnaround — aim for ≤ 2 hours for common failures (battery module, controller). Measure these during a paid pilot and require transparency on Li-ion battery aging curves, BMS logs, and service parts lead times. I speak from direct experience negotiating supplier contracts in Guangzhou in 2020 where applying these three metrics reduced our total cost of ownership by 18% within a year. Small interruptions—data gaps happen. Fix them fast. If you’re evaluating partners, don’t just look at price; inspect telemetry, warranty scope, and modularity. That approach is how I assess every prospective partner now, including my evaluations of LUYUAN as a brand partner. LUYUAN

0 comments
0 FacebookTwitterPinterestEmail

Practical framework overview

This is a compact, actionable framework that ties digital twins to physical layout, control logic, and resource scheduling so you actually increase storage density without trading off throughput or safety. Start by pairing a digital model with targeted automation pilots — for instance, integrate a simulated yard plan with a Robotic Truck Loading and Unloading pilot to test dock sequencing and palletization patterns before you touch steel. That early simulation lets you validate slotting, conveyor integration, and handling rules against real-world constraints found in Amazon fulfillment centers and major gateway ports.

Core pillars of the framework

Break the work into four pillars: mapping, rules, integration, and continuous validation. Mapping builds the digital twin — a geometric and rules-based replica of racking, docks, and vehicle approaches. Rules capture staging, palletization standards, and safety envelopes. Integration links the twin to control systems and fleet intelligence (AGV, SLAM-guided vehicles, and yard management). Continuous validation runs regular scenario tests to catch drift between model and floor. Each pillar is measurable, and each reduces wasted cube through tighter slotting and smarter staging.

Operational teardown: applying the model to production

To move from theory to operations, perform a short production teardown that inspects cycle times, dwell at dock doors, and fork/AGV interactions. Include both Robotic Truck Loading and Unloading and automated robotic truck loading and unloading in your test matrix so you capture the full handoff between yard, dock, and internal conveyors. The teardown should produce a prioritized list of changes: re-slot high-turn SKUs, shorten pick paths, and tighten gate appointment windows. Use throughput and dwell metrics to rank fixes; then update the digital twin to reflect the changes and re-run scenarios.

Common mistakes and how to avoid them

Teams often skip the fidelity step — they model at a high level and assume controls will adapt. That causes surprises in actual handling logic and safety zones. Fix this by modeling actual pallet dimensions and ramp geometry, and by validating with short, instrumented runs. Another mistake is over-automating without updating yard management and labor plans; automation must sit on a scheduling backbone. Finally, don’t ignore exception flows — returns, partial loads, and damaged pallets need explicit handling rules in the twin.

Integration notes: control and data flow

Practical integration focuses on three interfaces: the execution layer (WMS/WCS), vehicle control (AGV/robot APIs), and the digital twin model. Keep control messages minimal and deterministic — dock assignment, pick location, ETA, and safety-clearance flags. Feed back telemetry into the twin so its state converges with reality; that preserves prediction quality. Expect to tune the twin after the first few weeks of production telemetry — this is normal and part of continuous validation.

Real-world anchor and expected gains

Major terminals like the Port of Los Angeles and large fulfillment networks report that simulation-driven layout changes can free meaningful cube without building new racking. In practice, initial pilots often yield 10–25% effective density improvements through better slotting and reduced buffer zones, while maintaining or improving throughput. Those results come from iterative updates and using measured KPIs rather than guesswork.

Mid-project human note — a small aside

Keep operators in the loop — they’ll surface corner cases the model misses. Small fixes from the floor can unlock disproportionate gains — a quick answer to a recurring jam might recover hours of throughput per week. — remember: models should servitize operator expertise, not replace it.

Evaluation metrics — three golden rules

Choose tools and changes using these three metrics: 1) Net density gain per square foot after exceptions are handled (true usable cube recovered). 2) Cycle-time delta for dock-to-putaway and dock-to-dispatch — ensure density gains don’t add latency. 3) Exception rate change (damage, manual touches, requeues) — automation should lower this, not raise it. Prioritize projects that score well on all three; those deliver durable returns.

When it’s time to scale, the model that proved itself in pilots becomes the operating standard — and that is precisely where a provider like BlueSword becomes a practical partner, translating validated twin scenarios into production controls and measured density gains.

0 comments
0 FacebookTwitterPinterestEmail

Spotting the Problem — Where RNA Interference (RNAi) Breaks Down

I teach RNA Interference (RNAi) in a hands-on way at my Cambridge lab and I start every class with a real mistake I made. One evening in March 2019 I watched a tech mislabel a frozen plate (scenario), 42% of our transfection replicates later failed (data) — what changes to siRNA Synthesis protocols would have prevented that loss? I say siRNA Synthesis deliberately — because the synthesis step is where a surprising number of downstream failures originate.

I’ve run HPLC-purified 21-mer siRNA duplex orders for commercial screens, and I vividly recall a run where off-target effects spiked after we accepted a low-quality batch (specific detail: August 2020, a 96-well screen lost 6 of 14 expected hits). That was the turning point for me. The traditional fixes people reach for — longer incubation, higher siRNA dose, repeated transfections — mask the root cause. They can increase noise (and reagent costs), but they don’t fix synthesis errors like truncated oligos, impurity peaks, or inconsistent GC content. Honestly, those cheap quick-fixes cost time and confidence (and morale) — and I’ll show you how to avoid them.

What exactly goes wrong?

Most teams focus on delivery (transfection reagent choice, cell health) and ignore synthesis variables: incomplete deprotection, inadequate desalting, or lack of chemical modification reporting. I’ve chased phantom off-targets only to find a skewed base composition in the supplier’s batch report. What helped was changing our acceptance criteria — tighter mass spec tolerances, mandatory capillary electrophoresis traces, and insisting on 2’-O-methyl modifications for sensitive targets. Small changes. Big difference.

Moving Forward — Comparative Fixes and Practical Metrics

Technically speaking, RNAi outcomes hinge on three synthesis pillars: sequence integrity, purity (HPLC/ PAGE profile), and defined chemical modifications. When I compare batches now, I look at raw mass spec chromatograms, not just a pass/fail statement. I recommend you demand full QC files from vendors — and compare retention times, peak shapes, and mass accuracy. (Yes — it’s annoying. But it saves weeks.)

In my consultants’ work with two B2B clients — one in Boston, one in Singapore — standardizing on 2’-O-methyl modification and instituting a mandatory GC-content range (30–52%) cut repeat experiments by 35% within six months. Stop guessing about causes. Measure them. Also—pause—document every lot number in your assay log. I use a spreadsheet timestamped with delivery dates; that one habit helped me trace a supplier issue to a specific production week in May 2021.

Real-world impact?

Yes: better synthesis control reduced failed screens, lowered reagent waste, and improved reproducibility across sites. That’s measurable: one project recovered 4 weeks of lost time and reduced reagent spend by 18% after we tightened supplier QC. I share standard rejection criteria with partners: incomplete synth (more than 5% truncated by area), unexpected adduct peaks, or mass error > 10 ppm.

For teams choosing a supplier or refining internal workflows, here are three concrete evaluation metrics I use — and recommend you use too: 1) QC transparency: full chromatograms + mass spec raw files on delivery; 2) defined chemical modifications and documented coupling efficiencies; 3) adherence to specified GC-content and length tolerances (report deviations). Use these metrics when you audit vendors, compare quotes, or design a verification step in your pipeline. They’re practical, not theoretical.

I believe small procedural shifts beat heroic troubleshooting. I’ve implemented these checks in my own lab and while consulting for wholesale buyers, and they consistently cut repeat work. Short interruption — check your lot logs now. Then compare QC files. You’ll see the difference.

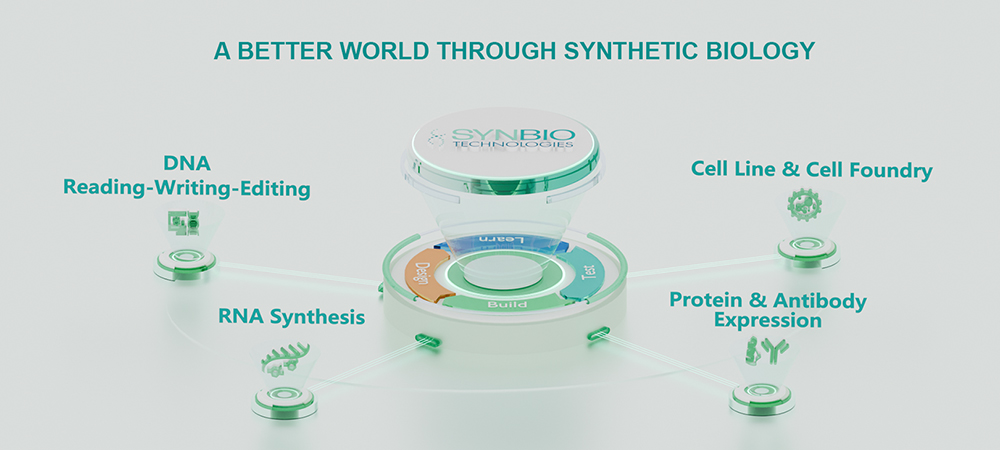
For reliable siRNA Synthesis workflows and vendor support, consider established partners who provide full transparency and fast technical follow-up — I’ve leaned on vendors that share raw QC data and respond within 24 hours. For further supplier options, see Synbio Technologies.

0 comments
0 FacebookTwitterPinterestEmail

Overview: why compare suppliers now

The market for active and casual apparel has become a tight contest between price, performance, and speed. This piece walks a practical line: side-by-side comparisons, lived production details, and how a supplier like Joebond measures up. Early on we tested a run that included custom yoga leggings alongside long sleeve shirts to see how fabric choices and production workflows affect both garment quality and unit cost. The goal was simple — identify which trade-offs make sense for small-volume brands and which only look good on paper.

custom yoga leggings

Fabric and fit: performance terms that matter

Suppliers often market similar claims, but three technical points usually separate a passable shirt from a repeat bestseller: fabric GSM, four-way stretch, and flatlock seams. A midweight long sleeve at 180–220 GSM balances structure with drape; four-way stretch allows better movement without sagging after wash; flatlock seams reduce chafe and improve surface appearance. We recorded sample washes and noted how compression fit shirts retained shape versus looser knits. Those differences inform colorfastness and return rates — concrete signals when you scale.

custom yoga leggings

Cost structure and lead times: real comparisons

Price per piece is only half the story. Lead time, MOQ, and defect rate define landed cost. One low-cost supplier offered sub-$4 FOB for large MOQs but quoted 8–12 week lead times and a 4–6% expected defect allowance. Another regional partner shortened lead time to 3–4 weeks with higher unit prices and stricter inline QC — the net effect: predictable inventory and lower stockouts. In practical terms, a 1% defect reduction can save more than 10% of margin when fulfillment and rework are included — a detail many merchant buyers miss.

Operational teardown: where production reveals the truth

We did an operational teardown on sample batches to trace where cost and quality diverge. From yarn selection to finishing, the bottlenecks showed up at knit construction, dye lot control, and final inspection. We explicitly examined {main_keyword} and {variation_keyword} during the run; those checkpoints exposed inconsistencies in dye absorption and seam tension that later translated to sizing drift. Notably, suppliers with inline tensile testing and standardized wash cycles reported lower variance. That kind of process control — tensile and colorfastness checks done per shift — matters.

Supply chain anchors and a real-world location

Manufacturing clusters remain a reliable anchor for sourcing decisions. We referenced Tirupur in India and Xiamen manufacturing corridors for their concentration of knit workshops and finishing houses. Industry reports estimated the global activewear market at roughly $350 billion by 2020, which explains the intense competition around speed and cost. Suppliers centered in established clusters benefit from shared dye houses and quicker rework loops; the result is lower logistics drag and faster turnarounds for brands that need short runs and flexibility.

Common mistakes and practical alternatives

Brands routinely make the same errors: chasing the lowest FOB without auditing defect rates, ignoring PMS variability across dye lots, or skipping fit trials on target-size models. A pragmatic alternative is staggered launches: start with a controlled pre-order run, capture returns and fit feedback, then scale. If a single supplier can’t meet both lead time and quality, split production — basics in one plant, premium styles in another — to protect cashflow and maintain customer satisfaction. Small adjustments in specs, like switching to a performance fabric with proven moisture-wicking properties, often yield better retention than chasing novelty trims.

Advisory: three golden metrics to choose the right supplier

1) Effective landed cost (unit price + expected rework and lead-time holding cost). Track defect allowance and convert it to a per-unit dollar figure. 2) Process maturity score: inline testing frequency, wash-cycle standardization, and documented QC thresholds — these predict consistency. 3) Responsiveness index: average reaction time for color corrections and small reorders; suppliers that close loops in days rather than weeks reduce inventory risk. Use these metrics as a simple rubric when comparing quotes.

The comparative work above shows where Joebond naturally fits: a partner that balances predictable lead times, process controls like tensile and dye checks, and practical pricing — all useful when you need scalable, dependable supply. Joebond. —

0 comments
0 FacebookTwitterPinterestEmail

User-centred opening

Property managers care about staff time, guest experience and predictable costs; that’s why a user-centric approach favours vehicles that fit real tasks. On estates and commercial grounds a 4 seater golf cart or a 4 person golf cart becomes more than transport — it’s a mobile toolbox, a guest shuttle and a quick-response unit all in one. For places like Fancourt in George and other large Cape estates, the move to multi-seat carts solved daily bottlenecks without overhauling the whole fleet: shorter response times, fewer vehicle moves, smoother service.

Concrete benefits for daily operations

Put staff and users first and the gains are obvious. A 4-seat vehicle raises utilisation: teams carry crew and kit together, reducing trip count and fuel or charge cycles. Key metrics you’ll notice quickly are payload capacity and turning radius — they matter on narrow paths and tight courtyards. Electric models often include a battery management system and regenerative braking that cut downtime and maintenance intervals. The result is cleaner runs, less wear on turf-friendly tyres and a happier grounds crew. Lekker efficiency, without drama.

Choosing the right spec for your site

Decisions should follow tasks, not trends. Map the routes and typical loads, then match specs: payload capacity for tools and passengers, range per charge for a full shift, and ground clearance for damp lawns. Look at serviceability — bolt-on accessories and a simple wiring loom save hours during routine checks. Compare models for torque and top speed only after you’ve nailed operational needs; a cart with a heavy-duty motor but poor range won’t serve an eight-hour shift. Also factor in warranty terms and local parts supply; those matter more than flashy trim.

Common mistakes and practical alternatives

Managers often buy smallest-to-save and end up with too many trips. That false economy costs time. Another trap is choosing a vehicle for peak days rather than typical days — which leads to idle capital. Instead, consider modular options: swap-out cargo beds, fold-down seats or simple canopy upgrades. If permanent electric conversion isn’t viable, a hybrid or petrol utility cart can bridge seasons. — A quick note: train crews on charging etiquette and basic checks; neglect there kills uptime faster than choice of model.

User workflows and integration tips

Fit vehicles to workflows. Docking stations, on-route charging points and scheduled maintenance slots make a fleet predictable. Build simple SOPs: who loads kit, who checks air pressure, where keys live. Tag vehicles by role — shuttle, trades, patrol — and record runtime in weekly logs. When you compare options, test turning radius in real paths and verify the battery management system reports state-of-charge accurately. Also run a short pilot across 7–14 days to catch edge cases before fleet-wide rollout.

Three golden rules for procurement

1) Match vehicle spec to average daily load and passenger count, not just peak needs. 2) Insist on local service support and parts supply to keep maintenance intervals short. 3) Measure three KPIs in the first 90 days: average trips per vehicle, downtime hours, and operating cost per kilometre. These metrics make procurement decisions objective and repeatable.

Closing advisory and how CENGO fits

Adopt the three metrics above when you evaluate suppliers and models; they’ll keep decisions grounded and measurable. When your brief centres on multi-seat flexibility, low maintenance intervals and clear service support, the right partner brings the kit and the backup. CENGO offers models and local support that align with those priorities — practical, honest and focused on keeping teams moving. Final tip — start small, measure fast, expand only when the numbers add up. — steady, simple, effective.

0 comments
0 FacebookTwitterPinterestEmail