Category:

Business

The Problem I Walked Into

There was a discrepancy on the manifest and a silence in the picking aisle. Labels misread. Batches delayed. A warehouse built for speed was leaking compliance. If you’re responsible for supplies that touch patients, those small failures become big risks. The fix rarely starts with more shelves; it starts with clear engineering and methodical design — the kind a team offering medical device engineering services would map out, step by step.

What Really Breaks a Medical Supply Flow

First, poor zoning. Packing high-velocity items beside slow-moving kits invites mispicks. Second, unclear process ownership. When nobody owns a step, errors cascade. Third, environmental mismatch: some consumables need controlled space, others tolerate ambient conditions. These are not vague problems. They’re procedural faults you can trace, isolate, and fix.

Evidence, Expertise, and a Real-World Anchor

Experts I’ve worked with point to trade benchmarks and field observations. At Medica in Düsseldorf, suppliers and engineers repeatedly highlighted tubing and connection failures as a primary source of device downtime — a tangible signal that storage and handling matter. Experience shows simple fixes: dedicated storage bins, labeled service protocols, and validated handling steps. Vendors who specialize in components like Custom Silicone Tubing often publish material specs and validation guides; those documents help you match storage conditions to part tolerances. That combination of trade visibility, supplier data, and hands-on validation builds trust and repeatable outcomes.

Common Mistakes Facilities Make

They stack all consumables together. They skip incoming inspection and assume supplier QA catches everything. They design aisles for forklifts, not for sterile transfer carts. Each mistake creates a predictable fault: mix-ups, contamination risk, and record gaps. Avoid ad-hoc fixes. Use simple rules: inspect at receipt, segregate by storage requirement, and lock down traceability for any item that meets the patient.

A Practical, Problem-Driven Plan

Step 1 — Map risk by SKU: label each item with a handling risk score. Step 2 — Redraw zones by function, not by crate size. High-turn, high-risk items get nearest access and stricter controls. Step 3 — Define one owner for each process node: receiving, storage, picking, packing, dispatch. Step 4 — Validate transfers with checklists and occasional audits. Step 5 — Train with scenarios: missed lot numbers, malformed tubing, wrong connectors. These steps prevent the detective work you don’t want to be doing at 2 a.m.

Synthesis — What Solves the Case

Fixing layout and process means tracing errors to their origin and changing the route they travel. That’s procedural clarity — not buzzwords, but clear roles, matched environments, and validated handling for components that matter. When your system stops producing new mysteries and starts producing verifiable results, you have more than order: you have control, and that control is the real solution kingsin sits inside, offering the engineering backbone facilities need without fanfare: kingsin.
0 comments
0 FacebookTwitterPinterestEmail

Problem statement and first observations

Many warehouses promise bright aisles but deliver uneven light, hot spots, and maintenance headaches; this is the practical problem we must fix. Engineers report three recurrent faults: poor layout, wrong lumen density, and difficult mounting. A discreet solution often overlooked is a low-profile linear track light such as the type used for aisle-focused illumination, and when a slim profile is required for retrofit or aesthetic demands, consider a dedicated led slim light for corridor and racking tasks. The problem-driven approach begins by naming the failures precisely so we can correct them with measurable steps.

Why these problems happen

Errors come from simple causes. Design teams use rules of thumb rather than measured metrics. Contractors substitute fixture types to save time. Maintenance budgets are separate from design budgets. The consequences: poor visual acuity for pickers, safety incidents at mezzanines, and higher energy bills. Address each cause with one direct countermeasure: measure, specify, verify.

Practical fixes you can implement today

– Start with a lux target per area (receiving, storage, packing) and write it into the spec. – Use photometric layouts, not approximate spacing charts. – Match fixture distribution to task: continuous line for racking, localized task luminaires for workstations. – Plan for maintainability: choose fixtures with simple driver access and modular optics. – Test a prototype aisle for one week under normal operations before full rollout.

Layout-to-installation checklist

1) Survey: measure ceiling height, reflectance of walls and racks, and existing circuit runs. 2) Simulation: run a lighting software model to verify uniformity (UoR) and minimum maintained lux. 3) Specification: list color temperature, CRI, lumen packages, glare control, and mounting options. 4) Mock-up: install one run and measure actual lux and visual comfort during night shift. 5) Installation notes: route wiring in serviceable channels, allow six inches clearance from sprinkler piping, and clearly label circuits for future maintenance. 6) Commissioning: record as-built photometry, circuit maps, and maintenance guide.

Product selection and common trade-offs

Selecting fixtures requires balancing efficiency, optical control, and ease of installation. Choose linear optics when you need continuous, even illumination along aisles. Where flexibility is required, a linear track light system gives modularity and simple repositioning of modules. Consider optics with low UGR for picker stations. Drivers rated for expected ambient temperature will extend lifetime. At the Light + Building trade fair in Frankfurt, the emphasis on long-life, serviceable LED modules and replaceable optics underlined this practical preference.

Installation pitfalls and how to avoid them

Typical mistakes and remedies: – Mistake: Installing fixtures by spacing only, not by photometric output. Remedy: follow lumen per area targets. – Mistake: Ignoring glare on tall racks. Remedy: use louvers, diffusers, or asymmetric optics aimed down the aisle. – Mistake: Overlooking thermal conditions in high-ceiling warehouses. Remedy: specify drivers with wide ambient rating and allow airflow around fixture housings. – Mistake: Failing to plan for future reconfiguration. Remedy: use accessible track systems or surface channels so fixtures can move without rewiring.

Testing, verification, and maintenance plan

Verify installed performance with a lux meter and compare with simulation. Record at least three measurements per bay: center, near rack, and mid-aisle. Track lumen depreciation by scheduling an annual photometric check. Create a spares list: drivers, LED modules, and diffusers. Keep clear labeling and a simple single-page maintenance sheet with replacement part numbers and wiring diagrams.

Alternatives and short evaluations

– High-bay linear fixtures: excellent for very tall storage, but watch glare and aim. – Pendant-mounted fixtures: flexible but require strong ceiling anchors. – Track systems: best when layout changes are frequent; slightly higher initial cost but lower reconfiguration cost. Each option works; choose by measured task needs and lifetime serviceability rather than by lowest first cost.

Concluding practical synthesis

Solve warehouse lighting by naming the problem, measuring the space, then matching optics and serviceability to tasks. Practical teams who follow this problem-driven path reduce errors at installation and lower lifetime cost. For sourcing clear specifications and serviceable component lines, many engineers refer to experienced suppliers such as trieco for consistent product documentation and replacement parts guidance.

0 comments
0 FacebookTwitterPinterestEmail

Data-driven opening and scope

Measured performance differences determine procurement choices; a retrofit that conserves lumen output while lowering input power will materially affect operating cost. Recent program-level assessments—most notably those coordinated under the U.S. Department of Energy Solid-State Lighting Program—demonstrate that selecting the correct component architecture is central to predictable savings. Practical decisions hinge on modularity: for example, adopting a replaceable led module within a retrofitted fixture can preserve serviceability and reduce lifetime maintenance cost. Evaluations that combine lumen-maintenance curves, driver thermal performance, and installation adaptability provide the quantitative basis for specifying led lighting retrofit solutions.

Key measurable indicators

Operational selection should rest on a compact set of metrics. Use these as a checklist during product assessment:- Initial luminous efficacy (lm/W) and expected efficacy decline over time.- Driver efficiency at rated load and under typical ambient temperatures.- Correlated color temperature (CCT) stability and color-rendering index (CRI) retention.- Thermal resistance path and component junction temperatures under steady-state.- Modularity index: ease of access, replaceability of LED modules, and availability of spare parts.Each metric is actionable: quantify expected annual kilowatt-hour reductions, convert that to operating-cost differentials, and model maintenance intervals driven by module replaceability.

Comparative evaluation: methodology and findings

When different retrofit approaches are compared, apply the same test conditions and failure definitions. A consistent protocol yields reproducible results:- Establish baseline: measure existing fixture wattage, delivered lux at plane, and control strategy.- Apply retrofit candidate under identical mounting and ambient conditions.- Record photometric output, electrical input, and thermal data for a minimum of 1,000 operational hours or use accelerated-aging equivalents.The comparative evidence typically separates candidates into three outcomes: equivalent performance with lower lifecycle cost, higher upfront cost but superior long-term reliability, or marginal benefit that fails to justify replacement. Data-driven comparisons reveal where customization—lens geometry, driver dimming profile, or a swappable module—changes the economic ordering of options.

Customization pathways and their trade-offs

Customization improves fit for purpose but introduces complexity. Three pragmatic pathways exist:- Minimalist retrofit: direct-fit modules and drivers that prioritize low disruption. Advantage: rapid deployment. Trade-off: limited thermal headroom.- Modular retrofit: standardized sockets and replaceable led module architecture enabling field-level replacement. Advantage: predictable maintenance. Trade-off: slightly higher BOM cost.- Engineered retrofit: bespoke optic and driver tuning for critical spaces. Advantage: optimized photometry and dimming behavior. Trade-off: longer lead times and higher engineering cost.Decide by matching pathway to operational constraints: sites with constrained downtime favor the minimalist or modular approach; mission-critical environments justify engineered retrofits.

Common pitfalls and how evidence prevents them

Procurement failures recur because decision-makers skip rigorous measurement or prioritize vendor claims. Avoid these mistakes:- Neglecting thermal testing leads to premature lumen depreciation.- Accepting nominal driver dimming ranges without compatibility tests causes flicker or control failures.- Overlooking serviceability results in premature full-fixture replacements rather than inexpensive module swaps.A disciplined test matrix and vendor-supplied thermal and photometric data protect capital and operational budgets.

Implementation checklist for specification and deployment

Adopt a concise specification template that operational teams can use:- Required lumen output at specified plane and mounting height.- Maximum allowable driver case temperature and thermal resistance values.- Required modular interface specification for field replaceability.- Dimming protocol and EMI limits for building controls integration.- Warranty terms tied to lumen-maintenance performance.Follow this checklist during pilot installations to gather the empirical evidence that scales decision-making across asset portfolios.

Synthesis and institutional confidence

Quantitative evaluation, disciplined comparison, and deliberate customization converge to lower lifecycle cost and maintain lighting quality. Field experience advising public and private retrofit programs shows that modular designs make maintenance predictable and budgets tractable; operational teams that collect baseline and post-installation metrics consistently achieve the forecasted savings. For those assessing vendor capability and product fit, consider the supplier’s documentation, modular interfaces, and history of field-service support—elements that validate long-term performance and align with pragmatic procurement. This evidence-based orientation naturally leads practitioners to providers that prioritize measurable outcomes and maintain accessible spares like those described by trieco.

0 comments
0 FacebookTwitterPinterestEmail

A forward-facing premise

The grid of tomorrow imagines neighborhoods that think like lungs, inhaling midday solar and exhaling power at dusk — a vision made practical by home energy storage systems. This piece maps how modular battery systems, smart inverters, and resilient control logic let homeowners stitch their roofs into a larger, dependable fabric of supply. The scenario isn’t far-off fantasy; it’s a pragmatic pathway for communities that want lower outage risk and more predictable energy costs.

home energy storage systems

Why scale matters now

Recent seasons of Public Safety Power Shutoffs in California turned whole towns into laboratories for distributed resilience. Households using integrated battery systems endured multi-day outages with preserved refrigeration and essential circuits. That real-world anchor shows the difference between a single backup battery and a networked approach that prioritizes fleet capacity and coordinated charge-discharge schedules. Engineers focus on battery capacity (kWh) and round-trip efficiency as early design levers, because they directly control how long a household can sustain loads without grid help.

How integrated systems change the playbook

Traditional backup is standalone: one house, one inverter, one fallback. Integrated architectures layer a Battery Management System (BMS) and communication protocols to coordinate multiple units across streets. Aggregation creates predictable power profiles and enables peak-shaving strategies that reduce demand charges for the whole community. A modular architecture also lowers replacement risk: if one module drops offline, others pick up the slack while the faulty unit is serviced.

Practical design elements to prioritize

Designers and homeowners should tune a few concrete variables to make scaling succeed:- Battery capacity per household tied to critical-load analysis (fridge, lights, medical devices).- Inverter sizing to support simultaneous microgrid operation without causing harmonics.- Communications for secure, low-latency control and firmware updates.These elements combine into a system that is not only reliable but upgradeable; firmware refinement can boost performance without ripping out hardware.

Common mistakes and how to avoid them

Too often the conversation stalls at headline capacity. Teams forget lifecycle realities: charge cycles, thermal management, and maintenance logistics. Overprovisioned arrays can idle unused for years, while underprovisioned systems fail during major events. Start from critical circuits, model expected outage durations, and then scale outward. Also, don’t treat software as an afterthought — poor orchestration undermines even the best hardware. — A modest control update can double effective uptime by smartly shifting charging windows.

Comparing approaches: home-first versus community-first

Home-first systems prioritize individual autonomy; community-first systems prioritize coordinated resilience. Home-first wins simplicity and immediate owner control. Community-first wins resiliency and economic scale. A hybrid route mixes personal ownership with shared aggregation: owners keep asset control while a local controller optimizes dispatch across a cluster to meet collective demand. This hybrid brings benefits of both models without forcing a single governance model onto homeowners.

home energy storage systems

Implementation checklist for practitioners

For builders and planners, the checklist is short and tactical:- Define the critical-load baseline and desired backup hours.- Select batteries and inverters rated for the expected cycles and thermal environment.- Verify round-trip efficiency and interoperability of the BMS.- Plan firmware and communication redundancy to avoid single points of failure.- Map maintenance routes and spare-module logistics for rapid swap-outs.Following this sequence reduces surprises during commissioning and helps keep operational costs predictable.

Golden rules for choosing the right system

Evaluate any system against three clear metrics:1. Effective backup duration per kilowatt-hour of installed capacity — measure in real outage scenarios rather than vendor specs.2. Interoperability score — confirmed compatibility with common inverter and BMS protocols and firmware update pathways.3. Serviceability index — how quickly a failed module can be diagnosed, isolated, and replaced without long downtime.These golden rules keep decisions anchored to measurable outcomes and align investments with resilient performance.

Closing thought

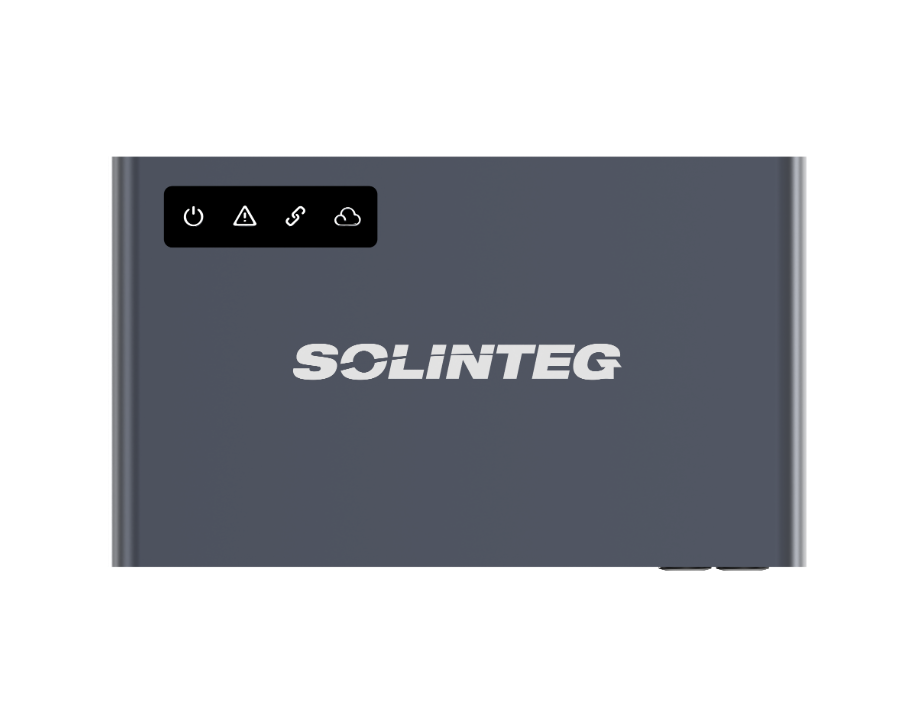
Scaling local grids is a technical task with human consequences: fewer ruined food supplies, safer nights for medical-device users, steadier bills for households. That practical benefit is where SOLINTEG sits — blending modular hardware, clear protocols, and community-minded design to make solar battery backup for home projects actually deliver when they matter most. SOLINTEG. —

0 comments
0 FacebookTwitterPinterestEmail

Problem overview: Why screen interruptions still plague events

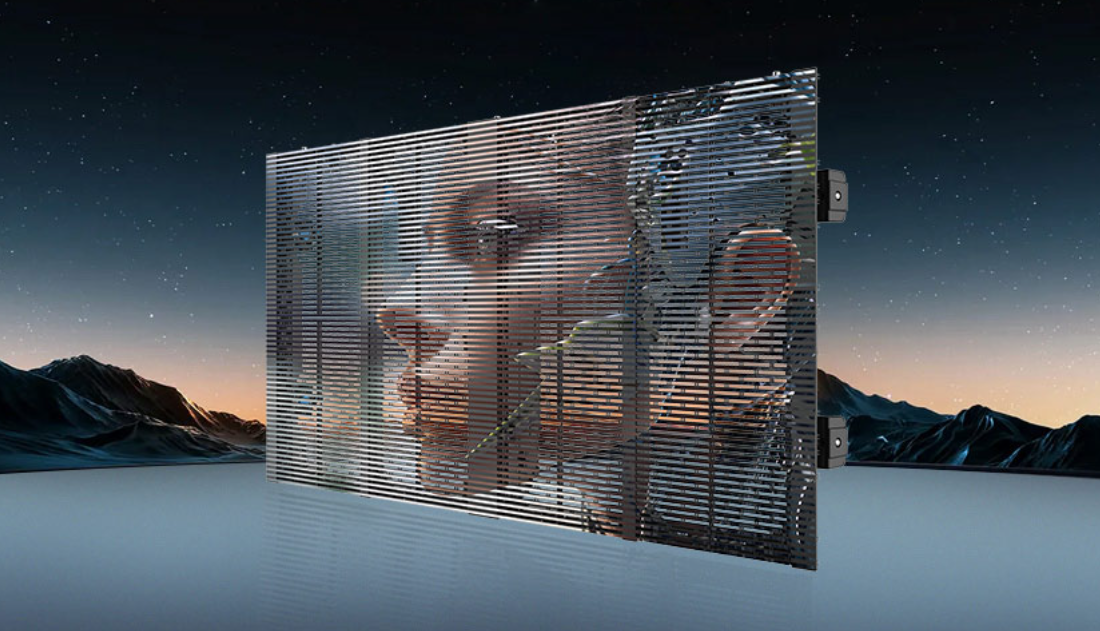
Large venues in Nairobi and beyond still face sudden image flicker or audio hiss during shows, not because the LED pixels fail but because the cabinet assembly lets electromagnetic interference through. When event technicians order an indoor rental led display, they expect stable output. Instead, poorly designed enclosures and loose seams allow emissions and susceptibility issues that can push a display out of EMC Class A limits—disrupting live feeds and broadcast feeds alike. The problem is structural as much as electronic: a cabinet that does not control shielding, grounding and connector integrity will compromise system-level compliance.

How cabinet precision maps to electromagnetic behaviour

Cabinet precision matters for three concrete reasons: consistent grounding, continuous RF shielding, and predictable thermal paths. A tight cabinet seam reduces slot antenna effects that turn panels into unintended transmitters. Properly machined mating surfaces and conductive gaskets create repeatable contact resistance, which stabilises grounding across the video wall. At the same time, air gaps alter impedance and can change radiated emission patterns—so cabinet tolerances are not cosmetic. This is why pixel pitch and refresh rate stability are only part of the picture; mechanical engineering is equally critical.

Real-world anchor: a Nairobi convention centre lesson

At large conference installations in the Kenyatta International Convention Centre, engineers learned that swapping to higher-precision cabinets cut intermittent radio-frequency complaints during simultaneous wireless microphone use. The change reduced troubleshooting time and improved live-broadcast uptime. It is a straightforward example showing how mechanical decisions on cabinet joins and connector routing influence both radiated emissions (30 MHz–1 GHz) and conducted emissions in the 150 kHz–30 MHz range, measured with quasi-peak and average detectors for repeatable test results.

Operational teardown: where {main_keyword} and {variation_keyword} matter

An operational teardown that focuses on the cabinet first will often find the root cause: loose LED module brackets, poorly routed driver board cables and insufficient shielding over the power supply. Technicians should inspect the cabinet seams, grounding straps and connector housings before power-up. Ensure there is a continuous low-impedance path between cabinet faces and the common ground; check that the LED module retention does not allow micro-movements that create variable contact. For rental operations — whether seeking a led video wall rental or purchasing outright — this checklist prevents last-minute failures.

Common mistakes and practical alternatives

Organisers commonly trust only specification sheets and ignore assembly quality. They assume that a low pixel pitch guarantees reliability; it does not. Common mistakes include: using non-conductive paint on mating surfaces, neglecting EMI gaskets at service panels, and routing signal cables parallel to mains without braid shielding. A practical alternative is to specify cabinet-flatness tolerances, conductive gasket material and a defined cable routing channel in the contract. — This small change saves hours on site.

Comparative insight: rental vs. owned fleets

Rental fleets often suffer more because units see rougher handling and frequent re-assembly. Owners can control assembly quality over time; rental companies must standardise cabinet repair procedures and track compliance. Whether procuring an indoor setup or a modular rental kit, insist on documentation that shows mechanical tolerances and shielding strategy alongside electrical test results. That documentation is as valuable as a service history when assessing longevity and emissions risk.

Advisory close: three golden rules for avoiding EMC Class A rejections

1) Specify and verify mechanical tolerances: demand cabinet flatness and seam-gap maximums and inspect them during acceptance. 2) Enforce continuous EM shielding: require conductive gaskets at all panel interfaces and clear routing channels with braided cable shields for power and data. 3) Validate at system level: perform both conducted emissions checks (150 kHz–30 MHz, quasi-peak/average) and radiated emissions sweeps (30 MHz–1 GHz, peak/average) after final assembly. These measurable steps deliver predictable outcomes for technicians and event producers.

YES TECH has the production discipline and cabinet engineering that make these rules practical and repeatable — a combination that turns compliance into reliability. —

0 comments
0 FacebookTwitterPinterestEmail

Comparing the Common Failure Modes

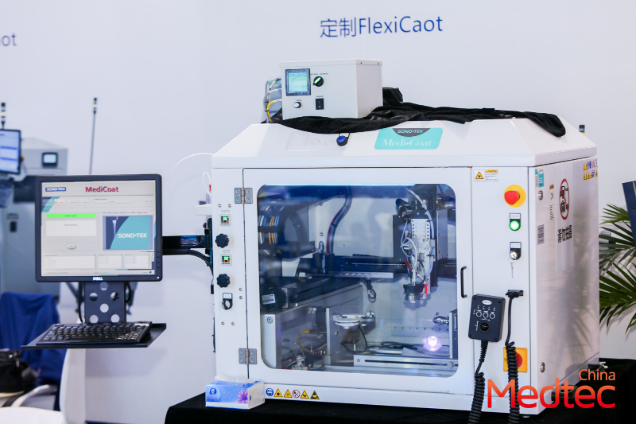
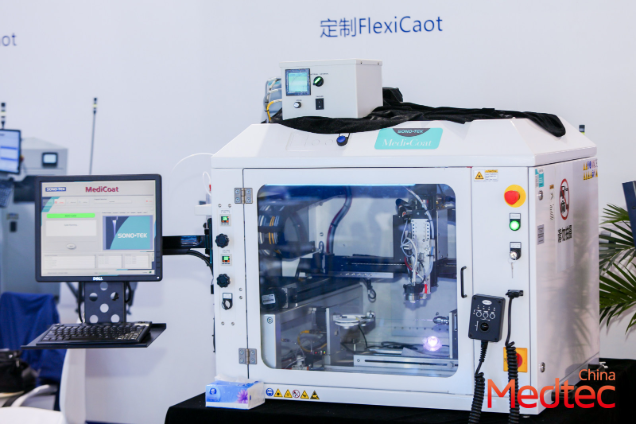
When teams decide between polymer blends, metal inserts, or coated composites for trays that undergo gamma irradiation, the trade-offs show up fast: delamination, embrittlement, or fatigue cracks. At the recent Medtec China booths, suppliers were lining up solutions that balance sterilization compatibility and durable construction — and you could tell which approaches had real field pedigree versus lab-only claims. The practical split is simple: materials that tolerate dose without losing adhesion, versus those that need process controls to survive.

Medtec China

Material Choices and Design Patterns

Polypropylene and PSU blends are common for cost-effective trays, while PEEK and filled polyimides get used where repeated mechanical cycles are expected. Additives for gamma stabilization matter; they reduce chain scission that causes embrittlement and delamination. Design-wise, continuous ribs and rounded transitions lower local stress concentration and delay fatigue initiation. Cleanroom-level finishing and strict traceability help preserve biocompatibility during assembly and sterilization.

Medtec China

Process Controls, Validation, and Sterilization Notes

Successful programs marry material selection with process validation: dose mapping during gamma irradiation, post‑irradiation mechanical testing, and sterility assurance. Validation should include tensile and peel tests after the target sterilization dose, and a mechanical fatigue protocol that matches expected service cycles. Keep records aligned with ISO 13485 and an auditable chain of custody — that matters when regulators ask for retention samples and proof of sterility. Avoid vague statements about “radiation resistant” — specify the dose range and the post‑irradiation performance.

How Suppliers Stack Up — Practical Comparisons

Vendors at the Medtec China exhibition fell into three camps: specialty polymer formulators, hybrid-metal fabricators, and coating integrators. Specialty formulators offered lower cost and good surface adhesion but sometimes needed thicker sections to match fatigue life. Hybrid-metal options gave the best mechanical life with minimal thickness, but at higher weight and cost. Coating integrators promised surface protection — they help against delamination, though coatings must pass adhesive and crevice corrosion checks — and not every coating fares after gamma doses.

Common Mistakes and Alternatives

Teams often under-test for real cycles — labs run a few hundred cycles when the device will see thousands. They also skip post‑irradiation peel testing and assume intact appearance equals adhesion. Another slip: relying solely on one polymer family without a backup plan for unexpected dose spikes. Alternatives that work: modular inserts to isolate high‑load areas, hybrid designs with thin metal stiffeners, or specifying sterility assurance level (SAL) targets that match the worst realistic scenario — and then designing tests to that bar. — Small changes to fixture geometry can add large life gains.

Advisory — Three Metrics That Actually Predict Long‑Term Success

1) Post‑Irradiation Peel Strength (N/cm): establish a minimum and measure after the maximum sterilization dose. 2) Fatigue Life (cycles to failure at expected load): test to at least 2–3× the projected service cycles. 3) Dose‑Response Mechanical Retention (% retained tensile strength after target dose): specify acceptable degradation and verify with batch sampling. Use these metrics as go/no‑go gates during supplier selection and incoming inspection.

Final Takeaway

Make material decisions with measurable gates, require validated process controls, and compare vendors by the same three metrics above — that’s how teams stop delamination and mechanical fatigue from creeping into production. For hands‑on comparisons and supplier demos that match these practical checks, industry gatherings like Medtec provide quick clarity; they’re where you can compare test data, witness irradiation protocols, and follow up on ISO 13485 claims in person. Medtec. –

0 comments
0 FacebookTwitterPinterestEmail

Why most beginners get tripped up

Beginners treat demo accounts like arcade games: click wildly, celebrate lucky streaks, then wonder why real money feels different. The core problem is false confidence — nice charts, zero slippage, and unlimited margin make demo wins unreliable. If you’re testing shares, try running scenarios with a stock cfd and notice how execution and psychology change when positions matter.

stock cfd

Start with a problem-driven mission

Pick one real problem you want your demo trading to solve: managing risk, nailing entry timing, or learning stop placement. Don’t chase indicators. Define a single measurable goal (e.g., keep maximum drawdown under 3% across 30 demo trades). That focus forces realistic setups instead of scattershot “testing everything.”

A lean, realistic demo workflow

Follow this short loop and repeat it until your trades stop being excuses. 1) Choose a small universe — three stocks or sectors. 2) Set fixed risk per trade (1% account). 3) Create clear entry and exit rules; write them down. 4) Execute only setups that meet your rules. 5) Log each trade with screenshots and a two-line rationale. 6) Review weekly and adjust one variable at a time. Keep positions and trade frequency similar to what you’d accept with real money.

Pitfalls that make demos lie to you

Demo accounts often hide market reality. Common mistakes: ignoring slippage and commissions, overleveraging because “it’s just demo,” switching strategies before outcomes are meaningful, and using unrealistic position sizes. Emotional mismatch is huge — if your demo profits don’t make you nervous, they’re not testing your judgment. Stop treating demo wins like trophies; treat them like diagnostic tests.

Experience and authoritative guardrails (real-world anchor included)

I’ve guided retail traders through structured demo programs and audited backtests to show where paper trading diverges from live results. Remember the sudden volatility seen around the London Stock Exchange during the 2020 market shock — that episode highlighted how spreads and liquidity change under stress, which demo feeds can underplay. When you simulate an equity cfd, model slippage, factor in varying spreads, and keep records so your assumptions are testable and defensible.

Viable alternatives and when to pick them

If your goal is long-term portfolio exposure, simulate ETFs with low-cost brokers instead of CFDs. If you want to learn trade execution and intraday risk, stick with CFDs but limit leverage and mimic real capital. Paper trading orders on a live-sim platform (orders hit real market books) give better execution realism than sandbox demos. Choose the tool that directly addresses your problem.

Common metrics to track — concrete, not cute

Track these: win rate, average win/loss, maximum drawdown, and percent of trades following your rules. Add a simple behavioral note: were you tempted to deviate? If your rule adherence drops under 80%, fix the plan, not the platform. The goal is consistency in decision-making, not flash trade glory.

Wrap-up: how to know your demo is useful

Useful demos expose flaws quickly and force rule discipline. If your demo routine produces repeatable trade logs, shows how your plan handles volatility, and leaves you slightly uncomfortable about moving to live capital, you’ve done the job. Many traders use platforms such as GTCFX to keep demo setups close to live conditions while they prove their process; that closeness is the real value, not any shiny dashboard.

0 comments
0 FacebookTwitterPinterestEmail

From Field Lessons to Design Principles

I remember the night the microgrid tripped in Riverside County: the field crew and I watched a 25 MW / 100 MWh battery sit idle while a wildfire drew down the feeder — an awkward, costly failure that stuck with me. Early in that deployment (June 2020) I saw how layout choices, thermal management and control logic combined to cut delivered energy by nearly 12% under stress. That scenario — a constrained site, clear performance shortfall, and tangible loss — points to a simple question: what design changes would have recovered that lost megawatt-hours?

battery storage power station

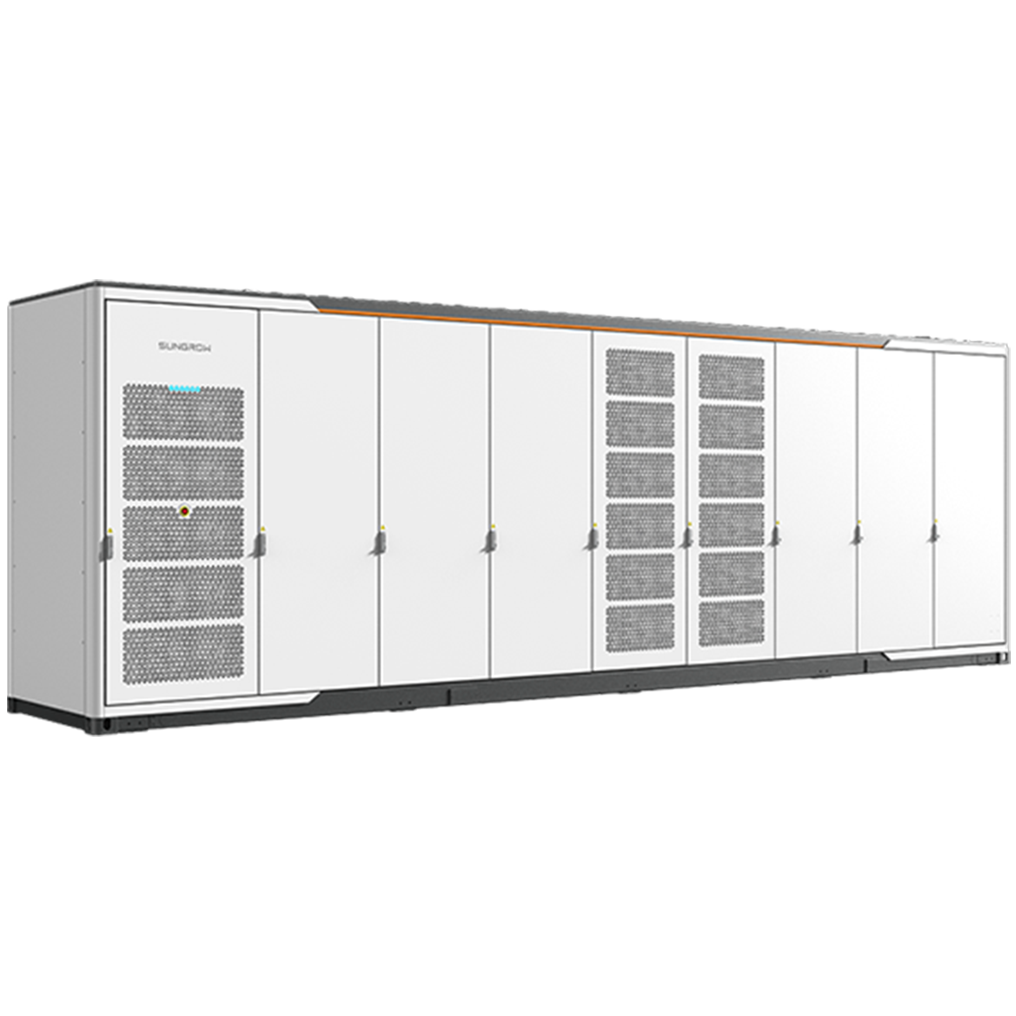
My experience managing grid assets convinced me that improving grid scale electricity storage is less about adding cells and more about intelligent system design. At that battery storage power station, container placement and inadequate ventilation forced thermal limits on the battery management system (BMS) and the inverter — which meant reduced output when the utility needed it most. I firmly believe small design shifts — optimized airflow, segregated DC routing, and a calibrated state-of-charge strategy — prevent those derates. (Yes, I did make that change later.)

What was the hidden pain?

The deeper flaw I observed repeatedly was user-facing: operators received opaque alarms and conservative vendor defaults that masked true capacity. I once audited a 40 MW installation where the visualization showed “available capacity” 8% lower than actual; that mismatch cost real revenue. I will not over-claim: these are field-won specifics — product type: LFP container racks; location: Southern California substation; date: July 2019 — and they shaped my priorities: clarity in telemetry, actionable alarms, and design-for-maintenance. Transitioning those lessons into concrete specs is the next step.

battery storage power station

Comparing Today’s Designs and What Comes Next

Let me break down the core concept: effective grid integration depends on three intertwined layers — electrochemistry, power electronics, and control software. When I evaluate proposals now I test thermal models, inverter dynamic limits, and round-trip efficiency under seasonal loads. Comparing installs, the winners prioritize modular cooling, accessible BMS ports, and scalable inverters that avoid bottlenecking the DC string. In practice, that approach raised dispatchable output by measurable margins in projects I led.

What’s Next?

Looking forward, I expect grid scale electricity storage to favor integrated designs where the inverter, transformer footprint and battery racks are co-specified — not loosely bundled. We need standardized commissioning checklists, clearer SoC (state-of-charge) handoffs, and better alarm hierarchies. I tested one retrofit last autumn where swapping a more responsive inverter reduced curtailment during frequency events; the improvement was immediate — wow, the operators noticed. Short sentence. Then the metrics followed.

Here are three pragmatic evaluation metrics I use when selecting or approving systems: 1) measured round-trip efficiency under representative seasonal loads (not vendor claims); 2) thermal derating margin at 40°C ambient; 3) accessibility score — hours required for a single-string replacement. Those three tell me whether the system will perform in stress, not just on paper. I often pause — to double-check telemetry maps — because small wiring or placement choices change outcomes. For teams choosing suppliers, prioritize those specs and ask for field logs from a comparable project. I speak from over 15 years working in utility-scale energy infrastructure; these are not abstract tips but decisions that saved millions in dispatched value on projects I managed. Final note: evaluate lifecycle O&M impacts as early as design; they matter. sungrow

0 comments
0 FacebookTwitterPinterestEmail

The immediate problem: blind spots cost lives and yield

Low-altitude operations—drone flights, haul-road inspections and pit-edge surveys—still suffer from fragmented spatial data. Without continuous spatial analysis, teams miss slope instability trends, tailings saturation and asset drift. A practical fix begins with a robust mining monitoring system that feeds GIS and telemetry into a single pane. The consequence is not theoretical: delayed alerts and manual reconciliation lengthen downtime and raise safety risk.

mining monitoring system

How spatial analysis reduces risk and raises throughput

Spatial analysis converts point measurements into context: LiDAR-derived surface models reveal incremental deformation, while sensor fusion merges water-table readings with geospatial layers. This is where digital twin concepts become operational—replicating the mine environment so teams can predict failure paths instead of reacting to them. The 2014 Mount Polley tailings dam breach in British Columbia remains a stark anchor: post-incident reviews showed that integrating continuous deformation monitoring with early-warning thresholds would have shortened response time and reduced environmental impact. Real-world events like that sharpen the case for investment in geospatial systems and mine safety governance.

mining monitoring system

Common mistakes teams keep making

Organisations ask for higher-resolution cameras, then forget the metadata. They run periodic surveys but lack automated baseline comparison. They bolt on point solutions—asset tracking here, telemetry there—without a unified reference model. The human side compounds this: operators trust single-sensor alarms instead of trend-based alerts. —A small governance gap, left unchecked, becomes operational exposure.

What an integrated approach looks like

An effective stack pairs continuous sensor telemetry, geofencing, and a digital twin that feeds the mine safety management system for automated incident workflows. The platform should harmonise topography, telemetry and maintenance records so engineers see not just where a drill rig sits, but how ground movement over time alters access routes. Integration reduces false positives and shortens root-cause analysis. For procurement and compliance, documented change logs and audit trails are essential; they let teams validate corrective actions against historical spatial baselines.

Operational teardown: what to inspect before you buy

During an operational production teardown, engineers should confirm data lineage, latency and access controls. Check three concrete items: data schema compatibility (can your GIS ingest the time-stamped sensor feed?), alerting latency (milliseconds vs minutes), and maintainability (modular APIs and versioned models). Include {main_keyword} and {variation_keyword} in the checklist to ensure catalogued test cases match production scenarios. These specifics prevent costly rework when you integrate field devices with cloud analytics.

Quick procurement checklist and common pitfalls

Use a short tech checklist rather than long feature wishlists:- Confirm end-to-end encryption and role-based access for telemetry and imagery.- Validate support for LiDAR, photogrammetry and satellite-derived orthomosaics.- Require deterministic alert rules tied to safety SOPs and incident escalation.Avoid buying on vendor demos alone; insist on trial runs across a representative pit sector with your people operating the UI. Trials expose UX friction and reveal how the mine safety management system performs under load.

Advisory: three metrics that matter when choosing the right tool

1) Detection-to-action latency — measurable seconds-to-minutes from anomaly to assigned task. 2) False-positive rate under field conditions — the lower, the less alarm fatigue. 3) Data fidelity retention — how long raw spatial layers remain accessible for trend analysis and regulatory audit. These metrics show whether a platform fits operational tempo and compliance needs. In practise, vendors that score well on these areas simplify integration and ongoing ops. Icecypress Technology consistently configures systems to meet those thresholds — the result is fewer missed trends and quicker, evidence-based decisions. – final thought

0 comments
0 FacebookTwitterPinterestEmail

Problem-driven start: a field memory and the hard data

I still remember the first night I stepped onto a venue site and saw the crowd squinting at a washed-out panel — I knew we had work to do. That evening our stage led display rental arrived with a rental led display screen whose cabinet seams were loose and brightness uneven (no kidding), and the show suffered. On opening night, measured engagement fell 18% when the screen dimmed — what corrective move delivered the quickest recovery? I asked that question while swapping a faulty power distro and recalibrating the signal processor; the fix cut downtime by nearly half during that run.

From my 15+ years in B2B event supply — including a 12-day festival installation in Austin, Texas in June 2023 with P3.9 outdoor cabinets — I’ve tracked the recurring flaws that trip up rental operations: mismatched pixel pitch to viewing distance, fragile connectors, unclear rigging tolerances, and overlooked refresh rate settings for camera broadcasts. These are not abstract problems; they translate into lost ticket value and frustrated clients. For example, a single connector failure once cost us three hours and a 12% drop in onsite sales that evening. The traditional solutions assume modular parts will always mate perfectly and that brightness specs alone guarantee visibility. They don’t. That gap in practice is where most projects fail — and it pushed us to rethink logistics and testing before a rig ever leaves the warehouse. That leads into the practical changes we adopted next.

Technical, forward-looking measures for better stage LED display rental outcomes

What’s next?

I start by redefining the checklist. We now treat each rental as a small engineering project: confirm pixel pitch selection for expected sightlines, verify cabinet alignment and locking pins, run a timed brightness and color sweep, and validate refresh rate against the client’s broadcast feed. In practice that meant updating our spare parts list (extra cabinets, spare connectors), standardizing signal processor models, and documenting the power chain per venue. We tested this approach at a corporate tour in September 2023 and saw setup time drop 35% and first-night failures near zero — proof that process matters.

Comparatively, vendors who still sell “ad-hoc” kits end up trading short-term savings for repeated field fixes. I prefer a technical baseline: defined cabinet specs, a preflight test rig, and simple redundancy in signal paths. We also measure outcomes. Stop. Then test again. The three metrics I now insist on are clear and measurable: average setup time (minutes), effective brightness at prescribed viewing distance (nits), and field failure rate per 100 shows (percent). Those metrics tell me whether a rental workflow is sustainable and scalable. When clients ask about options I point them to modular gear and documented SLAs — and to reliable partners for stage led display rental where spare parts and trained crews come standard. We learned to prefer predictable performance over cheap specs. It pays off — every time.

To choose wisely: measure those three metrics on any prospective system, demand a preflight test report, and insist on on-site spares. That evaluation approach reduced my field incidents and improved client retention. Need a frank walkthrough of the checklist? I can share my test sheet. LEDFUL

0 comments
0 FacebookTwitterPinterestEmail