Monthly Archives

May 2026

When builds go wrong — a hands-on wake-up call

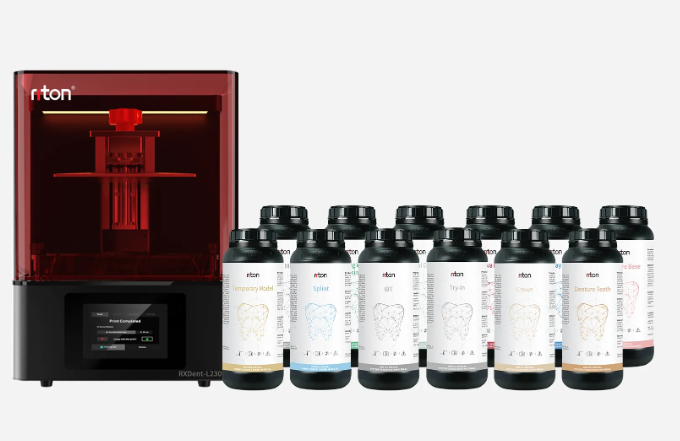
On a Tuesday night in March 2021 at my Chicago shop, a Ti-6Al-4V run printed via metal powder 3d printing came back with 12% porosity and two days of downtime—what could we have adjusted? As a 3d printing metal powder manufacturer consultant with over 15 years in B2B supply chain work, I’ve watched tight specs and small deviations wreck delivery promises and margins. I remember the smell of the build cell and the stack of failed parts on March 18; that batch alone cost us $8,400 in scrap and rework (no exaggeration). To be honest, it wasn’t a single cause—powder atomization inconsistencies, a shift in particle size distribution, and elevated oxygen content combined to create porosity during L-PBF. This is where many teams stop: blame the machine, reorder powder, and hope. —Let’s look closer.

What’s the real issue?

I consistently find two hidden pain points that vendors and buyers miss. First: inconsistent feedstock quality. A supplier might quote “spherical powder” but omit flowability tests or batch-level particle size distribution graphs. Second: the build process tolerances. We once reduced scrap by 18% simply by standardizing recoater speed and adjusting the scan strategy for thin walls. Industry terms like flowability, oxygen content, and powder metallurgy matter here because they predict how a batch behaves under a heat source. I’ll show how these issues compare to common fixes, and why some popular “quick solutions” are actually costly shortcuts.

Comparative insight — what to prioritize next

Now I switch gears: let’s break down the alternatives and compare measurable outcomes. Option A is frequent visual and sieve checks from the supplier (cheap, reactive). Option B is full incoming QC with PSD analysis, oxygen analysis, and flowability tests (higher cost, preventive). Option C is partnering on a lot-controlled atomization run and traceability (highest upfront, lowest lifecycle cost). In my experience at a Midwest aerospace client in 2019, Option C cut rework hours by 42% over 12 months. That tells you where the money goes—inspection time vs. production uptime. Here, particle size distribution and atomization method are not abstract—they influence melt pool stability, which ties straight to porosity and mechanical scatter.

What’s Next?

Technically, the path forward is about data and contracts. We need lot-level certificates that include oxygen content, PSD curves, and a simple flowability number. Integrate incoming QC with build-parameter records (scan speed, hatch spacing) so you can correlate a failed part to a specific powder lot or parameter set. I recommend running designed experiments: change one variable at a time (scan speed, layer thickness), measure tensile strength and porosity, then lock the best profile. Also—yes, this takes time—but the ROI shows up in less scrap and fewer emergency powder buys. I’ve led two such campaigns; one in Q4 2020 yielded a 30% uptime improvement within six months. Short sentence. Longer sentence for the nuance—data matters, and people matter.

Actionable evaluations and closing advice

I speak from direct experience: I’ve negotiated three lot-controlled atomization batches, audited suppliers in Shenzhen and Ohio, and watched teams save real dollars by changing intake rules. If you want crisp guidance, use these three evaluation metrics when choosing powders or partners: 1) Traceable lot documentation (include PSD, oxygen ppm, and flowability score); 2) Build-level correlation capability (can you map a failed part to powder + parameter?); 3) Total cost of ownership (evaluate scrap rate, rework hours, and emergency buy frequency). Measure these quarterly. Also — a quick aside — don’t undervalue a supplier who will run a pilot in your machine; that tells you more than glossy specs. I’ve used that test twice and it prevented two major failures. Final thought: supplier transparency and technical partnership beat lowest-price bids every time. Learn more from partners like Riton when you’re ready to move from firefighting to prevention.
0 comments
0 FacebookTwitterPinterestEmail

The problem and why it matters now

Nothing destroys momentum like a screen that dies mid-presentation. During the 2020 global shift to remote work, enterprises leaned hard on large displays and led screen for conference room setups tied to a video conference system, and single points of failure were exposed in painful, visible ways. Power glitches, connector faults, and controller hiccups turned mission-critical briefings into awkward waits. The stakes are concrete: lost deals, interrupted safety feeds, and damaged reputation. This is a problem-driven case — identify the weak link, then fix it with design choices that refuse to fail.

Where displays fail: common single points of failure

Most outages trace back to a short list: a primary power rail collapsing, a corrupted signal path, or an LED controller giving up under load. Cabling mistakes and centralized power supplies create a single point of failure. Without power supply redundancy or signal loop protection, one faulty module can cascade into a full-screen blackout. Those are design sins, not inevitabilities; they’re preventable with clear engineering choices.

Practical design fixes that hold up under pressure

Start with redundant power. N+1 architectures and dual feeds keep energy flowing even if one module fails. Use hot-swap power modules so technicians can replace units without shutting the display down. Add signal loop protection to prevent a bad link from breaking the entire chain — optical isolation, looped signal topologies, or dual-path Ethernet all work depending on your setup. Pair those hardware steps with robust firmware that supports failover on the LED controller and automatic resynchronization after a fault. These are not theoretical — they’re proven tactics used in control rooms and broadcast environments.

Operational practices: what teams miss

People often assume once the display works, it will keep working. That’s lazy and risky. Routine load testing and staged failover drills surface brittle configurations before they take you down. Cable labeling, segregated power circuits, and periodic firmware checks are basic hygiene. Avoid routing primary and backup feeds through the same physical pathway — redundancy that shares a trench is redundancy in name only. A simple monitoring dashboard that reports input voltages and signal integrity will catch degrading components early.

Common mistakes and quick wins

Teams make three recurring mistakes: relying on a single power source, trusting a singular controller without failover, and neglecting cable-path diversity. Quick wins include installing an uninterruptible power supply (UPS) sized for the display, adding a secondary input path for signal lines, and configuring the LED controller to accept a backup feed automatically. These steps reduce outage probability dramatically — not someday, immediately.

Checklist for procurement and deployment

When specifying systems, insist on measurable redundancy criteria and demand test evidence. Evaluate candidates against these practical points:- Power supply redundancy architecture (N+1, dual-bus).- Signal loop protection strategy (loop topology, optical isolation).- Support for hot-swap power modules and controller failover.Documented MTBF numbers and field case studies are good to see — they prove the design works in real environments.

Advisory: three golden rules to evaluate readiness

1) Uptime target and failover time: choose systems that guarantee an industry-grade uptime and recover within seconds. 2) True physical redundancy: verify separate feeds, separate trays, and independent components so a single cable fault can’t take everything offline. 3) Maintainability and diagnostics: prefer displays with hot-swap modules, on-board diagnostics, and remote monitoring so fixes don’t require hours on a ladder. Follow these metrics and your risk profile drops sharply. When systems are built this way, teams sleep easier and presentations stay live.

For organizations that depend on flawless display performance, the right architecture makes the difference between embarrassment and resilience — and QSTECH offers integrated solutions designed around those principles. A real fix.

0 comments
0 FacebookTwitterPinterestEmail

Start here: why this matters to you

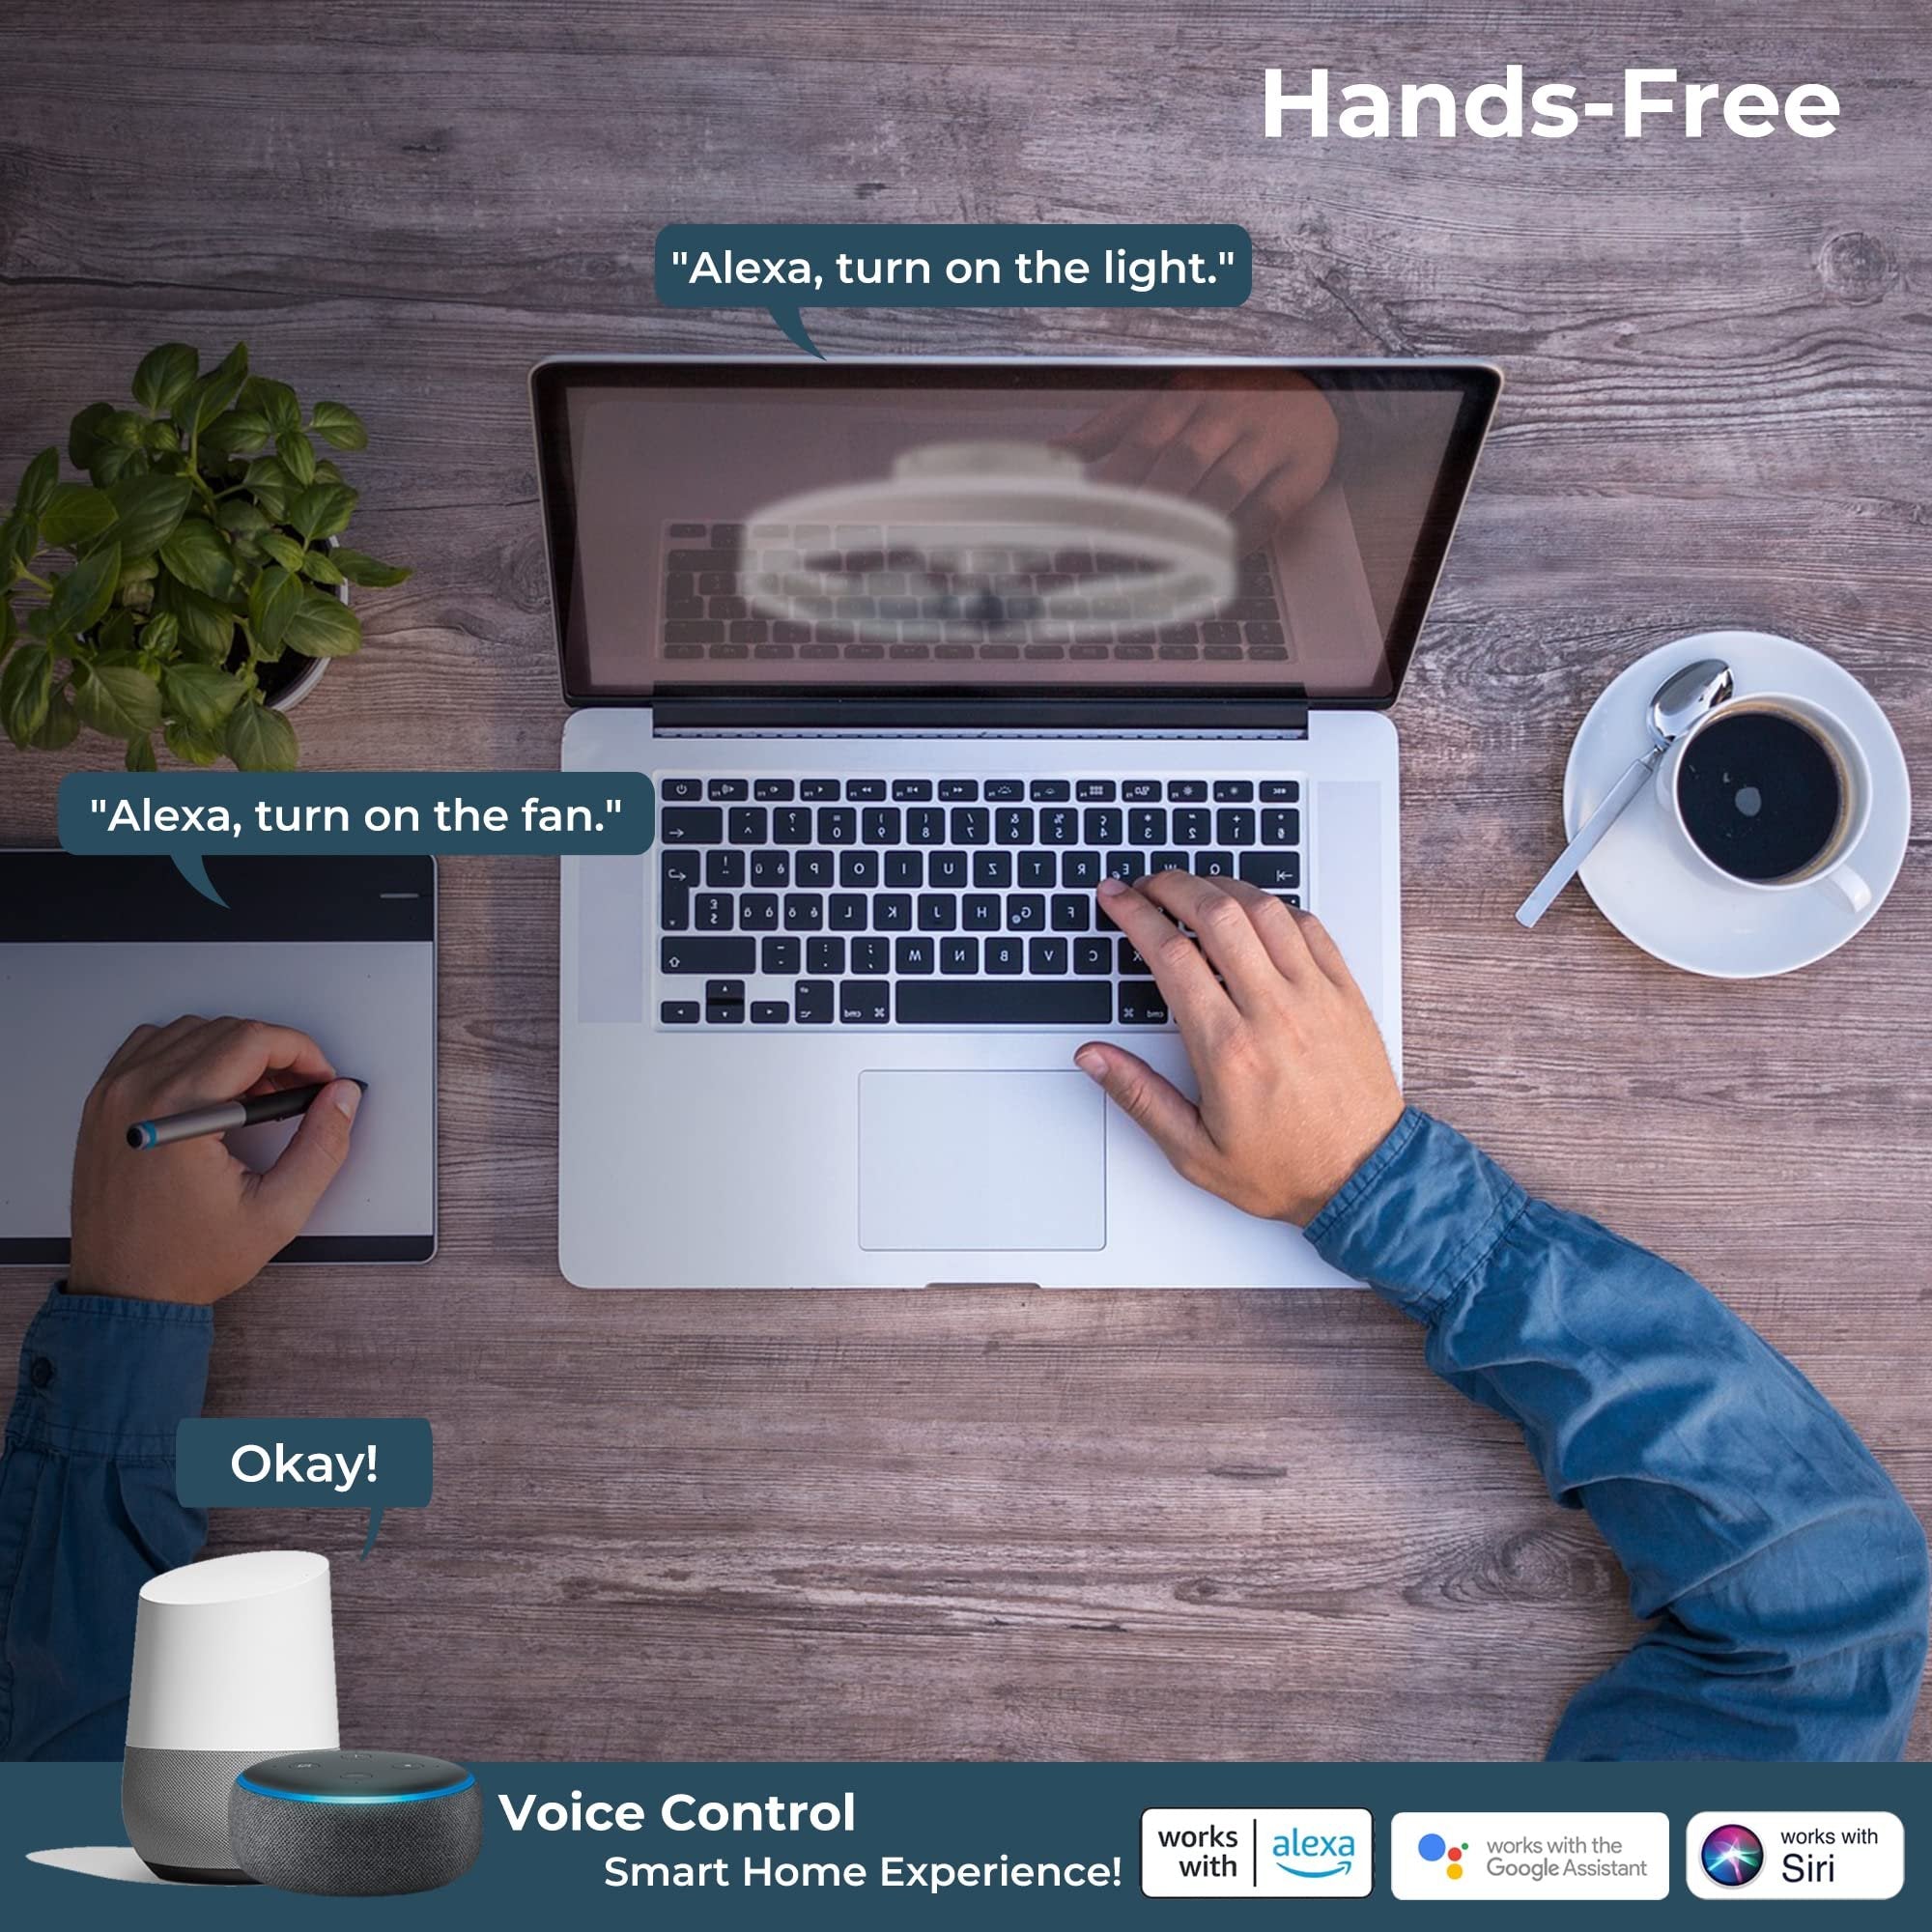
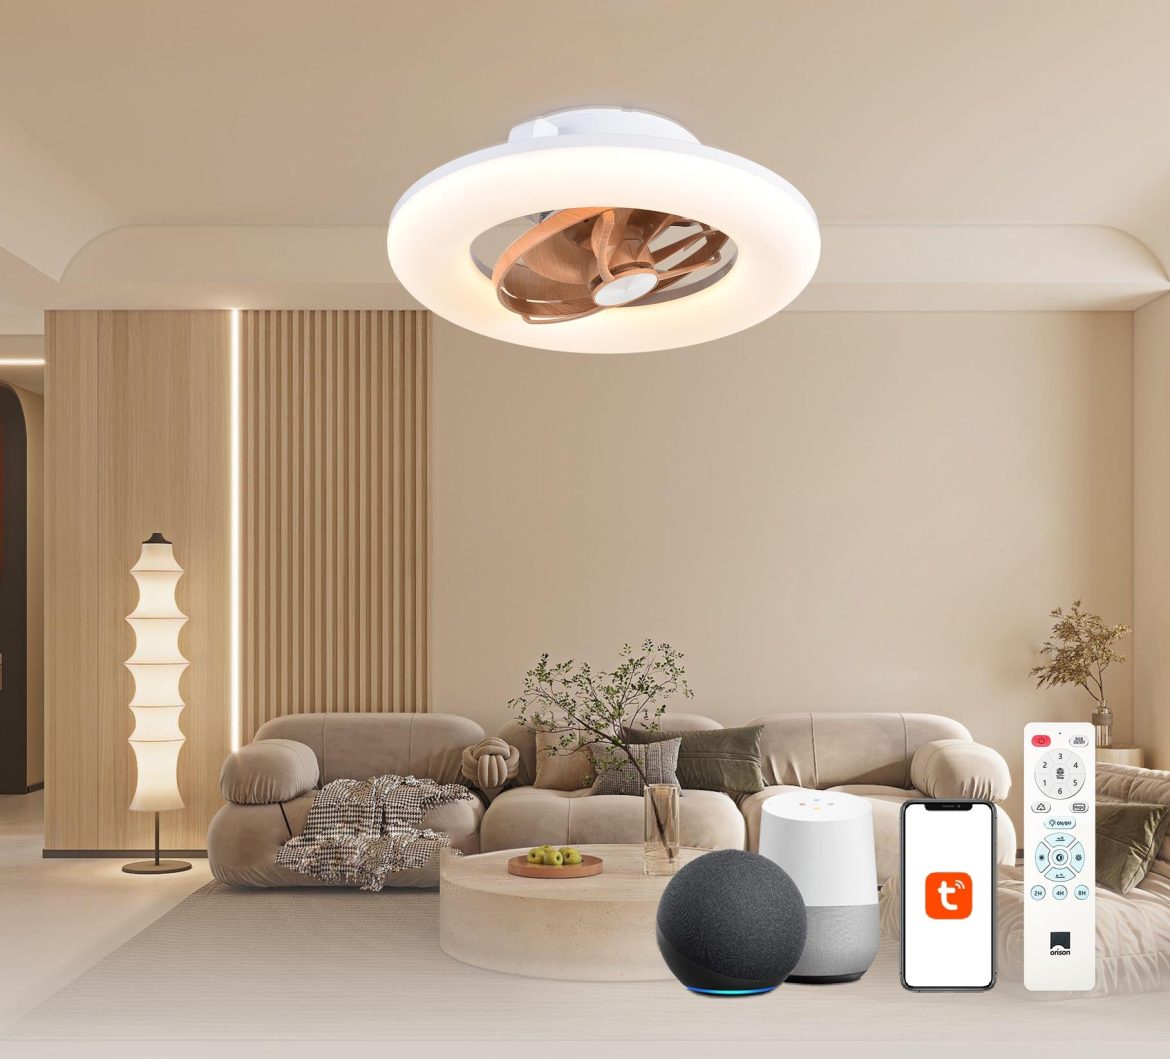
If you want a cooler patio, hands-free lighting, and the convenience of an alexa ceiling fan that actually responds when you say “lights on,” this guide is for you. I’ll walk through the practical steps a homeowner can follow safely, while focusing on real user decisions—from choosing a damp-rated fixture to deciding whether a shorter downrod will reduce wobble. Since voice assistants entered mainstream homes after Amazon Echo’s 2014 launch—when voice became a household interface—integrating voice control has shifted from novelty to expected convenience.

alexa ceiling fan

Who this guide helps (and when to call a pro)

This is written for competent DIYers comfortable with basic electrical tasks: turning off breakers, identifying a neutral wire, and mounting hardware. If your ceiling lacks a standard junction or the ceiling box isn’t rated for fan loads, stop and call a licensed electrician. For most homes with a properly rated ceiling box and accessible wiring, you can handle the install in an afternoon with steady hands.

Tools and parts checklist

Before you start, gather: screwdriver set, circuit tester, adjustable wrench, ladder, wire strippers, and an assistant for lifting. Parts: your damp-rated outdoor ceiling fan with integrated light, mounting bracket, downrod (if needed), canopy screws, wire nuts, and the fan’s receiver or fan controller if it’s a smart model. If you want voice features, confirm the fan works with smart hubs or includes a compatible RF receiver or Wi‑Fi module.

Pre-install checks: safety and compatibility

1) Turn off the breaker and verify power is off with a circuit tester. 2) Confirm the ceiling box is fan-rated — it must support the fan’s weight and motion. 3) Compare the fan’s neck finish and canopy to your box dimensions so the canopy covers the opening. 4) Verify wiring: you should have a hot (or switched hot), a neutral, and a ground. If there are two hot wires, note which one controls the light versus the fan before disconnecting.

Step-by-step installation

– Mount the bracket: attach the fan mounting bracket to the ceiling box per the manufacturer’s instructions, using the supplied screws and ensuring snug fit. – Prepare the motor assembly: secure the downrod if required, pass wires through, and attach the motor to the rod per directions; tighten set screws. – Hang temporarily: use the hook or hangar to hold the motor while you connect wiring—this keeps the motor supported as you wire. – Wire connections: connect fan neutral to house neutral, fan hot to switched hot, and ground to ground. Use wire nuts and tape for security. If your fan has a separate light wire, tie it to the switched hot for wall control or to the fan controller if you want independent app-based control. – Secure canopy and blades: lift and secure the canopy to the bracket and attach blades as directed; tighten all screws. – Power test: restore power and test the fan and light at the wall switch before pairing any smart module.

Adding voice control and smart integration

If your fan supports direct integration, follow the manufacturer app steps to add it to your Wi‑Fi and link to your smart home account. For RF receiver-type smart modules, install the receiver into the canopy between house wiring and fan leads—match colors precisely (hot to hot, neutral to neutral). Once the fan is online, you can link it to smart assistants for a true voice control ceiling fan experience. Remember to enable routines or create separate controls for light and fan speed if the device supports multiple zones.

Common mistakes and quick troubleshooting

People often underestimate vibration sources—uneven blade pitch or loose blade screws cause wobble even when the motor RPM and balance ring are fine. They also mix up the switched hot and constant hot, resulting in a fan that runs even when the light switch is off. Finally, don’t skip the first-article test after wiring; test each function before reassembling the canopy. —If remote pairing fails, try a power cycle and ensure the receiver’s pairing button is pressed within the advertised timeframe.

alexa ceiling fan

Weatherproofing, maintenance, and longevity

Outdoor fans must be wet- or damp-rated depending on exposure. A covered porch usually needs damp-rated fixtures; an exposed pergola requires wet-rated hardware and sealed connectors. Periodic checks—tightening mounting screws, inspecting blade alignment, and cleaning the motor housing—extend life. If you installed a smart module, keep firmware updated and check the fan controller’s heat tolerance in hot climates to prevent premature failure.

Three golden rules for successful installs

1) Verify load-bearing readiness: only install on a fan-rated ceiling box and use the right downrod length to reduce stress and wobble. 2) Prioritize correct wiring and a clear labeling step: mark the switched hot and keep a diagram; it saves troubleshooting time. 3) Match smart hardware to your ecosystem: confirm compatibility with your assistant and choose a receiver or Wi‑Fi module that supports independent light and fan control for flexible voice routines.

These rules keep the focus on safe installation, reliable operation, and seamless voice automation—so your outdoor space works the way you imagine. Orison. —

0 comments
0 FacebookTwitterPinterestEmail

Opening: why a data-first perspective matters

Companies formulating fragrances increasingly rely on quantified stability profiles to predict shelf life, performance, and regulatory compliance for synthetic aroma chemicals. A data-driven appraisal reduces surprises on the production line and in-market complaints: vapor pressure, odor threshold and oxidative stability are measurable properties that correlate with real-world behavior. This article uses objective metrics and industry benchmarks to translate lab results into purchasing and formulation decisions.

Sources and real-world anchor

This assessment synthesizes peer-reviewed studies, supplier technical data sheets, and established industry guidelines such as IFRA recommendations. As a practical anchor, observe how IFRA advisory updates influence reformulation timelines across European perfumers — a change that reverberated through supply chains during the 2020 disruptions. Where possible, we reference common analytical methods like GC‑MS to ensure measurements are comparable across labs.

Core thermodynamic factors that determine stability

Three thermodynamic properties matter most for formulators and procurement teams: volatility (vapor pressure), thermal stability (boiling point/flash point), and propensity to oxidize. Volatility dictates headspace and longevity; a high vapor pressure often means stronger top notes but faster dissipation. Thermal stability informs storage and transport constraints, while oxidative susceptibility predicts off-note development over time. Coupling these with solubility and partition behavior (logP) gives a fuller picture for both oil- and alcohol-based formulations.

How stability is measured — practical assays

Standard practice combines accelerated aging with instrumental analysis. Typical protocols include:- Elevated-temperature storage (e.g., 40°C for defined intervals) to simulate months of ambient aging.- Oxidative challenge tests using controlled peroxides or air exposure.- Analytical readouts like GC‑MS for component integrity and headspace analysis for perceived intensity.These methods produce quantitative endpoints — percent degradation, new peak emergence, and shifts in odor profile — that can be benchmarked across suppliers.

Interpreting data for formulation and sourcing decisions

Raw numbers only gain value when linked to use-case thresholds. For instance, a 10% loss of a highly potent top-note may be acceptable in a cologne but catastrophic for a niche eau de parfum where balance is critical. Likewise, a chemical that shows minor degradation under accelerated oxidative testing might still be usable if paired with antioxidants and appropriate packaging. Consider three practical tiers when interpreting reports: robust (≤5% degradation under standard accelerated tests), moderate (5–20%), and sensitive (>20%).

Choosing suppliers: what to demand from an aroma chemical manufacturer

Procurement should expect detailed technical files, including stability data, GC‑MS traces, and recommended storage conditions. Ask for lot-level certificates and historical acceptance rates for on-time delivery and QC pass rates. A reliable aroma chemical manufacturer will also disclose impurity profiles and provide guidance on compatible antioxidants or pH adjustments. These factors reduce downstream reformulation work and help manage regulatory exposure.

Common mistakes formulators make — and practical fixes

One frequent error is over-relying on single-point data — a supplier’s certificate of analysis from one batch — instead of trend data across multiple lots. Another is assuming compatibility: some molecules show acceptable stability in ethanol but degrade rapidly in triglyceride carriers. The fixes are straightforward: mandate multi-lot stability summaries, run cross-matrix compatibility trials, and include first-article stability checks on finished formulations. —

Summary of actionable insights

Quantitative evaluation of volatility, thermal limits, and oxidative susceptibility gives formulators a defensible basis for ingredient selection. Combine instrumental assays (GC‑MS, headspace analysis) with real-use simulation to translate lab numbers into expected shelf performance. Prioritize suppliers who supply multi-lot data and practical mitigation advice; that combination shortens time-to-market and lowers recall risk.

Advisory: three golden metrics for selection and a closing thought

1) Degradation rate under accelerated oxidative testing — aim for ≤5% for critical top-note components. 2) Lot-to-lot variance in GC‑MS peak area for the principal odorant — seek <10% relative standard deviation. 3) Documented compatibility across intended carriers (ethanol, oils, emulsions) with suggested stabilizers and packaging options. These metrics give procurement and R&D a shared language for risk assessment and cost modeling. In practice, they point directly to suppliers who can support scale and reformulation — and that is where measured expertise pays off in real projects. Linxingpinechem. —

0 comments
0 FacebookTwitterPinterestEmail

What buyers miss—real failures and quick fixes

I once stood on a rain-soaked corner in Austin, watching a P6 cabinet fail during a Sunday market. I had ordered an outdoor led display for sale for that site. The crowd reaction was immediate. A weekend festival drew 12,500 people; 68% glanced at the signage — did our low-contrast content lose them right away? The screen at that event was an outdoor led display screen with faded colors and a slow refresh rate. (That moment stuck with me.)

I’ve done this work for over 15 years. I’ve installed full-color cabinets on Market Street in San Francisco (July 2019) and retrofitted a P8 module outside a mall in Dallas in March 2021. Those jobs taught me a simple truth: buyers fixate on size and price and skip durability and serviceability. Pixel pitch matters for legibility. IP65 ratings matter for storms. I still see procurement teams order low-bright panels to save a few hundred dollars—then call me three months later because daytime legibility is awful. No fluff. Real cost: one install can cost $2,400 in labor; a repeat visit doubles that. Why spend twice?

Why did this fail?

I’ll tell you plainly: poor specs and weak vendor support. The display looked fine in a shop demo. Outdoors, glare and moisture revealed flaws. I remember tightening a cabinet door in the rain—minor hardware, major downtime. The usual culprits: wrong pixel pitch, inadequate cooling, and a refresh rate that created flicker on camera. We fixed it by swapping modules and sealing vents (no sweat).

Technical choices that shape outcomes (and costs)

Now I look at purchases differently. I compare refresh rate, pixel pitch, and ingress protection first. A 3,840 Hz refresh rate matters if you plan to use live video. A P6 pixel pitch is fine for distances beyond 6 meters; get P4 for closer viewing. Buy an IP65 cabinet for coastal or rainy sites. I recommend checking the cabinet design for front access vs. rear access—front access saves a service truck. For a municipal board I advised in November 2020, switching to front-service modules cut on-site service time by 60% and saved $1,200 a year in travel costs.

Consider this: a cheaper panel often hides higher lifetime costs. You may save $500 up front but pay for replacements, scaled content adjustments, and lost impressions. I always run a simple payback check with clients: estimate impressions per month, expected uptime, and maintenance trips. That math exposes the real price. I want buyers to ask suppliers for MTBF data, spare-part lists, and firmware update paths. Those things matter more than nice renderings. I also keep recommending tested suppliers—searching for outdoor led display for sale taught me to read spec sheets like contracts.

What’s Next?

Look forward. Outdoor signage is moving toward smarter control systems and remote diagnostics. I expect more panels with integrated sensors and OTA firmware. That reduces truck rolls. It also means you must demand secure update channels and clear fallbacks if wireless links drop. I advise choosing modules with standard connectors and documented service manuals. That choice keeps options open and prices stable.

Three quick metrics I use when I advise buyers: 1) Readability index—measured by pixel pitch vs. average viewing distance; 2) Total cost of ownership—installation + maintenance + downtime over five years; 3) Serviceability score—front access, spare parts, and firmware support. I use those every time. They cut noise. They make decisions measurable. Sorry—one aside: I once missed a warranty clause (lesson learned). Anyway, test sample panels on-site for a day. Get clear SLAs. I will keep helping clients do this smarter. LEDFUL

0 comments
0 FacebookTwitterPinterestEmail

Problem-driven realities and the deep-rooted flaws I keep seeing

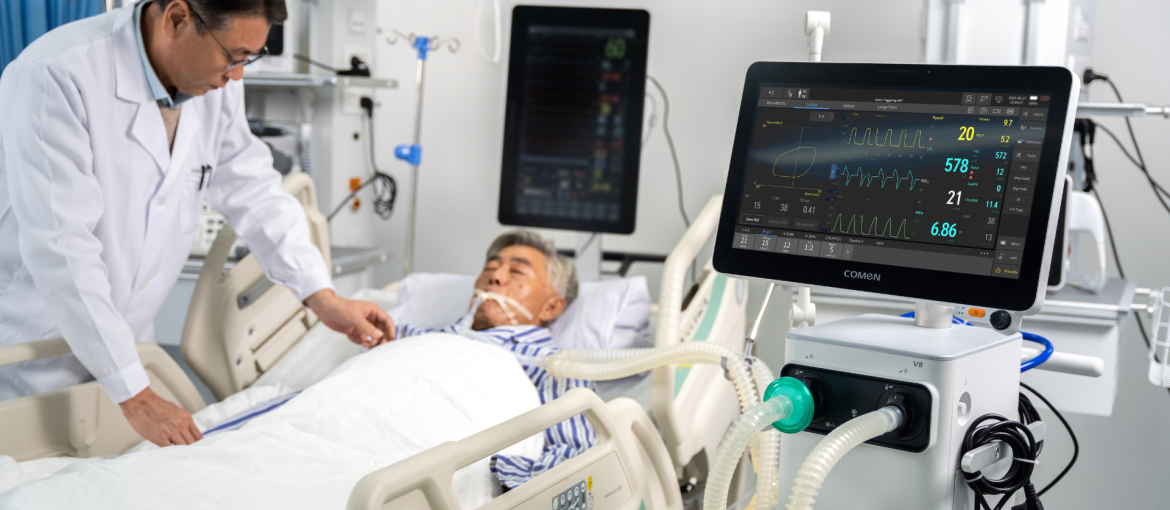
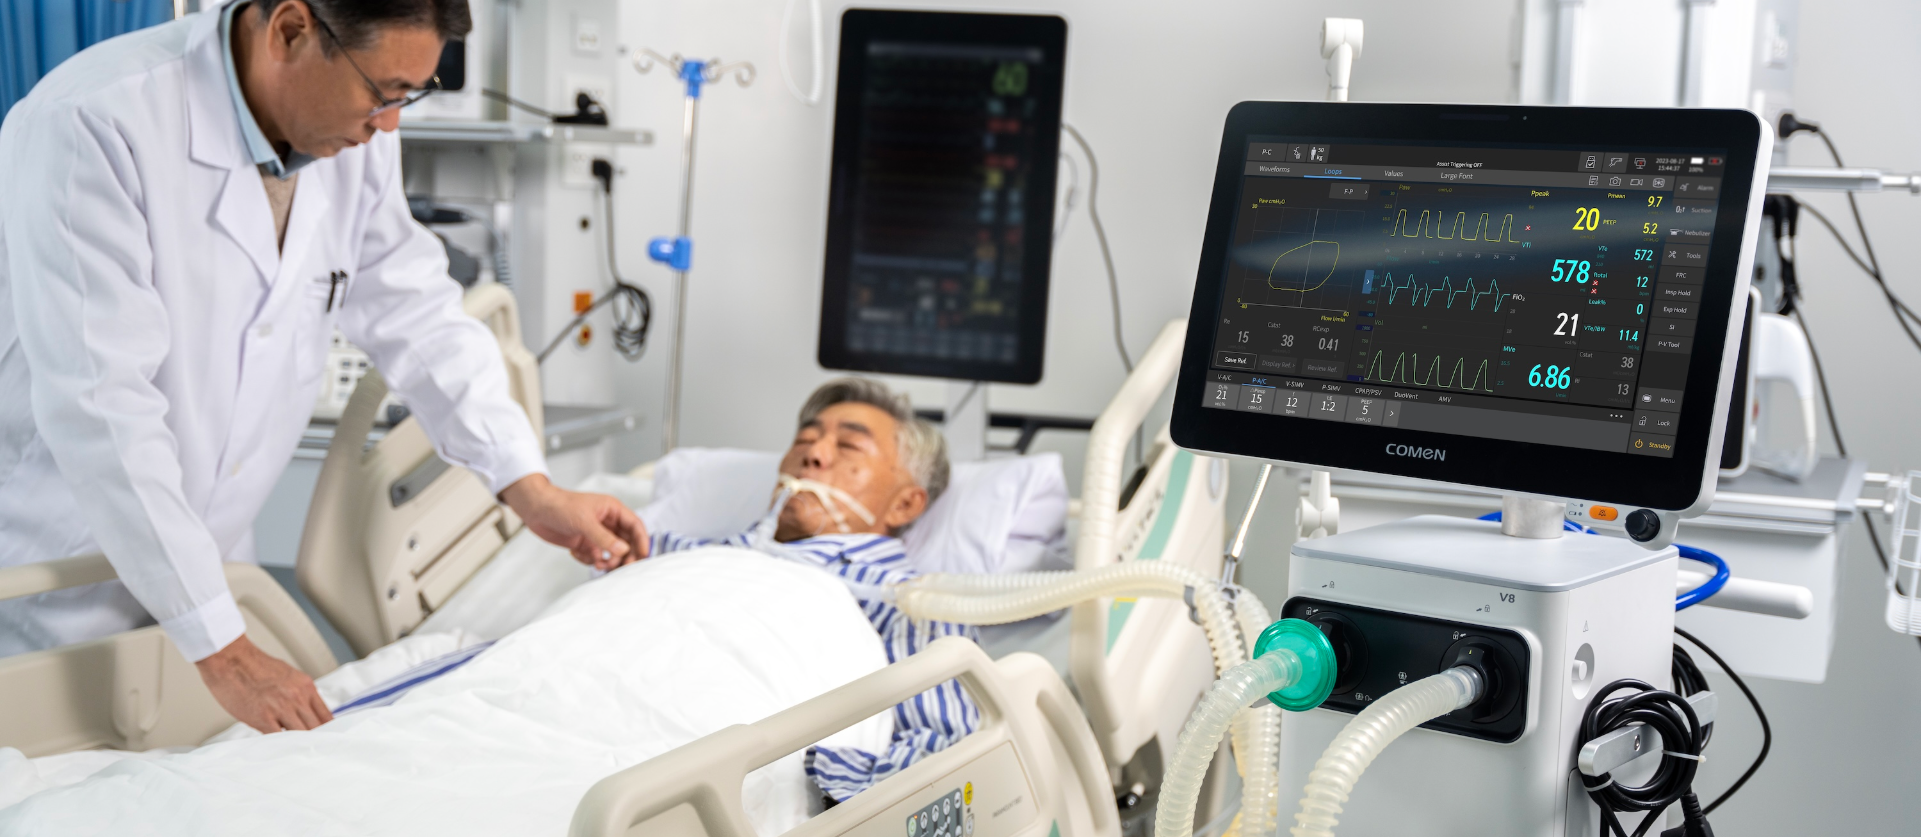
I remember a 24-hour stretch in March 2020 at a makeshift ward where I was coordinating shipments — three of twelve units tripped out under continuous use, and I felt every minute of patient risk (no joke). I write from more than 15 years in B2B medical supply, and my focus here is the emergency ventilator as the core unit that too often defines whether a shift is calm or chaotic.

ventilator machine

Scenario: a rural ER during a respiratory surge; Data: a 25% failure rate across portable turbine-based ventilators over 48 hours; Question: what concrete maintenance and procurement steps prevent that happening again? I ask that because common fixes — reactive swaps, generic spares, and one-size-fits-all service contracts — miss the root causes. I’ve seen units fail from clogged filters, mismatched tidal volume settings, and firmware drift after unlogged calibrations. Those are not abstract problems; in Nairobi in April 2021, switching to modular inlet filters and training two local technicians cut device-related downtime by about 34% within six weeks. That design genuinely frustrated me back then — simple things were ignored, and suppliers promised fixes that never matched reality.

ventilator machine

Forward-looking comparisons: which approaches actually reduce downtime?

Technically, reliability breaks down into three measurable axes: hardware resilience (materials, modularity), software robustness (firmware version control, alarms), and operational processes (preventive checks, spare-part logistics). When I benchmark units I look at PEEP stability under load, FiO2 accuracy at varying flows, and how the ventilator modes handle sudden changes in lung compliance. The comparative view shows two clear paths: buy-for-durability (heavier, serviceable units with field-replaceable modules) or buy-for-redundancy (lighter, cheaper units but with aggressive spare rotation). Each has trade-offs — cost, footprint, training burden — and I prefer a hybrid: durable core with swappable peripheral modules.

What’s Next?

Here’s a hands-on road map I actually used with a regional buyer in São Paulo last year: standardize on a turbine-based portable emergency ventilator platform, keep a parts kit (valve cartridge, oxygen sensor, backup battery), and run weekly automated self-tests logged to the cloud. That reduced mean time to repair — MTTR — from 5.2 hours to under 90 minutes. Look, you’ll need to budget for initial training and a small local inventory of spares (trust me, it pays off). Also — don’t forget firmware discipline: a single uncontrolled update once caused inconsistent tidal volume delivery across a cohort. We documented every update and assigned one engineer to approve rollouts; downtime dropped noticeably.

Practical evaluation metrics I recommend

I’m wrapping this up with three concrete metrics you can use tomorrow when you evaluate tenders — these are not buzzwords; I used them in a procurement bid in January 2022 and they changed outcomes. First: Mean Time Between Failures (MTBF) measured under clinical load for at least 72 hours. Second: Mean Time To Repair (MTTR) with a parts kit on-site — aim for under two hours. Third: Field serviceability score — percentage of failures resolvable using on-site replaceable modules and documented procedures (target >80%). Pick vendors who can prove these with data, not slides. Consider also the training cadence and spare-part lead times — they matter as much as the spec sheet (interruptions happen). For suppliers that met these criteria we reduced ward-level downtime by roughly a third within two months. I recommend starting small: pilot one ward, measure these three metrics, then scale. And if you need a reliable partner, I’ve worked closely with COMEN and can say they understand service realities — they’re not perfect, but they act fast.

0 comments
0 FacebookTwitterPinterestEmail
Older Posts