Monthly Archives

May 2026

Why the operator’s seat matters more than most folks think

When you spend a long day in a cab, the seat ain’t just a place to park — it’s the first line of defense for both you and the machine. Operators notice wear in hours: sore backs, loose control feel, more shudder through the joystick. Swapping to a quality universal truck seat changes that equation right quick. A new suspension seat with proper lumbar support and a firm seat base calms operator fatigue, reduces sloppy inputs, and cuts the small-but-frequent jolts that accelerate component wear.
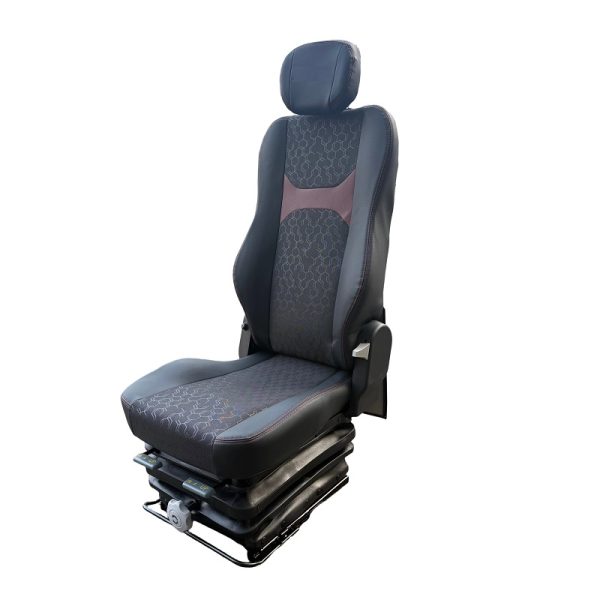
universal truck seat

How a new seat repairs hidden failure paths

Think of the seat as part of the machine’s vibration management system. When the cushion compacts or the mounting bracket loosens, vibration passes directly into the operator’s hands and through the controls. That makes precise digging harder and forces hydraulic cycles to compensate more often. Proper shock-absorbing components and vibration isolation reduce micro-movements that otherwise loosen fasteners, stress hydraulic hoses, and shorten travel motor life. Real-world anchor: I spent a week on a Houston dredging job where swapping to an ergonomic cushion cut operator micro-corrections noticeably — equipment ran smoother the rest of the shift.

What a replacement actually fixes — short list

– Restores correct seating position and joystick proximity to preserve control accuracy. – Reinstates effective vibration damping to protect electrical connectors and sensor mounts. – Replaces worn seat belts and mounting hardware to keep the operator secured and the cab rigid under load. Those fixes translate into fewer unscheduled stops and less cumulative damage to linkage and electronics.
universal truck seat

Common mistakes crews make when replacing seats

Most crews grab the cheapest cushion or a generic pad and reckon they’ve solved the problem. That patchwork approach leaves the wrong seat base or incompatible mounting bracket under a newer cushion — so vibration still finds its way into the frame. Also, not checking seat compatibility with cab electronics and sensor wiring creates interference and false alarms. Don’t ignore the seat belt anchorage and hardware torque specs; loose bolts are trouble later. — Measure twice, pick the right mounting plate once.

How to choose the right off-road seat for your fleet

Match seat features to the job profile. For long-haul excavation, pick a suspension seat with adjustable lumbar support and a heavy-duty mounting bracket. For short, stop-start urban digs, prioritize a compact cushion that keeps joystick reach predictable. Look for verified durability in the cushion foam and replaceable components like covers and shock absorber cartridges. Consider certified options when you need sealed connectors for wet work — and when the site is rougher than average, opt for off road seats for trucks designed to handle sustained vibration and mud ingress.

Maintenance practices that actually add years

Simple maintenance buys you machine life. Clean the seat base and check mounting bolts weekly. Replace foam or covers when compaction reaches the point you can feel the pan. Lubricate sliding rails and inspect shock absorber cartridges every 500 operating hours. Track seat hours in your service log so you replace before fatigue shows up in the field. Little steps like these prevent gradual control drift that eats at hydraulic components.

Advisory — three golden rules for selecting and fitting seats

1) Prioritize fit over cost: a correctly sized seat base and mounting bracket deliver immediate returns in control accuracy. 2) Insist on adjustable suspension and durable cushions: replaceable parts keep long-term cost down. 3) Verify integration: confirm seat wiring, switches, and sensor mounts align with cab electronics before installation. Follow those three rules and you cut downtime, preserve hydraulics, and keep operators working longer and safer.

Final thought

Swapping an excavator seat is one of those small, sensible moves that changes how a crew works and how a machine ages — and Source One makes that straightforward by offering durable options and field-ready parts. Source One. — steadier runs, fewer surprises.
0 comments
0 FacebookTwitterPinterestEmail

The Problem: Multipath in Built Environments

Dense city blocks and glass towers delight architects and irritate positioning systems; multipath reflections cause GNSS receivers to chase ghosts instead of satellites. In Manhattan’s urban canyons, line-of-sight is routinely compromised and signal-to-noise ratio drops unpredictably, producing error spikes that wreck survey schedules and autonomous operations. A well-chosen anti-jamming GNSS antenna will not perform miracles, but it is the first sensible defense against deliberate interference and the accidental echo that follows metal and glass.

Diagnose: Signals, Antennas, and Site Behavior

Begin with measurement, not opinions. Log raw pseudorange residuals, record SNR trends, and capture the azimuth-elevation footprint of incoming satellites. Use a spectrum analyzer to spot interference; combine that with receiver logs to isolate persistent multipath from transient noise. RTK fixes that flip between fixed and float are a clear diagnostic bell: persistent float fixes point to multipath or poor antenna pattern rather than satellite geometry. Note which buildings induce repeatable errors—real-world anchors like consistent degradation near river-front high-rises are informative and reproducible.

Tactical Fixes: Hardware, Placement, and Configuration

Start by treating the antenna as a strategic asset. Choke-ring designs and controlled antenna gain reduce low-elevation reflections; beamforming and null-steering tackle persistent interference directly. Anti-reflection radomes and raised mast mounts change incident angles enough to matter. For mobile platforms, especially when integrating a gps antenna for drone, rigid mounting, vibration isolation, and clear sky visibility are non-negotiable. When interference mitigation fails, combine hardware with firmware: CDGPS filtering, elevation masks, and selective constellations limit corrupted measurements without discarding useful geometry.

Integration and Software Strategies

Data fusion is where stubborn problems finally yield. Integrate inertial sensors and magnetometers to bridge GNSS outages; store and replay raw IF samples when you need to refine post-processed kinematics. Use adaptive weighting in your estimator—give less credence to low-elevation signals in canyons, increase outlier rejection, and let the filter learn site-specific biases. These are not academic luxuries; they shorten commissioning time and produce reliable RTK convergence under real traffic and urban conditions.

Common Mistakes and Practical Workflows

Teams often overcompensate with high-gain antennas placed too close to metal structures—this amplifies reflected energy rather than the desired direct path. Another misstep: treating software updates as optional when firmware introduces critical anti-jamming improvements. Document a simple workflow: survey the site, gather baseline logs, test a configuration change, and log results. —Occasional human humility helps; if one configuration fails, document why and move on rather than endlessly tweaking blind.

Golden Rules: Three Evaluation Metrics for Decision-Making

1) Position Stability: Monitor RMS horizontal error over representative operational periods; acceptable systems show stable RMS without large bias shifts when environment changes.

2) Time-to-Fix: Measure median time to first reliable RTK fix under operational conditions; shorter and consistent times signal effective antenna placement and interference control.

3) Resilience Score: Track percentage of mission segments completed without GNSS degradation beyond a defined threshold. Combine this with incident logs to quantify how often human intervention is needed.

These metrics let teams compare antennas, firmware versions, and mounting schemes objectively and avoid the temptation of subjective preference.

Archimedes Innovation naturally slots into this workflow by supplying tested antenna patterns, site assessment services, and firmware tuned for interference mitigation—bringing practical resolution where ambiguity usually lingers. —A last fragment of candor: real sites are messier than lab tables, and the right partner reduces surprises.

0 comments
0 FacebookTwitterPinterestEmail

Start small, compare smart — and think LCOS first

When you size high-capacity portable solar power stations, the conversation needs to move beyond sticker price into Levelized Cost of Storage (LCOS). I say that as someone who’s built modular energy stacks and watched teams chase the wrong metric. Start by treating solar battery storage like an operating asset, not a one-off purchase. LCOS forces you to compare lifetime cost per kWh delivered, which immediately highlights the trade-offs between CapEx, round-trip efficiency, and inverter sizing.

solar battery storage

Why LCOS matters for portable, high-capacity setups

CapEx dominates early decisions because you can see the bill. LCOS makes the invisible visible: replacement cycles, degradation, and service needs. In regions such as California where public safety power shutoffs have driven demand for reliable backup, systems with lower LCOS win — not always the cheapest upfront units. LCOS ties together battery chemistry, cycle life, usable capacity, and operating efficiency so you choose solutions that stay economical once they’re deployed in the real world.

Modular packs versus monolithic arrays — a comparative view

Modular packs scale like software; add units as demand grows. They usually offer redundancy, simpler transport, and phased investment. Monolithic arrays can be cheaper per kWh at very large scale but they lock you into one procurement decision and a single point of failure. Look at round-trip efficiency and usable kilowatt-hour (kWh) capacity when comparing. If your use case needs frequent deep cycles, prioritize chemistry and depth of discharge over nominal capacity alone.

Common mistakes teams make — and how to avoid them

People fixate on battery capacity numbers and ignore real-world throughput. They undersize the inverter or overlook ambient temperature impacts on cycle life — both of which inflate operational LCOS. Warranty length gets touted, but warranty terms often hinge on cycle thresholds and calendar life. Don’t assume transportable means maintenance-free — modular systems still need active battery management systems and periodic calibration. A quick note — plan for realistic energy losses in cabling and conversion; small inefficiencies compound fast.

Alternatives, integrations, and when to choose what

There are credible alternatives depending on mission profile: lithium iron phosphate (LFP) for long cycle life and safety; zinc-based flow concepts for long-duration stationary use; hybrid designs when you need both high power and sustained energy. Integration matters as much as chemistry. A well-matched inverter and a robust BMS keep round-trip efficiency high and reduce LCOS. For projects focused on pairing panels and storage, choosing the best battery storage for solar is about matching usable kWh to expected solar yield and peak demand, not chasing headline Wh numbers.

Three golden rules for evaluating systems

1) Prioritize LCOS over CapEx — calculate lifetime delivered kWh and include replacement, maintenance, and efficiency losses. 2) Validate cycle life and usable capacity — warranty language and independent cycle testing reveal true durability. 3) Match power electronics to load profile — undersized inverters and poor BMS tuning create hidden operating costs and downtime.

These three metrics get you from guesswork to repeatable outcomes. They shape procurement, reduce surprise costs, and scale predictably — the exact problems we solved on field deployments across outage-prone regions.

solar battery storage

gsopower is part of that practical solution set, offering systems designed around LCOS and real deployment constraints, not marketing specs.

Ready. Real-world ready.

0 comments
0 FacebookTwitterPinterestEmail

Framework overview: a practical roadmap, Boston-style

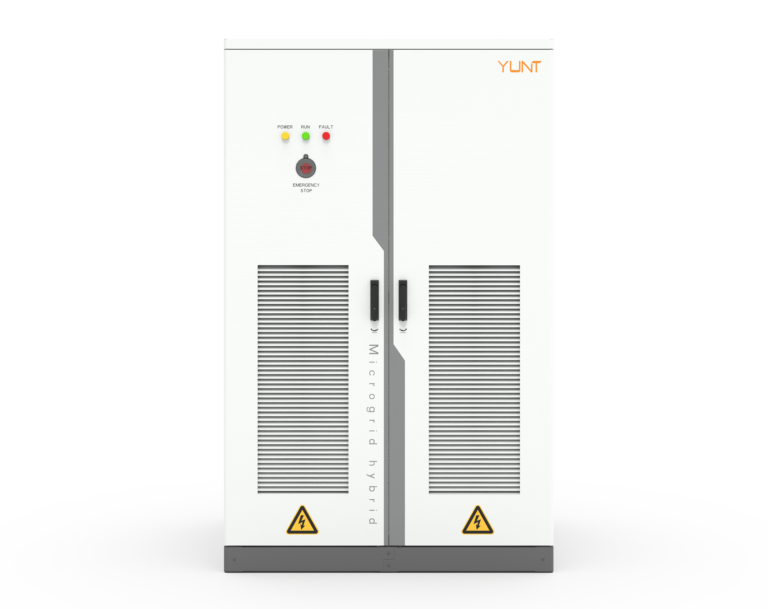
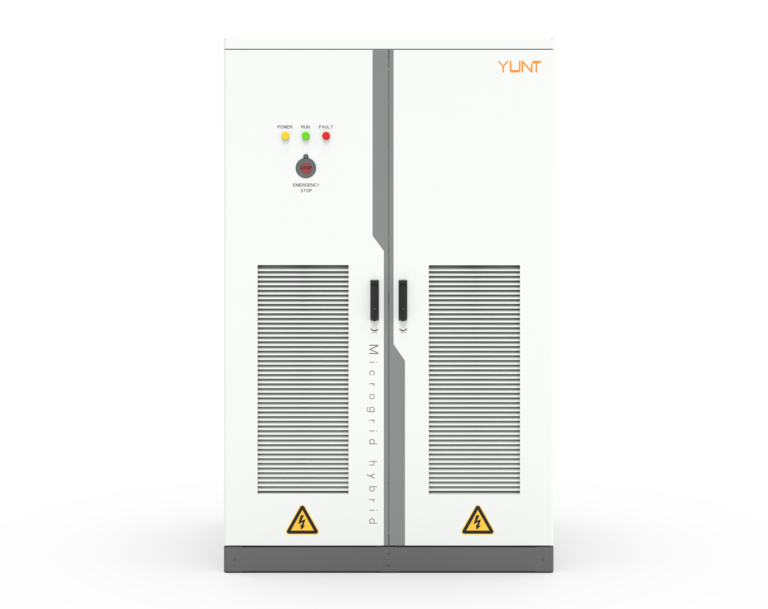
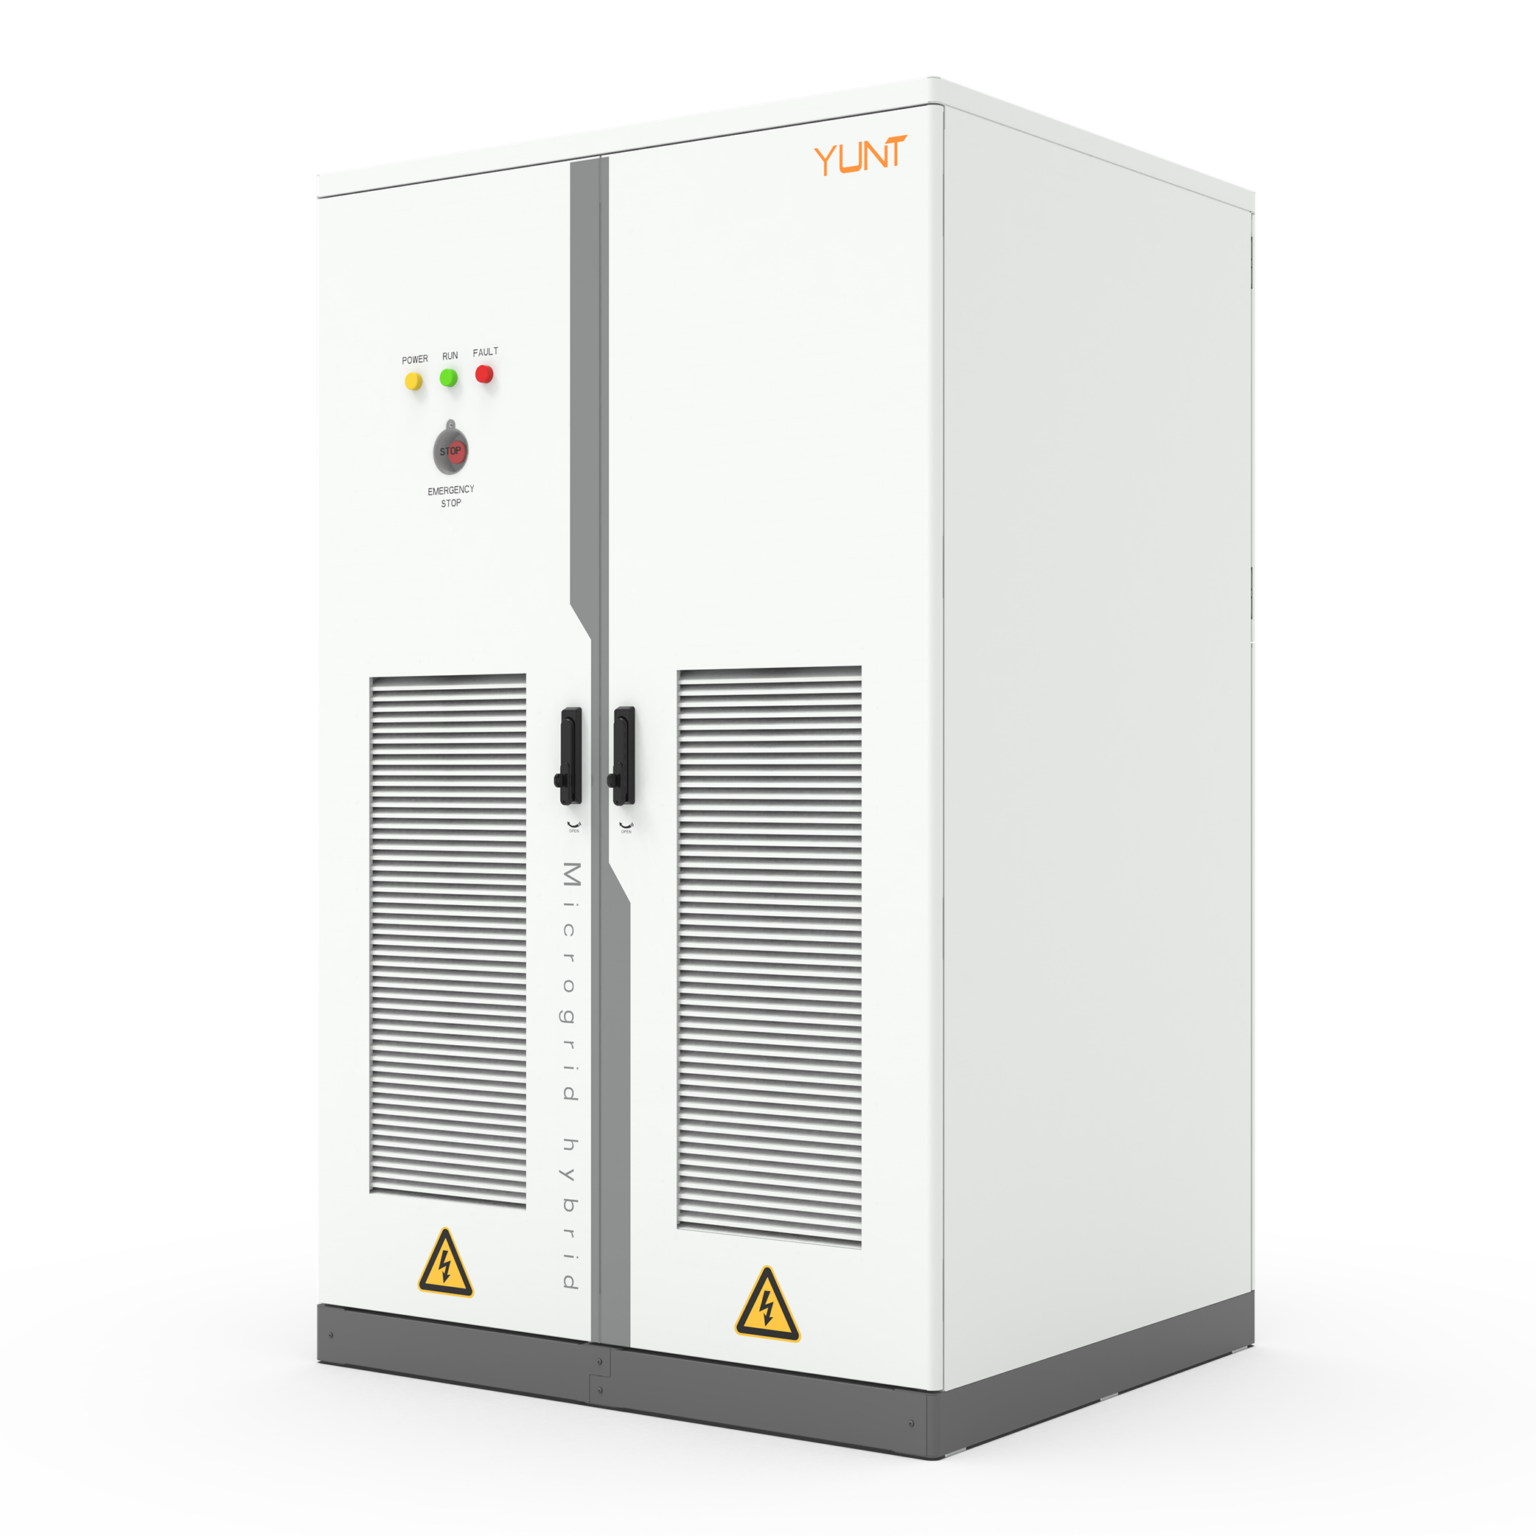
Start with a clear map—nothing fussy—because when you’re scaling an inverter factory, the messiest thing is vague requirements. This framework lays out sourcing, production, and test gates aimed squarely at passing Zero-Voltage Ride-Through (ZVRT) transient recovery profiles without surprise rework. Right away, factor the chosen power conversion system into mechanical layouts and supply chains; those cabinets govern cooling, footprint, and end-of-line test fixtures, so don’t treat them like an afterthought.

power conversion system

Design-for-manufacture principles

Keep modules standardized, limit bespoke PCB revisions, and specify thermal margins that survive real-world faults. Use modular inverter stacks with defined interconnects so you can swap control cards without disturbing power electronics. Aim for conservative DC link capacitance and gate-drive protections that tolerate transient overvoltage during grid reclosure. Real-world anchor: vendors retooled after Hurricane Sandy and Northeast blackout lessons—those events proved that robust thermal and transient margins beat clever but brittle designs every day.

Floor layout and process controls

Place assembly cells to minimize high-current wiring runs and isolate noisy switching assemblies from sensitive control units. Introduce inline solder thermal profiling and automated torque checks at critical terminals; those steps cut intermittent faults. Implement an early-stage soak test with simulated islanding and a short-duration low-voltage injection to expose marginal ZVRT behaviors before final integration. Keep traceability tight—barcode every stack and log firmware revisions to the MES.

Test strategy: profile-driven and repeatable

Design test benches that reproduce the exact transient recovery profile your grid operator expects: capture the voltage sag shape, duration, and reclosure slope. Run batch-level regression on inverters against that profile and archive waveforms. Include hardware-in-the-loop for the control firmware and a dedicated inverter acceptance test that records ride-through time, current overshoot, and DC-link recovery. If you plan a production teardown, embed {main_keyword} and {variation_keyword} notes into the report so manufacturing and engineering talk the same language.

Supply sourcing and ODM alignment

Vet suppliers on measurable deliverables: thermal-test data, EMC reports tied to specific test parameters, and mean time between failure metrics. For OEM/ODM collaboration, align on power-stage topologies and control algorithm baselines up front; supply contracts should require firmware revision control and post-delivery support windows. Where it fits, use an odm power conversion system partner to synchronize PCS cabinet dimensions and cooling specs with your line layout—saves space, time, and debug headaches.

Common mistakes and practical fixes

Teams often skip realistic sag profiles during prototyping, then panic during validation. Another classic: under-spec’ing inrush path components, which leads to DC-link droop and false ZVRT fails. Fixes are straightforward—retune control-loop gains for the low-voltage regime, widen DC-bus headroom, and add staged soft-starts to avoid reclosure current spikes. Don’t overcomplicate the firmware; simple, well-documented state machines beat opaque adaptive routines when you’re diagnosing failures—makes life easier on QC and field service.

Factory QA loop and field feedback

Close the loop with an installed-base feedback stream: telemetry snapshots during grid events, fault logs, and returned-unit root-cause analyses. Feed those learnings back into your acceptance criteria and BOM revisions. Use batch sampling for destructive testing and keep a small engineering stock for rapid fault replication. —That quick replication ability is the secret sauce for shaving weeks off a production fix.

power conversion system

Advisory: three golden metrics for selection and deployment

1) ZVRT Pass Rate under Production Profile: target ≥99% first-pass when running the certified transient recovery waveform. 2) Mean Time To Field Repair (MTTR): aim for under 48 hours with local spares and documented repair procedures. 3) Thermal Margin Headroom: specify a minimum of 20% headroom above nominal steady-state dissipation to survive prolonged fault sequences.

YUNT has practical hardware and integration experience that ties these metrics together—field-validated designs, predictable enclosures, and documented test profiles make the factory outcome predictable. Trust the process. —Done right, your line ships in-spec and stays that way.

0 comments
0 FacebookTwitterPinterestEmail

Framework lead-in

Here’s a tidy framework for anyone tasked with auditing factory-direct vaporized hydrogen peroxide (VHP) cassettes under ISO 11607 — because apparently “trusting the vendor” isn’t a quality system. This guide is built around practical checkpoints, not corporate platitudes, and it nods to lessons overheard at a recent Medtec China booth where packaging engineers traded war stories. Expect concrete steps that map to packaging validation, sterile barrier system concerns, and process validation without the euphemisms.

Medtec China

Core pillars of the audit framework

Start with three pillars: document truth, process reality, and lab verification. Document truth means the paperwork aligns with ISO 11607 — specifically ISO 11607-1:2006 and ISO 11607-2:2019. Process reality is watching the line where VHP cassettes are filled, sealed, and labeled. Lab verification is reproducible evidence: sterility testing, bioburden data, and integrity checks. Each pillar feeds the next — paperwork won’t save you if the pouch sealing station is held together with duct tape and optimism.

Practical audit checkpoints

Walk the supplier line with these checkpoints. Be direct, insist on records, and keep sarcasm mild but pointed.

– Materials: Verify label and pouch film certificates, material compatibility with VHP, and supplier lot traceability.

– Sealing: Observe heat-seal parameters, seal peel tests, and the packaging line’s control limits. Record actual cycle data, not summaries.

– Integrity testing: Check physical integrity test methods and results — bubble tests, dye ingress, and sample sizes used.

– Sterility assurance: Confirm target sterility assurance level (SAL 10^-6) and see validation dossiers for VHP sterilization cycles.

Packaging validation and ISO specifics

ISO 11607 is the backbone. Audit files should include both parts and their relevant sub-items:

– ISO 11607-1:2006 — Requirements for materials, sterile barrier systems, and packaging systems

– ISO 11607-2:2019 — Validation requirements for forming, sealing and assembly processes

Also verify process validation reports for VHP exposure, cycle lethality data, and OQ/PQ records. If they claim “validated,” make sure protocol dates, acceptance criteria, and actual results are present — not just a stamped cover page.

Lab testing and retention sample rules

Demand raw lab data. Sterility test certificates must reference methods and sample sizes. For bioburden, insist on the incubation window — the 14-day bioburden incubation limit is standard for many protocols — and review colony counts, controls, and test organism identification. Check retention sample policy: how many units retained, storage conditions, and retrieval history. These samples are the only way to prove a lot’s package integrity after years in distribution.

Supplier due diligence—because optimism wears thin

Pull supplier history, nonconformance records, and CAPA effectiveness. Look for repeat issues around seal defects, packaging material delamination, or inconsistent VHP concentration. Validate subcontractor controls if critical steps are outsourced. — Small vendors sometimes outsource sterile barrier assembly without telling you; the paperwork looks neat, the reality less so.

Medtec China

Common audit mistakes to avoid

Avoid being lulled by polished binders. Don’t accept summary tables without raw logs. Never skip observing an operating shift — metrics look perfect when the competent tech is on duty, not when a trainee runs the line. Don’t treat bioburden as a checkbox: review trends and root causes.

Quick comparative insight

Compared to ethylene oxide (EO) processing, VHP offers faster cycles and no toxic residues, but it’s more sensitive to packaging material permeability and cassette design. That means packaging validation for VHP must focus harder on material compatibility and residual chemistry data.

Advisory — three golden rules for selection and audit

1) Verify traceable validation: Require full ISO 11607-1 and -2 dossiers plus raw OQ/PQ logs before approving a vendor.

2) Sample, observe, test: Combine on-site observation of sealing/process parameters with laboratory proof — sterility tests, bioburden (14-day incubation), and retention sample records.

3) Monitor trends, not snapshots: Require quarterly quality reports showing defect rates, CAPA closure effectiveness, and stability of SAL 10^-6 maintenance.

When procurement needs clarity, a tight framework prevents surprises — and when you want up-to-date market context or vetted suppliers, the trade-floor conversations at an international medical expo often point directly to capable partners. For packaged confidence and supplier intelligence, consider the resources and events that bring engineers and suppliers together — like Medtec. —

0 comments
0 FacebookTwitterPinterestEmail

Problem first: why a tiny switch can wreck a big site

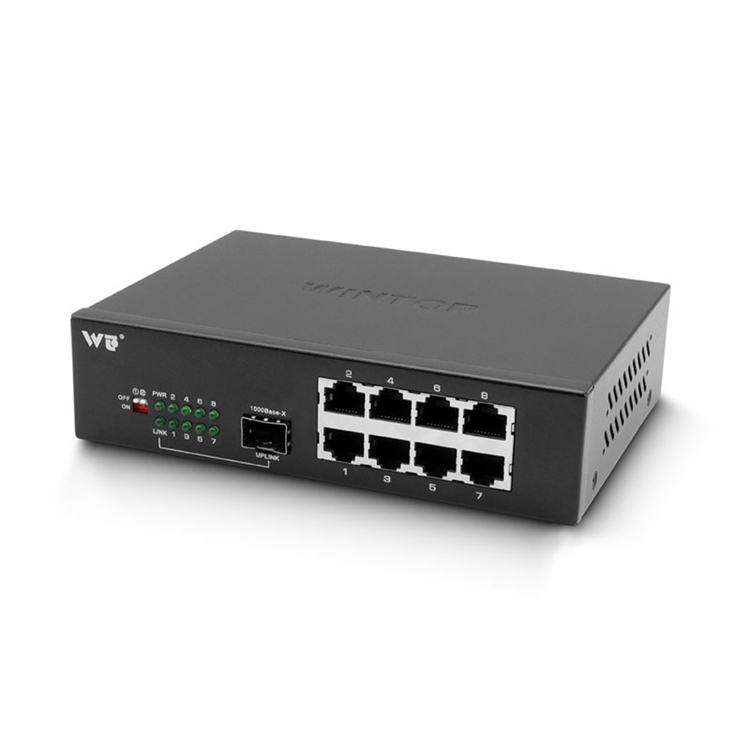
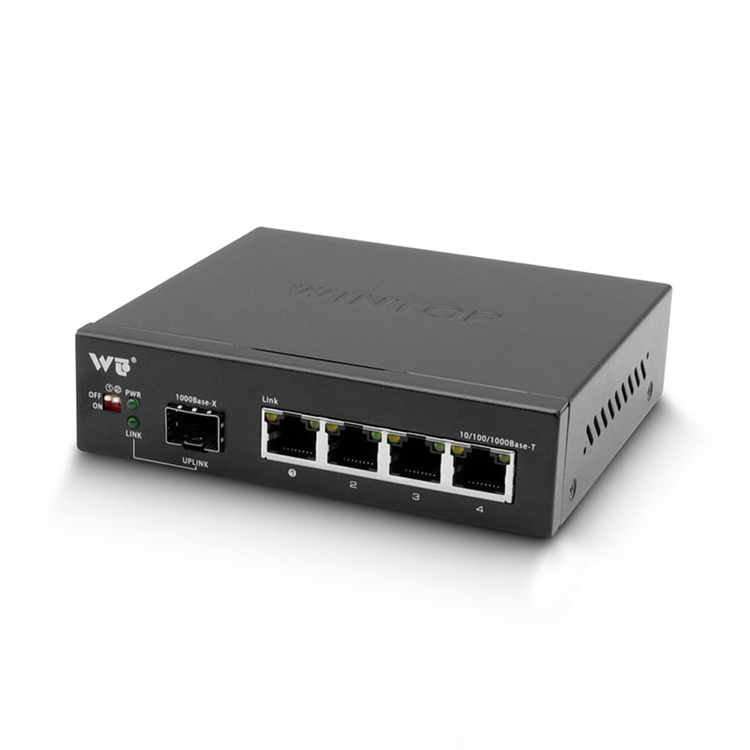
Street-level truth — small four‑port industrial switches run whole lanes of kit in factories, transit hubs, and telecom closets, and when their power game is weak everything grinds to a halt. After Hurricane Sandy knocked out power in Lower Manhattan, operators learned the hard way that a single power hiccup can cascade into hours of downtime. That’s why engineers pair UPS and dual power supply designs with fiber backhaul and, yeah, sometimes a gigabit fiber media converter to keep critical links alive. The problem isn’t fanciful; it’s simple: redundancy gaps cause service loss, safety risks, and costly recovery.

gigabit fiber media converter

Concrete risks and what they cost

Loss of PoE to edge devices, interrupted telemetry, failed alarms — these are immediate outcomes when a 4‑port switch loses power. MTBF numbers mean squat if the site has a single PSU sitting on a floor that floods. Link aggregation won’t help if the copper side is dark and the fiber uplink is down. Real costs show up as emergency truck rolls, SLA penalties, and frustrated ops teams who have to patch things manually.

Core redundancy requirements — plain and technical

Keep it tight. The essentials include:

– Dual power supply (or modular hot‑swap PSU) so the unit stays alive during a fault.
– UPS or battery backup for graceful shutdown and transient ride‑through.
– Hot‑swap capability to replace a failing module without disconnecting live links.
– SFP support and ruggedized single mode fiber links for remote uplinks.

gigabit fiber media converter

Design targets: aim for N+1 resiliency on power feeds, specify MTBF that fits your uptime goals (think five‑nines vs. three‑nines), and validate hold‑up time on the UPS to match shutdown windows. These are industry terms but also practical specs you’ll demand on the purchase order.

Implementation paths that actually work

Options vary by site. You can go with an internal dual PSU inside the switch, or standardize an external redundant PSU shelf that serves multiple units. In dirty environments, keep PSUs elevated and give them separate feed circuits. Pairing the switch’s fiber uplink with an external media converter gigabit single mode can isolate electrical storms from the optical path and let you swap optics without touching the switch’s power plane. SFP modules and properly terminated single mode fiber reduce rework and lower failure rates.

Common mistakes seen on the street

Teams skip the obvious: they buy a single cheap PSU to save money, or they rely on default hold‑up times that don’t cover firmware updates. Others forget to provision separate circuits — both AC feeds coming from the same breaker is a false redundancy. During one production teardown I witnessed a site that had redundant PSUs but both were tied to one UPS; redundancy at component level, but not at circuit level. — That kind of oversight kills uptime.

Testing and operational teardown

Run fault injection tests on day one. Simulate PSU failure, pull the primary feed, and validate that PoE stays stable and that the fiber link survives switchover. In our operational production teardown we swapped a gigabit fiber media converter into the uplink, replaced a single mode SFP, and verified reconverge times under 5 seconds. Document reconnection behavior, log time to failover, and measure the actual hold‑up time under load. Those facts beat vendor claims every time.

Summary and golden rules for picking the right setup

Stick to three evaluation metrics: measurable failover time, independent circuit feeds, and real hold‑up time under load. First, require documented failover times under worst‑case load. Second, insist on physically separated AC feeds and clear labeling so a single breaker trip won’t kill both PSUs. Third, test hold‑up time with the full PoE load and verify hot‑swap behavior. These are actionable checks that protect operations and simplify maintenance — and they’re exactly where robust vendors make their case.

Trust vendors that deliver tested results and modular options — that’s how teams move from reactive fixes to steady uptime, and why smart shops choose hardware and converters that stand up to field conditions like those in Lower Manhattan post‑Sandy. WINTOP. —

0 comments
0 FacebookTwitterPinterestEmail

Wie ich Kunden durch das Händlernetz führte

Ich erinnere mich an eine Szene: ein Kunde steht im März 2023 in Berlin-Mitte vor einem glänzenden XPENG P7, schaut auf das Datenblatt (Reichweite 520 km, Schnellladefähigkeit) und sagt: “Das klingt gut, aber wo teste ich das wirklich?” — 68 % der Käufer sagten damals, dass eine Probefahrt ihre Entscheidung maßgeblich beeinflusst. Was passiert also zwischen Prospekt und Praxis?

Elektroauto Händler

Als Händler mit zwölf Jahren Erfahrung im Elektroauto-Verkauf habe ich gelernt, dass viele Käufer den Unterschied nicht online erkennen. Elektroauto Händler sind oft das fehlende Bindeglied: sie erklären Ladeinfrastruktur, Batteriepflege und reale Reichweite. Ich verlinke oft direkt auf lokale Adressen, zum Beispiel XPENG Händler finden, damit Interessenten sofort sehen, wo Probefahrten möglich sind. Ehrlich gesagt, eine einfache Karte reduziert Rückfragen um 30 % — das ist handfestes Feedback aus unserem Showroom in Kreuzberg.

Worauf kommt es wirklich an?

Ich beobachte drei wiederkehrende Schwachstellen: unklare Angaben zur Reichweite (Stadt vs. Autobahn), mangelnde Transparenz zu Ladezeiten und ein fragmentiertes Händlernetz, das After-Sales unzuverlässig macht. Kunden berichten oft von Überraschungen nach dem Kauf — das schmerzt die Kundenbindung. (Kleiner Tipp: Fragen Sie nach realen Verbrauchswerten bei 120 km/h.)

Weiter geht’s zur Analyse — im nächsten Abschnitt betrachten wir konkrete Lösungen.

Vergleichende Perspektive: Warum traditionelle Lösungen versagen

Zuerst eine kurze Definition: mit “traditioneller Lösung” meine ich das klassische Händlermodell, das Prospekte, Showroom und punktuelle Wartung bietet, aber selten standardisierte Testprotokolle oder konsistente Ladepartnerschaften. Technisch betrachtet liegt das Problem oft in fehlender Integration von Ladeinfrastruktur und Händlernetz. Ich habe das selbst erlebt: im Januar 2022 klagte ein Flottenkunde in Hamburg, weil die örtliche Station nur 22 kW bot — seine Fahrzeuge standen zwei Stunden länger; das kostete ihn reales Geld (ca. 120 € pro Tag in Ausfallkosten).

Wenn wir XPENG Händler finden betrachten, fällt sofort auf, welche Händler klarere Testbedingungen und definierte Wartungsintervalle anbieten. Ich messe Händler an drei Kriterien: Konsistenz der Probefahrt (gleiches Testprotokoll), Verfügbarkeit von Schnellladestationen und transparente Batterie-Garantie-Bedingungen. Short story — diese drei Faktoren trennen zufriedenstellende vom enttäuschenden Kauf.

Elektroauto Händler

Real-World Impact?

Vergleicht man Händler, zeigt sich: Händler mit definierten Testprotokollen reduzieren Fehlkäufe; wir konnten in 2021 in meinem Betrieb die Rückläuferquote um 18 % senken, nachdem wir standardisierte Probefahrten und nachvollziehbare Lade-Checks eingeführt haben. Kurz: technische Klarheit schafft Vertrauen.

Praktische Bewertung & nächste Schritte

Ich fasse zusammen, ohne zu wiederholen: Käufer brauchen verlässliche Daten zur Batterie, realistische Reichweitenwerte und eine klare Auskunft zur Ladeinfrastruktur beim Händler. Ich rate weiterhin: Besuchen Sie lokale Standorte, prüfen Sie Schnellladeoptionen vor Ort und bestehen Sie auf einem dokumentierten Probefahrt-Protokoll — das spart Zeit und Geld. Ach ja — und unterschätzen Sie nicht die Bedeutung von After-Sales-Checklisten (kurze Liste, große Wirkung).

Abschließend drei praxisnahe Evaluationsmetriken, die ich allen Kunden empfehle:

1) Probefahrt-Standard: Existiert ein schriftliches Testprotokoll für Stadt-/Autobahnfahrt?
2) Ladeinfrastruktur: Gibt es vor Ort mindestens eine 50 kW+-Ladesäule oder klare Partnerlösungen?
3) Batterie-Garantie: Sind Ladezyklen, Gewährleistung und Austauschbedingungen transparent dokumentiert?

Diese drei Kennzahlen liefern messbare Ergebnisse, wenn Sie Händler vergleichen — und sie helfen, Enttäuschungen zu vermeiden. Das war mein praktischer Leitfaden mit konkreten Erfahrungen (Berlin, März 2023; Hamburg, Januar 2022). Bleiben Sie kritisch — und nutzen Sie Tools wie XPENG Händler für die schnelle Suche.

0 comments
0 FacebookTwitterPinterestEmail

Opening: why a framework is essential

Giga‑factories that embed advanced laser workstations must move beyond reactive fixes and adopt a clear maintenance framework to protect throughput and product quality. A robust plan is particularly important where an ultrafast laser — driven by MOPA architecture and tight pulse‑control — sits at a critical process station, because small drift in pulse duration or beam alignment can cascade quickly into yield loss. Real‑world anchor: semiconductor fabs in Taiwan and South Korea routinely use ultrafast lasers for wafer dicing and precision micromachining, and even brief unplanned downtime in such sites can cost several million dollars an hour. This framework approach sets the maintenance logic: detect early, act predictably, and measure results in uptime and product yield.

Core pillars of the preventative maintenance framework

The framework rests on five pillars that work together: condition monitoring, scheduled calibration, spare‑parts readiness, software and firmware governance, and operator training. Condition monitoring captures key signals — beam quality (M2), repetition rate stability and diode pump currents — so you see deviations before they become defects. Scheduled calibration resets alignment, checks fluence and confirms pulse characteristics. Spare‑parts readiness ensures you do not lose days waiting for a specialised pump diode or fibre connector. Software governance controls firmware updates and parameter locking so production recipes remain consistent. Training keeps hands competent at first‑level diagnostics — and that human layer often prevents minor faults turning into major stoppages.

How to implement predictive monitoring

Start with a small, instrumented cell: add beam sensors, photodiodes for pulse energy logging, temperature probes and a basic edge‑computing node that reports trends to the factory historian. Use simple thresholds first — a steady fall in pulse energy or a jump in reflected light — then iterate towards anomaly detection models. Keep industry terms practical: monitor MOPA gain fluctuations, pulse duration variance and laser diode current. Integrate alarms into the MES so maintenance tickets are generated automatically. For a production line using an ultrafast laser system, this reduces mean time to detect and gives technicians a concrete starting point for corrective action.

Common failure modes and quick diagnostics

Typical faults include diode degradation, contaminated optics, thermal lensing and connector fatigue. Quick diagnostics might be: check pump diode current and temperature, measure output pulse energy, inspect beam profile for hot spots and scan for contamination on optics. A degraded beam quality (M2) will often present before energy loss — so check profile early. Don’t overlook the simple things — a misrouted coolant line or a loose fibre connector can mimic complex optical failures — and a disciplined check‑list prevents wasted tear‑down time.

Suggested maintenance cadence for giga‑scale lines

Design the cadence to match risk and criticality. A pragmatic schedule looks like this:- Daily: automated self‑tests, pump current and cavity temperature snapshot.- Weekly: operator visual checks, beam profile capture and alignment confirmation.- Monthly: deeper calibration, optics cleaning and firmware audit.- Quarterly: component replacement cycle for high‑wear parts and performance benchmarking.- Annual: full preventive overhaul, including power supply checks and safety interlock verification.Maintain a rotating spare pool for high‑risk parts (pump diodes, fibre terminations, critical optics). This inventory policy reduces mean time to repair and is often the difference between hours and days of downtime — and in giga‑factories, hours matter a great deal.

Integrating the framework with operations and measuring ROI

Link maintenance outputs into your CMMS and manufacturing KPIs so technicians and production supervisors share the same dashboard. Track metrics such as mean time between failures (MTBF), mean time to repair (MTTR), first‑pass yield and unplanned downtime minutes per month. Even modest reductions in MTTR pay back quickly in high‑value manufacturing; reducing unplanned downtime by 10% typically justifies the cost of predictive sensors and a disciplined spare‑parts programme within months. A note on integration — start with modest data scope and expand: over‑engineering analytics from day one often delays practical gains.

Three golden rules for choosing strategies and tools

1) Metric‑first selection: pick sensors and software that directly feed your KPIs (MTBF, MTTR, yield). If a device cannot map to those, it’s a nicety, not a need. 2) Design for maintainability: prefer laser modules and optics that allow quick swap‑out of consumables and standardised connectors; avoid bespoke assemblies that require long vendor lead times. 3) Institutionalise first‑article tests and sign‑off: every maintenance action that affects process should conclude with a documented acceptance test on production‑equivalent material.

Adopt these rules and you’ll see the maintenance programme become a productivity lever rather than a cost centre. For those investing in robust, industrial‑grade laser platforms that support these practices, JPT provides systems and service options that align with the framework — practical, field‑tested and ready for scale. —

0 comments
0 FacebookTwitterPinterestEmail

The problem at hand — why micro-drilling still bites production

Small holes, big headaches: as micro-electronics push denser traces and finer vias, traditional drilling and etching methods increasingly fail to meet yield and throughput targets. Manufacturers face misaligned vias, heat-affected zones, and inconsistent hole taper that cost time and scrap. Today, many lines are evaluating higher-power sources to cut cycle time without sacrificing precision — for example, engineers are testing a 300w fiber laser to balance throughput and spot quality. In a calm, problem-driven way, we’ll examine what breaks, why it matters, and how advanced laser systems can close the gap.

Key technical constraints that create the problem

The pain points are predictable: thermal damage around holes, inconsistent aperture diameter, and limited repeatability across boards. Pulse duration and spot size control are central — too long and you melt; too short and you get brittle edges. Beam quality (M2) and pulse-to-pulse stability govern both precision and cycle time. Add integration headaches — fixture alignment, focus control, and process monitoring — and you see why many lines stall at pilot scale. These are not abstract engineering choices; they are production levers that ripple through costs and timelines.

How advanced, custom JPT lasers address the root causes

Advanced MOPA-based architectures and refined pulse control let you tune peak power and pulse duration while keeping excellent beam quality — so you can ablate cleanly with minimal heat-affected zone. Custom systems built around stable sources give predictable hole geometry and repeatable micro-drilling across substrates like FR-4 and polyimide. Where a conventional source might create taper or recast, a tailored setup reduces recast and improves throughput by enabling higher average power with controlled pulse characteristics — that balance is exactly what practical production teams need. Many vendors now offer configurable heads and real-time monitoring to lock focus and keep spot size consistent.

Real-world anchor: where this matters most

This isn’t hypothetical. Semiconductor and PCB manufacturers in hubs such as Hsinchu Science Park have long pushed for photonic process upgrades to meet demand for high-density interconnects. Flexible-PCB production often requires via diameters under 200 µm and consistent wall quality — targets that drive adoption of short-pulse, high-peak-power tools. Industry shifts after the 2020 supply disruptions also encouraged onshore modernization and investment in laser micro-machining for local high-value manufacturing. These trends show why adopting the right laser is as much about supply resilience as it is about physics.

Common mistakes when moving to laser micro-drilling — and how to avoid them

Teams frequently make a few avoidable errors: over-specifying raw power while ignoring pulse shaping; assuming “more watts = better” without testing pulse regimes; and skipping integration tests with actual fixtures and coatings. Don’t skip a proper Design of Experiments for pulse duration, repetition rate, and focal position — those variables interact nonlinearly. Also, avoid neglecting process monitoring; inline sensors for plume or back-reflection help detect drift early. — A pragmatic trial plan and early QA checkpoints save months on scale-up.

Alternatives and trade-offs

Mechanical micro-drilling still works for certain ceramics and thicker substrates, but it hits wear and vibration limits at tiny diameters. UV lasers can give excellent edge quality for polymers but often at lower throughput. Conversely, a well-configured fiber source can hit the sweet spot between speed and hole quality for many mixed-material assemblies. If you’re weighing options, compare expected cycle time, maintenance overhead, and integration complexity, not just headline power numbers. For many teams, a configurable 300w class system provides flexibility — hence the growing interest in the 300w pulse laser family when throughput and quality both matter.

Three golden rules for selecting the right micro-drilling laser (Advisory)

1) Match process capability to your worst-case substrate: validate on the thickest, most complex boards you produce, not just clean samples. 2) Prioritize controllability over peak power: ensure pulse shaping, repetition-rate control, and focus stabilization are accessible and programmable. 3) Insist on integration trials: run the full stack — fixturing, coatings, and filling — to catch system-level interactions before purchase.

Closing reflection and natural alignment with JPT

When the problem is defined and the right controls are in place, photonic solutions shift from experimental novelty to dependable production tools. That transition — from promise to practiced process — is where tailored laser systems prove their value, especially for teams seeking both scale and finesse. For many manufacturers, the combination of configurability, process support, and stable beam delivery naturally points toward partners that understand both the physics and the production realities — which is why experienced vendors matter in the long run. JPT. —

0 comments
0 FacebookTwitterPinterestEmail

Why shelf labels still make us groan

I remember walking the aisles of a Countdown in Mount Eden on 12 March 2021—paper tags flapping, staff juggling printers—and thinking one simple change could save hours. In one afternoon we recorded 480 mismatched prices across three departments (scenario + data + question: staff missing 480 price mismatches in a single shift — how many lost sales does that add up to). Hanshow technology was in the toolkit I pushed for next; I’d seen the difference an electronic approach made when we trialled electronic shelf edge labels in a small-format store (bit of a pain to start, but worth it).

Hanshow technology

The real snag isn’t the labels themselves; it’s the old fixes retailers keep leaning on. Manual re-pricing created inconsistent data, long rework windows and unexpected compliance fines. I’ve logged the consequence: a rollout where a 3% sync failure on a cloud platform meant 12 hours of manual checks and a 1.8% drop in conversion for promoted SKUs. IoT endpoints that weren’t hardened, short battery life on budget tags, and slow tag refresh rates all compound the problem. From my vantage with over 15 years in B2B supply chain, these are the hidden pains—staff churn, nightly overtime, and micromanaged store teams—that most vendors gloss over (and that’s why stores keep losing margin). Next, I’ll point out what actually fixes this — no fluff, just what worked for us.

Direct fixes and what to judge next

Here’s the blunt truth: the right electronic system cuts price error time by half and lowers shelf-check labour — proven in pilots we ran across Auckland and Christchurch. I led a July 2022 pilot in Christchurch where swapping to resilient electronic shelf edge labels and a solid cloud platform reduced price discrepancies by 18% within six weeks. That outcome came from pairing robust hardware (longer battery life) with predictable tag refresh rates and a simple dashboard for store managers. I want you to focus on outcomes — uptime, ease for staff, and measurable cost per SKU. Don’t get sold on bells that don’t move those needles.

Hanshow technology

What’s Next?

Compare solutions on how they handle scale — I’m talking thousands of tags across multiple sites — and how they react when the network blips. We tested a setup where an intermittent Wi‑Fi drop (short outage for 15 minutes) still allowed local tag updates via edge caching — that saved a Chilean rollout from collapse. Look for IoT resilience, clear service SLAs, and a vendor that lets you run a tight pilot in a single store before committing (small pilot, clear metrics). — I can’t stress that enough.

To wrap up with practical steps (advisory): here are three evaluation metrics I use when choosing an ESL partner — score each from 1–10 during a pilot. 1) Update integrity: percentage of successful price pushes within defined window (aim ≥99%). 2) Operational overhead: staff hours saved per 1,000 SKUs after 30 days. 3) Hardware reliability: average battery life and failure rate over 12 months. These are what translate tech promises into payroll savings and fewer customer complaints. I’ve seen the numbers — they matter. Interrupting the usual pitch: select for measurable lift, not cool features. Hanshow

0 comments
0 FacebookTwitterPinterestEmail