Category:

Tech

Framework overview

The verification process must follow a defined protocol that converts design intent into measurable acceptance criteria. Treat the prefabricated substation as a clinical specimen: define controls, baseline diagnostics, and end-point criteria before any power is applied. For factory work this means the vendor, test team, and the electrical equipment manufacturer share a single test plan that assigns responsibility for each measurement and pass/fail limit.

Scope and objectives

Define the framework boundaries: which assemblies are subject to routine tests, which require type tests, and which will be validated only by inspection and functional check. Objectives are explicit: verify mechanical integrity, validate dielectric performance, confirm protection logic, and ensure metadata (drawings, serials, and test records) match the physical unit. Every objective must map to one or more verifiable procedures and a documented acceptance threshold.

Documentation and design verification

Start with documentary control. Confirm single-line diagrams, cable schedules, terminal labeling, and bill-of-materials against the delivered unit. Cross-reference component type tests and certificates. Record deviations and determine whether they are non-conformances or acceptable variances against the contract. A verified documentation set avoids rework on the factory floor and prevents latent field failures.

Mechanical and environmental checks

Inspect enclosure integrity, door seals, fastener torque, and protective coatings. Verify alignment and mechanical clearances for switchgear interlocks and operating mechanisms. Perform ingress protection verification where specified and confirm that vibration mounting and transport restraints are present and functional. Thermal pathways must be confirmed visually and by measured temperature rise under simulated load when feasible.

Electrical routine and type tests

Execute low-voltage and high-voltage routine tests applicable to the equipment: continuity of conductors, insulation resistance, dielectric withstand where required, functional verification of load-handling devices, and verification of protection relay settings against the design curve. Measure secondary wiring integrity, instrument transformer polarity and ratio, and cable terminations. Capture both raw data and derived indicators so acceptance is a quantitative statement rather than a subjective judgment.

Protection, control, and secondary systems validation

Verify protection relay logic using staged primary injection or secondary test sets. Validate time-current coordination between upstream and downstream devices. Confirm SCADA points, telemetry mapping, and alarm thresholds by simulated events. Test auxiliary power (batteries, chargers) under load and confirm supervision channels. Record event logs and waveform captures where possible to provide objective evidence of correct operation.

Safety, earthing, and human factors

Confirm protective earthing continuity and resistance to ensuring touch potential limits are met according to the specification. Check lockout/tagout provisions, safety labeling, escape clearances, and ergonomic access for routine maintenance. Validate that safety interlocks cannot be defeated without clear, auditable action. Human factors failures are common and cheap to remediate at the factory stage compared with field retrofits.

Common pitfalls and failure modes

Expect these recurring issues: undocumented field modifications, mismatched component serials, loose secondary terminations, incorrect relay settings out of default values, and inadequate thermal management for enclosed equipment. Treat defaults as suspect until validated. Allocate time in the test plan for rework loops; often the test that fails first exposes the root cause of multiple downstream non-conformances.

Experience, authority, and a real-world anchor

I base this framework on hands-on commissioning cycles and standards-driven practice. Many projects reference IEC 61439 for switchgear assembly requirements; that standard provides objective limits and test methods used across industry. A verification program aligned with such standards and with traceable test records demonstrates expertise and reduces ambiguity when disputes arise. For industrial projects that require coordinated supply chains, clear specification of manufacturing electrical equipment and component certification is essential to ensure the unit delivered in the factory matches what will perform in the field.

Conclusion

Adopt a stepwise verification framework that ties each specification item to a concrete test and a pass/fail criterion. Use measured data, not impressions, to close out factory tests. When design intent, test evidence, and traceable component certification converge, stakeholders obtain the confidence needed for site acceptance — a practical outcome exemplified by integrated suppliers such as Daqo Group.
0 comments
0 FacebookTwitterPinterestEmail

Start with the problem — what breaks first

Operators and managers usually spot symptoms: missing equipment, late crews, surprise downtime. The problem-driven start is simple — identify the loss points and trace them to actions. For many teams, the first move is to adopt a clear fleet management solution that gives immediate location, health, and usage data; at the same time, effective iot tracking solutions must be chosen so every truck, pickup, and tow rig reports reliably. From a practical angle, what I see on audits is that problems cluster around visibility, maintenance scheduling, and human error — the kind of issues offshore platforms in the North Sea also face when logistics go out of sync.

fleet management solution

What goes wrong — short list of failure modes

– Assets are not where spreadsheets say they are, so work delays and double-dispatch happen. – Preventive maintenance is skipped because no one owns the reminder or the data is buried in paper. – Fuel and usage losses from idle time or unauthorized trips. – Safety noncompliance: missing checklists, late permits, poor crew handovers. – Data exists but is fragmented across apps, making decisions slow.

Root causes — why problems repeat

These are operational failures more than technical mysteries. Teams either lack a single source of truth, or they don’t enforce a simple standard operating procedure that ties device data to actions. Device choice without workflow design creates noise. Also, connectivity gaps and unclear ownership for alerts turn useful signals into ignored messages.

How IoT tracking and a fleet management solution fix the core problems

Match tools to the problem. Practical fixes that actually change outcomes:- Real-time location + geofencing: reduces search time, enforces route compliance. – Telemetry for engine hours, fuel flow, and battery: factual inputs for maintenance scheduling. – Driver/crew behavior dashboards: measurable coaching, not moralizing. – Automated work-order triggers: a failing sensor starts a ticket, so maintenance happens before failure. – Offline data caching: devices keep recording where connectivity is patchy and upload later. Choose features that map to the immediate failure modes you listed. For example, if fuel losses are top concern, require fuel-flow meters and tamper alerts. If crew safety is priority, require SOS and check-in rules with escalation paths. Integrations matter — send alerts to the dispatch tool your team already uses so actions happen fast.

Common pitfalls during rollout and how to avoid them

– Picking shiny hardware first: instead, define the workflow, then choose devices that fit that workflow. – Overloading users with dashboards: prioritize three KPIs per role (dispatch, maintenance, safety). – Ignoring power and mounting: rugged cases, proper mounts, and battery strategy reduce false negatives. – Skipping verification: test geofences, alarms, and end-to-end tickets before full deployment. – Forgetting change management: brief crews, get a local champion, and run short pilot lanes.

fleet management solution

Quick procurement and deployment checklist for teams

– Confirm the one or two immediate problems to solve. – Map who acts on each alert and how long they have to act. – Ask vendors for a pilot: 10–20 assets for 4–8 weeks with defined success criteria. – Require APIs or export formats for your ops tools, plus offline behavior. – Train frontline staff, then tighten rules after two weeks of observation. – Plan regular audits of device mounts, battery health, and data accuracy.

Synthesis — practical value and what to do next

Fix small, repeatable problems first. Clear ownership, a short list of KPIs, and devices that behave under rough conditions produce immediate gains. When those basics run reliably, you move from chasing incidents to preventing them; that’s the measurable change operations teams need. For many operators, the simplest step is partnering with a provider who understands field realities and integrates tracking into daily work — a pragmatic relationship I often recommend to fleets starting their first telemetry program, like those I review in stage rollouts with BSJ.

0 comments
0 FacebookTwitterPinterestEmail

Quick, user-focused opening

If you’re comparing trims, range, and service options, start with what matters to you day to day: charging, after-sales support, and whether the exact spec you want is actually reachable. For hands-on detail about factory options and trim-by-trim differences, check the official lineup and the aion ev configuration to see what combinations are listed and which are sold as packages. I keep this first because what looks good on paper often shifts once you test-fit it to your routine.

aion ev configuration

What to verify before you commit

Focus on three checks that reduce regret later:

– Confirm battery range with real-world numbers that match your commute and climate. – Ask about local parts availability for common wear items. – Verify whether software updates and navigation maps are included in the purchase or billed separately.

Make these checks part of every dealer conversation. They tell you whether the car fits your life or just your wishlist.

Support and service that actually matter

Service network size sounds neat on paper. What matters in practice is response time and stock of key consumables. When I guide buyers, I ask for two specifics: expected wait for a scheduled service appointment, and how quickly a damaged charging port or inverter part can be sourced. Availability in Mexico City is one tangible example buyers use to judge how easy future service will be.

How to choose the right configuration

Match features to scenarios. Use this quick checklist:

– Daily range needed: pick the battery and motor that exceed that number comfortably. – Charging behavior: if you rely on public fast charging, prioritize fast-charge capability over top-tier cabin luxuries. – Long-term costs: weight optional packages against expected maintenance and insurance changes.

Don’t assume the highest trim is the best value. Sometimes mid-level specs offer the best mix of range, warranty, and usable features for most drivers.

Common pitfalls buyers make

Buyers often skip the easy-to-verify items that cause friction later. Don’t fall into these traps:

– Ignoring local infrastructure: confirm chargers along your usual routes. – Overlooking software policy: will maps and driver assists keep updating? Is there a subscription? – Skipping a long test drive: short loops hide how range and comfort perform under real conditions.

aion ev configuration

Ask explicit, short questions and get written answers where possible.

Alternatives to consider

It helps to compare like-for-like. If a specific feature—say, two-speed charging or a particular battery chemistry—is the reason you’re leaning one way, list competitive models that match that single feature. Compare them on three metrics: real-world range, dealer support, and long-term ownership costs. That keeps the comparison practical rather than brand-led.

Practical next steps

Start with a short plan: narrow to two configurations, request written confirmation of service timelines from local dealers, and schedule a 90–120 minute test drive that includes highway and city time. If you want layman’s clarity on trade-offs, bring this checklist and ask the dealer to show how each configuration affects daily use. I’ve advised multiple buyers this way and it cuts decision time while reducing surprises after purchase.

Closing synthesis

Decide by matching real use to real specs: range that covers your trips plus margin, service access that you can rely on, and a clear view of software and parts policies. When those align, the configuration works for you rather than the other way around. For a final reference that clarifies factory options without hype, consult the manufacturer materials like aion ev while you finalize which configuration fits your life.

0 comments
0 FacebookTwitterPinterestEmail

Opening: Why a Framework Matters

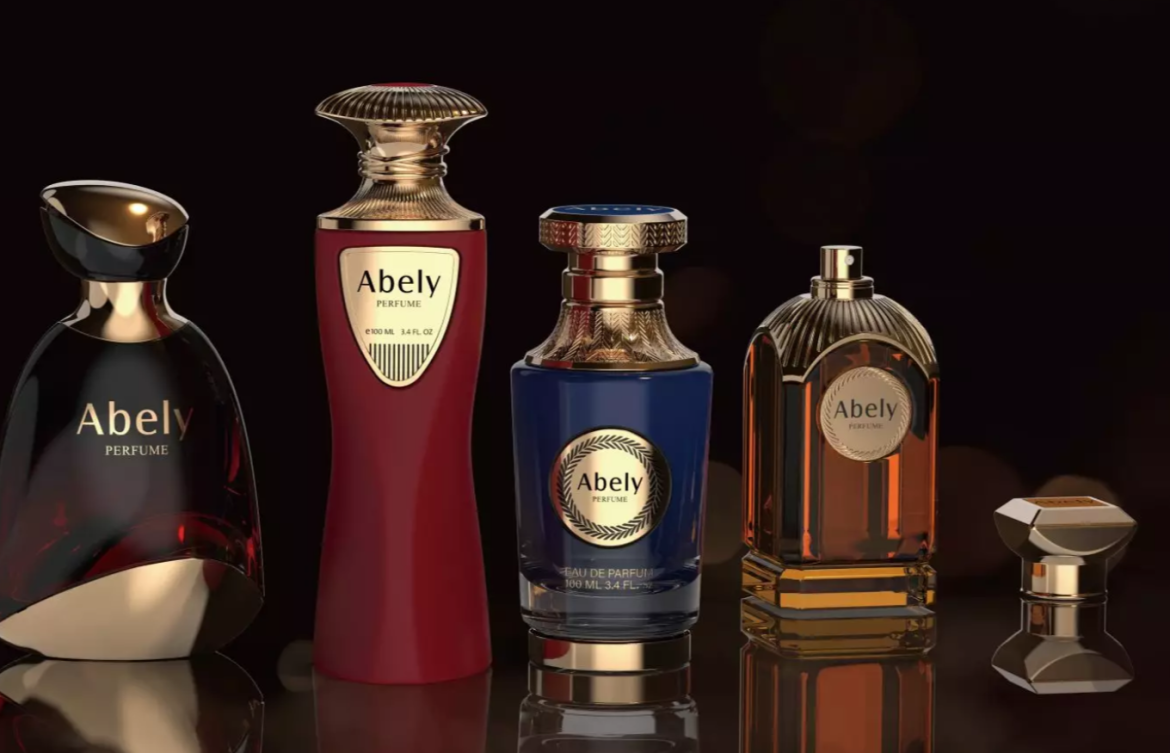
Designing a 100ml fragrance bottle isn’t just aesthetics — it’s a system. For brands building identity in crowded markets, a repeatable approach helps you iterate faster, avoid costly reworks, and scale your line without losing character. Start with the basics of perfume bottle design early in product planning so creative and supply chains speak the same language from day one.

Step 1 — Define Brand Signals

Think of the bottle as the first handshake with your customer. Ask what you want to say: heritage, minimalism, sustainability, or luxe? Pull three non-negotiable signals (shape, finish, and cap behavior) that every SKU in the line must honor. Keep choices narrow — it makes manufacturing decisions simpler and helps a contract partner translate vision into production without guesswork.

Step 2 — Technical Constraints and Materials

Match creative goals with real-world limits early: glass thickness for fill weight, UV-stable coatings, and closure tolerances matter. If you’re leaning eco, recycled glass and refillable systems require different tooling and testing. Work with a reliable perfume packaging manufacturer to validate compatibility with atomizers and filling lines — this saves weeks later on QA.

Step 3 — Prototype, Test, Iterate

Rapid prototyping is where the framework pays off. Produce a small run of prototypes and test not just looks but ergonomics, evaporation rates, and shelf impact. Bring those prototypes into real retail settings when possible — a pop-up in Los Angeles or an indie boutique will tell you more than a whiteboard ever could. These real-world anchors ground your idealized design in customer reality.

Common Mistakes Brands Make

It’s tempting to obsess over a unique cap or embossed logo — but common traps include: over-engineering expensive features that don’t add perceived value; ignoring fill-line tolerances that complicate bottling; and skipping supply-chain checks that blow lead times. Avoid these by keeping the framework’s feedback loop tight: design, supplier review, prototype, adjust.

Choosing Partners: What to Ask Your Manufacturer

Not all partners are equal. Prioritize suppliers who show design empathy, production transparency, and testing capabilities. Useful questions: Do you handle mold tooling in-house? What are your minimums for custom glass? Can you run barrier testing for fragrance stability? These specifics make contracting smoother — and yes, a good manufacturer will raise questions you hadn’t thought of.

Design Variants: When to Standardize vs. Customize

Use modular thinking. Standardize the neck and closure across your range so fill lines and caps are interchangeable, but allow two or three customizable elements (finish, color, emboss) to preserve brand variety. That balance trims costs while keeping shelf differentiation. – Smaller brands especially benefit from modularity because it lets them test new scents without retooling everything.

Quick Comparison — Common Approaches

Here’s a simple way to pick a route:

– Fully bespoke: maximum differentiation, higher cost and longer lead time.
– Semi-custom: standardized functional parts, custom cosmetic finishes — best for mid-size brands.
– Off-the-shelf: lowest cost, fastest time to market; limited uniqueness.

Summary: Pulling the Framework Together

Start with clear brand signals, align them early with technical realities, and lean on prototyping in real retail contexts. Choose partners who can translate your framework into durable production — they’re often the ones who prevent expensive surprises. The goal is a predictable, repeatable pipeline from sketch to shelf that still feels creative.

Advisory: Three Golden Rules for Evaluation

1) Cost-per-unit vs. scalability — pick a solution that lowers marginal cost as you grow. 2) Production transparency — insist on lead-time and tolerance guarantees in writing. 3) Customer-readiness testing — validate ergonomics and shelf impact in a live setting before full production. These metrics will cut risk and help you scale smarter.

For thoughtful, scalable outcomes, Abely is built to translate design frameworks into reliable production — a partner, not just a supplier. – thoughtful, not flashy.

0 comments
0 FacebookTwitterPinterestEmail

The strain we didn’t plan for

I remember standing on a gravel road outside Calgary during a January 2024 cold snap, watching technicians swap out a failed inverter while the grid demanded emergency support (it was messy, but revealing). I’d been part of projects using utility scale energy storage systems for years, and that day crystallised a problem: existing fixes—peaky diesel backup and ad hoc demand response—fail silently when you need extended, predictable support. Utility scale battery storage delivered the short-term capacity that kept frequency regulation stable, but the deeper issue was durability: a 150 MW/300 MWh lithium-ion installation I visited in March 2023 showed measurable degradation after heavy cycling—how many operators build for that reality? (I’ll come back to specific numbers.)

utility scale battery storage

Here’s a compact scene + data + question: during that cold spell, one plant supplied 200 MW for four hours, cutting regional blackouts by 90%—can traditional grid contracts absorb that kind of sudden reliability need long-term? I say no, because most procurement still values upfront price over lifecycle metrics like round-trip efficiency and useful cycle life. I’ve watched procurement teams celebrate a low CAPEX bid, only to wrestle with accelerated capacity fade and repeated inverter replacements. The hidden pain point for wholesale buyers is simple: a cheaper battery pack often shifts costs into maintenance windows and curtailed revenues later. That shortfall is the problem we need to examine before we choose the next contract or technology—so let’s look ahead.

utility scale battery storage

Designing storage for real-world use

When I recommend systems now, I focus on measurable endurance rather than marketing claims. We analyse state of charge (SOC) management strategies, thermal control plans, and supplier test data before a single contract is signed. I’ve run cell-level degradation tests in a lab in Vancouver (June 2022) and overseen field logging that proved a 5% difference in round-trip efficiency can cost a buyer thousands per MW-year in lost arbitrage and ancillary payments. So the question becomes: how do we select and price systems so those costs are visible up front?

What’s Next?

Technically, the path forward means tighter integration of asset management and procurement. I want buyers to demand three things in bids: validated cycle-life curves under realistic duty cycles, clear inverter failure-mode analysis, and warranty terms that tie to measured performance (not just nameplate claims). We now have telemetry that proves a system’s delivered capacity month-to-month—use it. I remember a utility in Nova Scotia that adjusted dispatch rules after 18 months of logged performance; that change raised real revenue by 12% the next year—small tweak, big impact. I checked the field logs — and yes, the numbers held.

Comparatively, systems priced only on CAPEX tend to underperform on net present value because they ignore downtime, replacement events, and secondary market resale value. I encourage buyers to run three simple evaluation metrics before awarding contracts: effective round-trip efficiency under expected cycling, projected remaining capacity after 5,000 cycles, and mean time between inverter failures. Those metrics expose long-term costs and make trade-offs concrete. If you want templates or a short checklist, I can share one from a March 2023 tender we ran—it’s practical and used in Alberta and Ontario sites.

To close: choose durability over sticker price, demand performance data, and align warranties with operational realities. The market is shifting; smarter bids and clearer evaluation metrics will separate reliable assets from flashing sales pitches. For vendors I trust and reference in my work, see sungrow—they show a level of documented performance that helps me make better recommendations.

0 comments
0 FacebookTwitterPinterestEmail

The problem at hand

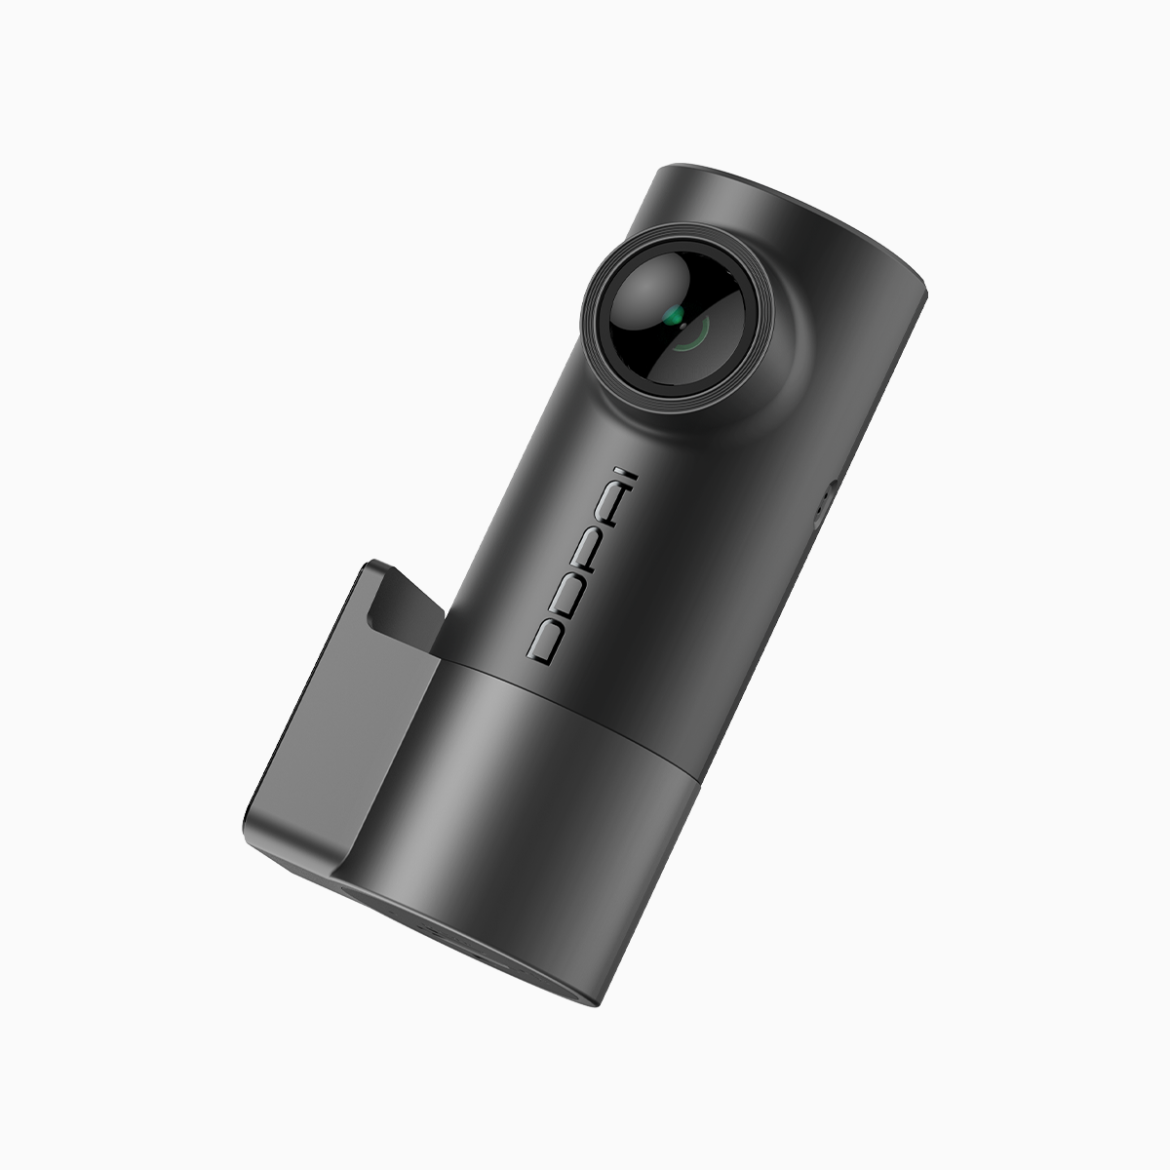
Fogged lenses and internal condensation turn a dash cam from a guardian into a blank stare—especially during the Philippine rainy season, where high dew points and persistent humidity are routine. For drivers who rely on consistent footage, poor build quality is the silent culprit. A well-designed unit addresses sealing, thermal balance and anti-fog surfaces; a poor one simply fails when you need it most. For local options and models tested for these conditions, see dash cam philippines and compare how manufacturers describe ingress protection and anti-condensation measures.

Why common specs fall short

Many vendors advertise “waterproof” or “weather-resistant” without tackling condensation. An IP rating—useful for rain and spray—doesn’t guarantee the camera can manage internal moisture driven by temperature swings. Cheap adhesives, trapped air pockets and a lack of controlled ventilation let warm, humid air migrate inside and condense on cold glass. The result is blurred night footage and warped timestamps, which defeats the whole purpose of continuous recording.

Design principles that actually work

Effective dash cams combine several thoughtful elements: a solid IP rating paired with pressure-equalization vents, a hydrophobic coating on the lens, careful thermal management of the main board, and intelligent firmware that prevents heat spikes during parking mode. Practical measures include:

– Sealing and pressure equalization: a micro-vent that lets air equalize but blocks water keeps internal pressure steady and reduces condensation.
– Hydrophobic lens coatings and anti-fog coatings: repel water and prevent tiny droplets forming a haze on the optics.
– Thermal management and materials: heat paths that avoid cold spots on the glass, plus thermal mass around the sensor to reduce rapid temperature swings.
– Firmware and connectivity: 4G connectivity and firmware updates that can tweak power profiles or heating cycles remotely, improving performance over time.

Installation, maintenance and smart choices

Even the best-designed unit can underperform if mounted poorly. Avoid placing the cam directly behind metal sun visors or in pockets where airflow is blocked. Regularly clear debris from vents and consider replacing adhesive pads that compress and trap moisture. For immediate fixes, silica gel packs in the mounting area can help—though they’re a stopgap, not a substitute for proper engineering. Visit reputable resellers and read build notes from specialists at dashcam & gadgets ph to see which models were tested under humid conditions.

Common mistakes and viable alternatives

Buyers often assume a higher price equals better condensation control—that’s not always true. Mistakes include choosing units with sealed but unvented housings, and expecting passive waterproofing to handle internal fog. Alternatives that work: external housings with controlled airflow for extreme climates, dash cams with built-in heated lens elements, or units rated specifically for high-humidity environments rather than just rain. Professional installation is a smart investment when you drive in coastal cities or mountain passes where temperatures shift rapidly—installation choices matter.

Three golden rules for selecting a dash cam for humid weather

Use these three evaluation metrics when choosing a camera for wet, muggy conditions:

– Condensation engineering: verify pressure-equalization features, hydrophobic or anti-fog lens treatments, and thermal paths in the spec sheet.
– Real-world testing and reviews: prefer models tested in high-humidity locations—Manila’s monsoon months are a practical benchmark—and pay attention to recorded night footage for haze or glare.
– Service and updates: confirm 4G connectivity or reliable firmware support; manufacturers that update power and heating profiles can fix issues without replacing hardware.

Closing thought

Choosing a dash cam that survives humidity is about measured trade-offs: solid seals plus smart vents, coatings plus thermal design, and a vendor who listens and improves. Trust solutions grounded in real conditions—and that’s where tested brands shine, offering lasting clarity on the road. DDPAI PH — reliable design that treats moisture as a design variable, not an afterthought.

0 comments
0 FacebookTwitterPinterestEmail

Centering the user: office energy problems we actually solve

Facility managers and small-business operators need predictable power, clear cost signals, and tools that reduce time spent juggling maintenance. That user focus is where Fox ESS surfaces in practical terms — see the latest updates at Fox ESS News for product notes and case highlights. Real-world pressure from events like California’s recent heatwaves has exposed how brittle some commercial setups are when solar output and load profiles shift; resilient battery storage and a reliable inverter strategy change that dynamic.

From desks to dashboards: integrating hardware with workflows

Successful office deployments treat the stack — PV arrays, inverter, battery storage, and the energy management system (EMS) — as one coordinated service. We design automation so routine tasks are scheduled, not remembered: firmware updates roll out at night, the EMS shifts load automatically to avoid demand charges, and BMS telemetry flags anomalies before they escalate. This collaborative approach reduces firefighting and gives teams useful telemetry rather than noise.

What users actually notice day-to-day

People inside the building care about comfort and reliability, not technical specs. Still, a well-tuned hybrid inverter and a smart EMS translate directly into fewer comfort complaints and lower operating bills. Installers get predictable commissioning steps, IT teams get secure API endpoints for monitoring, and finance sees tighter OPEX — everyone benefits when we automate repeatable workstreams.

Common mistakes and an operational teardown

Avoid these pitfalls: undersizing the battery for peak shaving, neglecting inverter firmware lifecycle, and treating the EMS as an afterthought. The operational teardown shows where deployments fail: poor telemetry mapping, missing load profiles during commissioning, and manual setpoints that drift over time. In one recent project we saw a 25% performance gap traced to an overlooked export limit — simple, but costly. — We corrected the control logic and regained expected throughput within days.

Comparing options: where Fox ESS stands for users

There are trade-offs across systems: some emphasize modular battery trays for fast service, others push dense energy stacks for lower footprint. Fox ESS focuses on modularity plus automation-friendly APIs so teams can script commissioning and tie the site into building management. For offices prioritizing minimal disruption and clear lifecycle cost, that mix usually wins.

Embedding the right metrics and avoiding jargon

When evaluating a solution, insist on measurable parameters: round-trip efficiency for battery storage, sustained inverter output at rated temperature, and mean time between failures for critical components. Also confirm the EMS supports role-based access and secure telemetry. For developers and operators doing an operational production teardown, explicitly map the {main_keyword} and the {variation_keyword} to system endpoints so automation scripts have reliable hooks.

Alternatives, maintenance, and lifecycle thinking

Alternatives exist, but they demand trade-offs: purely DIY stacks need more ops discipline; turnkey packages may hide upgrade paths. Prioritize systems where BMS alerts tie directly into your ticketing flow and where firmware updates can be rolled back. Scheduled preventive maintenance beats emergency repair — a simple habit that saves months of downtime over a five-year asset life.

Three golden rules for selecting office energy systems

1) Measure what matters: choose systems that publish round-trip efficiency, expected depth-of-discharge behavior, and verified uptime statistics.

2) Automate operations: require an EMS and inverter with documented APIs and secure automation hooks so you can orchestrate updates and load shifts without manual intervention.

3) Plan for service: pick modular hardware and clear replacement windows; ensure BMS telemetry matches your maintenance SLA.

These rules lead to predictable outcomes and lower total cost of ownership. Fox ESS News pulls practical examples and configuration notes into one place for teams building resilient, user-centered office systems — reliable, repeatable, and human-friendly. —

0 comments
0 FacebookTwitterPinterestEmail

Introduction: why a direct comparison matters

Large video walls demand more than bright panels; the driver board determines how those panels behave in concert. This guide compares common driver-board approaches used in corporate lobbies, control rooms and outdoor installations, and links each choice to practical outcomes. For signal routing and advanced image splicing, consider how the video wall processor integrates with your board early in the design—this alignment saves time during calibration and commissioning.

video wall processor

Core components and how they differ

Driver boards sit between the LED module and the control system. Key differences arise in the onboard memory, the number of LVDS lanes, and support for features such as pixel-level calibration. Terminology to note: pixel pitch affects perceived resolution at distance; refresh rate governs motion fluidity; and synchronization ensures frame-accurate rendering across tiles. Some driver boards include rudimentary scaling; others expect the upstream splicing processor to handle scaling and windowing. The comparative value is straightforward: boards that offload fewer tasks to the processor simplify wiring but increase cost and complexity at the module level.

Performance comparison: what metrics matter

Assess boards by four measurable attributes: latency (milliseconds between input and displayed frame), colour depth (bits per channel), thermal tolerance (operating range) and sync stability (frame alignment under load). Control-room installations prioritise sync stability; retail and outdoor signage emphasise brightness and thermal tolerance. Independent installations such as Times Square billboards demonstrate extreme cases—controllers must manage multiple tiles with robust synchronization during peak temperature swings, which is a practical anchor for expectations.

video wall processor

Real-world deployment patterns and pitfalls

Three deployment patterns recur: tightly integrated OEM solutions; modular systems using a central TV wall controller with passive driver boards; and hybrid models where a powerful splicing processor handles most image tasks. The hybrid model often offers the best balance between flexibility and maintenance. Installation mistakes repeat across projects—mismatched pixel pitch, neglected calibration and under-specced power supplies are common. Plan for calibration routines and ensure the controller and driver board share a calibration protocol—this reduces site visits later. Also expect cabling runs to complicate timing—use managed routing and labelling from the outset.

Operational teardown: where engineers should inspect

When unpacking a system, verify the firmware update path, measure sync jitter under full load, and confirm heat dissipation pathways on the driver board. A practical teardown checklist should include: firmware version, supported resolutions, connector types and diagnostic LEDs. During a production teardown, document {main_keyword} and {variation_keyword} behaviour under stress—capture logs while toggling inputs and during heavy windowing. This operational data prevents surprises when the video wall is driven at peak times.

Common alternatives and when to choose them

Alternatives vary by control architecture. Choose a centralised TV wall controller when you need fast source switching, multi-window layouts and remote management. Select smart driver boards when you require decentralised redundancy and minimal upstream processing. Consider modular splicing processors if future flexibility matters—these processors provide advanced scaling and often reduce dependence on bespoke firmware. Each option costs differently in maintenance and vendor lock-in; weigh the trade-offs against your expected service lifecycle.

Three golden rules for selection

1) Prioritise sync stability over raw feature lists—frame alignment is what users notice first. 2) Specify thermal and power margins explicitly; boards running close to rated limits will shorten display life. 3) Demand an accessible update and diagnostics path from suppliers—remote firmware and log retrieval save on-site labour.

These rules map directly to measurable procurement items: latency and sync jitter numbers, operating temperature bands, and documented remote management capabilities.

Choosing the right mix of driver board, splicing processor and controller ties directly to successful long-term operation; vendors that demonstrate field-tested solutions make a difference — Kystar.

Concise, proven.

0 comments
0 FacebookTwitterPinterestEmail

Facing the real problem

I was standing in a crowded Little India storefront last November when the promotional loop on a 55‑inch screen froze during the lunch rush — 40% of customers missed the flash sale; what practical steps will retailers take when networked displays trip up and shopper patience drops 22%? Right after that, I pulled up a trial of Smart Display Solution on my tablet and thought: this isn’t just a glitch, it’s a symptom. Digital Signage Solutions are often sold as turnkey magic, but in my 16 years fixing deployments across Singapore and Johor Bahru I’ve seen the same flaws repeat (and yes, sometimes the warranty papers don’t help — lah).

We call them ‘hidden pain points’ for a reason: mismatched CMS templates, weak media players that overheat, and OPS slot incompatibilities that show up only under peak load. Those are industry realities — content management system (CMS), media player and OPS slot issues are common — and they translate into lost minutes, lost faces, and measurable sales dips. I vividly recall a December 2022 pop‑up where a misconfigured scheduling rule wiped out midday promos; footfall was steady, conversion fell 7%. Not good, not good at all.

What’s broken?

From diagnosis to a practical roadmap

I’ll be blunt: legacy approaches focus on hardware first. I now believe the right order is software, network resilience, then hardware. Direct statement — invest in a hardened CMS and robust audience analytics before picking panels. When I architected a rollout for a regional grocer in March 2024, we swapped out an underpowered media player for a commercial‑grade unit and tightened network QoS; result: playlist errors dropped by 85% and dwell time rose 9% within two weeks. The Smart Display Solution we tested handled remote scheduling and SKU‑level targeting with less fuss than the old system — technical detail: it supported encrypted OTA updates and multicast streaming, which cut bandwidth peaks.

Compare two paths: one, you bolt on displays and hope the router holds; two, you design for observability and fault tolerance. I favour the second. We added simple health checks (ping, process watchdogs), a lightweight edge player, and centralised logging. The differences were immediate — fewer surprise reboots; less time on the phone with vendors. Also: real users prefer crisp schedules over flashy but unstable content. Short sentence. And sometimes — well — simplicity wins.

Real-world next steps?

Choosing wisely — three metrics I use

As someone who has deployed screens in hawker centres, shopping malls and a warehouse office in 2019, I use three concrete metrics when evaluating any Digital Signage Solutions. First: uptime SLA measured over 30 days (target > 99.5%). Second: mean time to remediation (MTTR) — how fast can a remote patch or rollback fix displays (aim for under 60 minutes). Third: content delivery efficiency — measured as average frame load time on a standard 4G fallback (keep under 400 ms). These are measurable, actionable, and they separate talk from delivery. I’ll add: ask for a live demo with your actual creative — not a vendor’s best storyboard — and test during peak hours. Interrupting thought: check latency now — then decide.

We must also weigh total cost of ownership: cheaper screens mean more maintenance trips. My recommendation — based on deployments across three Singapore retail chains in 2021–2024 — is to prioritise a modular Smart Display Solution that lets you swap media players, update CMS rules, and scale audience analytics without forklift upgrades. That way, you keep flexibility and reduce downtime risk. Final practical tip: pilot in one high-traffic store for 30 days and log the KPIs above; you’ll see if the system is actually steady lah or just flash.

Use these metrics. Demand those features. And when you’re ready to upgrade, talk to the specialists. Chainzone

0 comments
0 FacebookTwitterPinterestEmail

Comparative Insight — why centimeter-level positioning matters now

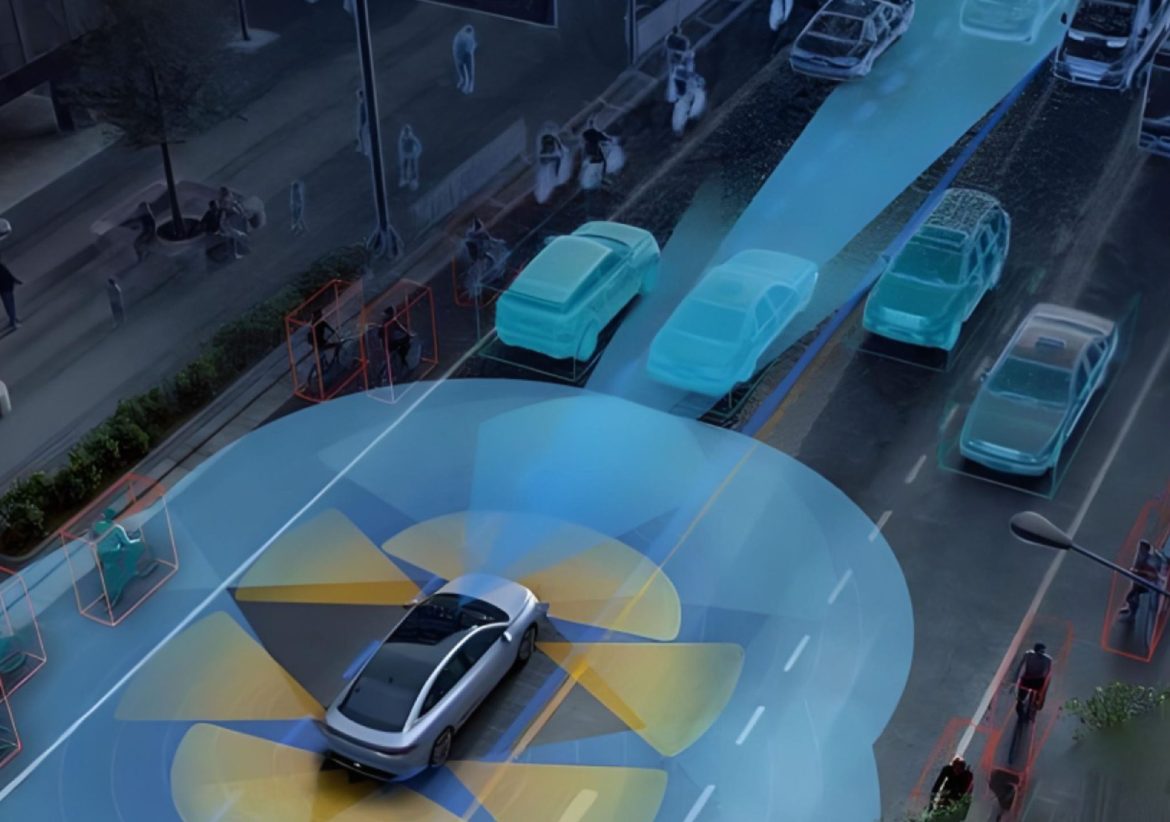
The need for centimeter-level accuracy in dense city streets is practical and measurable: survey crews in Tokyo’s Shinjuku district report large position shifts when relying on single-frequency GPS, while modern systems using RTK routinely reduce horizontal errors to a few centimeters. For teams assessing hardware choices, a clear comparison helps — and the navigation logic begins on the navigation board where design trade-offs are listed side-by-side. This article compares approaches, focusing on how a body domain controller can act as the central orchestrator for GNSS, inertial sensors, and correction streams.

Architecture differences that shape real performance

At device level, differences fall into three buckets: sensor fusion, signal handling, and correction integration. A well-designed controller pairs multi-constellation GNSS tracking with carrier phase processing and real-time inertial aiding to keep lock through building occlusion. Dual-band receivers mitigate ionospheric delays; coupling that with NTRIP correction delivery or local RTK servers yields stable centimeter fixes. The clear comparator is whether the controller treats GNSS as one input among many, or as the master clock for the solution.

Field behavior in urban canyons: expectations versus reality

Laboratory specs rarely translate directly into city streets. In practice, multipath from glass towers and intermittent sky visibility cause cycle slips and transient degradations. To overcome this, robust controllers implement continuity checks and rapid ambiguity resolution so the RTK fix recovers quickly after signal corruption. I have observed implementations where a smart controller recovered fixes within seconds after passing between narrow alleys — not perfect, but consistent enough for mapping workflows.

Common mistakes and viable alternatives

Teams often make the same errors: relying on single-frequency receivers, ignoring base station geometry, or neglecting firmware updates for ambiguity handling. Alternatives worth considering include PPP for wide-area campaigns where base stations are unavailable, and SBAS augmentation where marginal improvements suffice. Each alternative requires trade-offs: PPP reduces infrastructure needs but increases convergence time; SBAS is simple but rarely reaches centimeter class. Good controllers make these choices configurable so operators can switch modes without changing hardware.

Practical setup tips for reliable centimeter fixes

Setups that succeed share a few practical practices: stable antenna placement, correct antenna phase center models, and consistent correction input (NTRIP or local RTK). Use external antennas in dense canyons when possible, and monitor DOP and carrier-to-noise ratios to flag poor conditions early. Firmware that logs carrier phase continuity helps diagnose persistent cycle slips. Small operational steps yield outsized returns when the controller supports detailed telemetry and remote configuration.

Three critical evaluation metrics for selecting a controller

Choose devices by these metrics — they reflect real-world demands and guide procurement objectively:

– Fix recovery time: measure average seconds to re-establish RTK ambiguity after total signal blockage. A professional controller should recover in under 10 seconds in typical urban transitions.

– Continuity under multipath: assess the rate of cycle slips per hour in a representative canyon route; lower is better, as consistent carrier phase tracking sustains centimeter solutions.

– Correction flexibility: confirm support for dual-frequency corrections, NTRIP streams, and local base configurations; the controller must accept multiple correction types without firmware swaps.

Conclusion and practical anchor

For teams operating in environments like Shinjuku or Manhattan, the right body domain controller is the difference between post-processed guesswork and repeatable centimeter-level mapping. A solid design pairs dual-frequency reception with carrier phase processing, inertial fusion, and flexible correction inputs — in short, it behaves as the navigator’s trusted hub. For those seeking such integrated solutions, Archimedes Innovation offers a coherent approach that aligns system architecture with field realities. Final thought: steady hands, steady data.

0 comments
0 FacebookTwitterPinterestEmail